AI Agents Are Getting Digital Passports. But Who Checks What They Do?

Yesterday, Bookmark Conversations, the little application I’ve been building to find unexpected connections between my bookmarked articles (see more https://justme.website/content-creation/read-later-more-like-read-never-so-i-built-bookmark-conversations/), came up with something very interesting. It connected a Cloudflare article about the growing amount of automated traffic on the internet with a technical specification from SPUR, an initiative exploring how publishers can track the use of their content by AI systems.

At first, the connection seemed fairly straightforward. If AI agents are becoming increasingly active on the web, publishers need to know who these agents are and what they’re doing with their content. But the more I looked into it, the more fascinating it became. Because there are actually two very different questions here:

How do we know who an AI agent really is?

And how can we verify what it does with the information it collects?

It turns out that quite a few people are working on the first question. The second is considerably more difficult.

Could I see your passport, please?

Imagine someone walking into a library, picking up a book and introducing themselves as a researcher from a well-known university. The librarian might be perfectly happy to help. But how does he or she know the visitor really works for that university?

Something similar happens constantly on the web. Software visiting a website can identify itself through a user-agent string. A crawler might claim to be Google’s crawler, for example, or another well-known automated service. But simply claiming an identity is not the same as proving it. And as AI agents begin doing more than collecting information, this distinction becomes increasingly important. Some agents browse websites, compare products, book services or carry out tasks on behalf of users. Others collect material that may eventually appear in AI-generated answers.

So how do we distinguish a legitimate agent from software pretending to be one? One answer is Web Bot Auth, an emerging approach being developed through the Internet Engineering Task Force (IETF) (https://datatracker.ietf.org/doc/draft-ietf-webbotauth-httpsig-protocol/). Instead of simply announcing its identity, an automated visitor can cryptographically sign its requests. A website can then verify that the request was signed using a particular private key. It’s a little like replacing a handwritten name badge with a digitally verifiable identity document.

Of course, proving that an agent controls a particular cryptographic key doesn’t automatically tell us whether that agent is trustworthy. But it gives us something much more useful than a name that anybody can type into an HTTP request. Cloudflare is among the companies exploring and implementing this approach.

The surprising part: payment companies are interested too

I initially thought this was mainly a problem for website owners and publishers. But then I discovered that payment companies are working on remarkably similar questions. Visa has developed its Trusted Agent Protocol (https://developer.visa.com/docs/trusted-agent-protocol/trusted-agent-protocol-specifications), intended to help merchants recognise AI agents involved in shopping transactions. Mastercard is also exploring ways to establish what a customer has actually authorised an AI agent to do.

Here is what they are trying to do. If an AI assistant buys something on your behalf, a shop needs more than an assurance that the visitor is an AI agent. It needs to know who operates the agent, whether the agent is acting for a genuine customer and whether that customer authorised the purchase. That’s quite a different problem from identifying a web crawler. Yet the underlying questions are more or less the same: Who are you? Who sent you? What are you allowed to do? And can you prove it?

The FIDO Alliance (https://fidoalliance.org/), known for its work on authentication and passkeys, is also involved in discussions about securing interactions involving AI agents.

I find this development rather fascinating. We seem to be watching the early construction of something resembling a digital identity infrastructure for software that acts on its own. Not a single universal passport system, at least not yet. More a collection of standards, protocols and experiments that may eventually fit together.

And that raises another question I hadn’t initially considered: who will issue these identities, and who gets to decide which agents are trusted? I’d much prefer an open system in which a small independent website can verify an agent without depending entirely on a large technology company or government agency. Otherwise, we risk creating another layer of gatekeepers on the internet.

But what happens after the agent leaves?

This brings me back to the second part of the Bookmark Conversations discovery. Let’s imagine that an AI agent visits a news website. It identifies itself cryptographically. The publisher verifies its identity and allows it to retrieve an article.

So far, so good. But what happens next? Does the agent simply read the article to answer a question? Does it store a copy? Does it pass the information to another system? Does the article influence a generated answer without ever being quoted or linked? The publisher can’t necessarily see any of this. And that becomes particularly interesting when publishers want to license their content to AI companies.

Several initiatives are trying to create the infrastructure for such arrangements. Really Simple Licensing (https://rslstandard.org/) focuses on machine-readable licensing conditions. Cloudflare has been experimenting with Pay Per Crawl, allowing website owners to charge automated visitors for access (https://developers.cloudflare.com/ai-crawl-control/features/pay-per-crawl/what-is-pay-per-crawl/).

SPUR (https://github.com/SPUR-Coalition/telemetry) takes another approach. Its Content Telemetry specification describes ways to report how content moves through AI systems and how it is used. When I examined SPUR more closely, I discovered that its specification already considers verified bot identities. So the original Bookmark Conversations discovery wasn’t entirely correct in suggesting that identity verification had simply been overlooked.

But it had uncovered a much more interesting issue: Knowing who collected an article is not the same as knowing what happened to that piece of content afterwards. An AI company might report that an article was used in a particular way. But can the publisher independently verify that report? That’s where things become difficult.

A receipt isn’t necessarily proof

Suppose a publisher receives a report saying that an article was retrieved 500 times and used in 30 AI-generated answers. That’s useful information. But where did those numbers come from? If they were reported by the AI provider itself, the publisher still has to trust that provider’s reporting system. Even a cryptographically signed report only proves who signed it and that it hasn’t subsequently been altered. It doesn’t automatically prove that every relevant use was recorded.

This reminds me a little of advertising measurement. For years, advertisers and publishers have wrestled with questions about impressions, clicks, attribution and independent verification. AI introduces an additional complication. An article might influence an answer without appearing in the final response. Information might pass through several services. And the distinction between retrieving content, processing it and actually using it becomes surprisingly difficult to define.

Perhaps some of these events can eventually be recorded in independently auditable systems. Perhaps trusted execution environments, cryptographic proofs or third-party measurement services will play a role. But none of these approaches should be mistaken for a complete solution. Proving what happened inside a complex AI system is very different from proving that a particular computer sent a particular HTTP request. And I suspect this distinction will become increasingly important as the market for licensing content to AI companies develops.

Two pieces of a much bigger puzzle

Interestingly, these developments are coming from different corners of the internet. Security researchers are thinking about cryptographic identities. Payment companies are working on agent authorisation. Publishers are experimenting with licensing and usage reporting. Internet standards organisations are trying to make sure the underlying technologies can work together. They aren’t necessarily building one coordinated system. But they are encountering different parts of the same problem.

The internet is gradually filling with software that can act on behalf of people and organisations. We need ways to recognise that software, establish what it is allowed to do and hold it accountable for its actions. A digital passport may help with the first part. It doesn’t automatically solve the last. And there is a rather uncomfortable possibility here: we might eventually become very good at identifying the AI agents that visit our websites while remaining surprisingly dependent on their operators to tell us what happens to our content.

One discovery, quite a few new questions

I like that this whole line of thought began with two bookmarks that decided were related. The application didn’t provide a definitive answer. In fact, one part of its original interpretation needed correcting after I checked the sources. But that’s fine. I didn’t build it to deliver unquestionable conclusions. I built it to notice connections I might otherwise miss and give me something worth investigating.

And this one certainly did. I started with a question about a technical specification for AI content telemetry. I ended up wondering whether we’re witnessing the birth of an identity system for autonomous software, and whether the people creating the content these systems consume will ever be able to verify how that content is used. And get paid for it. Not bad for a couple of bookmarks that might otherwise have remained in my read later collection forever.

Why Are People Building Websites for Computers from the 1990s?

Imagine switching on a thirty-year-old computer, connecting it to the internet, and discovering that you can still create a website, read an online magazine, sign someone’s guestbook, or chat with other people. Not by visiting an archive of long-forgotten websites, but by using services that people are actively developing today. Why would anyone build something like that in 2026?

That was my first thought when I started exploring Web1.0Hosting (https://web1.0hosting.net/). It is a hosting service designed specifically to make websites accessible from old computers, operating systems, palmtops, and even mobile phones from a time when smartphones didn’t exist. You can use it with modern equipment too, of course. But the fascinating part is that modern equipment isn’t a requirement.

The service provides free hosting space, simple tools for building websites, webmail, chat, guestbooks, and other features that were once perfectly ordinary parts of the internet. It even supports WAP, the technology that allowed early mobile phones to access simplified online services (https://en.wikipedia.org/wiki/Wireless_Application_Protocol). And this isn’t just some experimental project with three websites maintained by a handful of nostalgic computer enthusiasts. At the time of writing, Web1.0Hosting reports hosting more than 2000 websites.

I find that quite remarkable. Here we are, living in an age of artificial intelligence, increasingly sophisticated web applications, enormous cloud platforms, and websites that sometimes seem to require a small supercomputer just to display a few paragraphs of text. Meanwhile, someone is deliberately building a hosting service that works on a computer from 1995.

But the more I explored, the more I realised that this isn’t really a story about old computers.

An online magazine that doesn’t believe in endless upgrades

One of the projects associated with Web1.0Hosting is ELPiS Magazine (http://elpis.ws/), a small digital publication devoted to Web 1.0, the small web, the indie web, and other interesting corners of the internet. ELPiS published its first issue in October 2024 and has since developed into a continuing publication. The magazine looks refreshingly old-fashioned, with a simple layout, straightforward navigation, and pages that work on old as well as modern computers.

What caught my attention was the philosophy behind the magazine. Its creator explains that technological development doesn’t necessarily have to mean constantly upgrading software, replacing hardware, or adding more complexity. Instead, people should be able to choose the technologies that actually work for them, rather than simply accepting whatever the technology industry decides they ought to use.

It’s a rather different way of thinking about technological progress. Usually, we discuss technology in terms of what comes next: faster processors, more capable AI systems, new software platforms, and additional functionality. We rarely ask whether we actually need all those improvements. ELPiS raises that question without suggesting that everyone should abandon modern technology and retreat to an old computer in the attic.

There is another aspect of this magazine that I particularly like. In issue eight (https://elpis.ws/cgi-bin/cms/zine_may_25), the creator explains that there is no real editorial plan. Articles appear because someone feels the need to write them. The magazine doesn’t seem particularly concerned with publishing schedules, audience growth, or turning every article into a commercial opportunity.

I recognise something of my own approach to Just Me in that. I started this blog because I enjoy writing about things I discover and find fascinating. Whether a post attracts five readers or five hundred isn’t really the point. Writing it, exploring the subject, and perhaps sharing something interesting with another person is already rewarding. And apparently, there are more people who think that way.

The return of the handmade website

Following the links from ELPiS and Web1.0Hosting leads to a surprisingly lively world of people building their own websites. There is Neocities (https://neocities.org/), for example, where people create personal websites, often using relatively simple HTML and CSS. And there is Nekoweb (https://nekoweb.org/), another platform that encourages people to build and customise their own little pieces of the internet.

Some of these websites look as though they have travelled directly from 1997. Colourful backgrounds, animated GIFs, tiny buttons, strange navigation menus, and pages devoted to subjects that would probably never survive a professional website design meeting. Others are surprisingly elegant, minimalist, and modern. What they have in common is that their creators appear to enjoy the process of making something themselves.

A website can be about someone’s favourite computer game, a collection of photographs, an obscure musical genre, a fictional world, or absolutely nothing in particular. It doesn’t have to attract visitors, generate advertising revenue, or become part of a larger business. And it certainly doesn’t have to please an algorithm.

Something else caught my attention here. On 24 October 2026, a new magazine called INDIEWEB (https://indieweb.nekoweb.org/articles/welcome-to-indieweb/) published its first article. It is devoted to what the editors call the hand-built web. They explain that they kept discovering wonderful personal websites but didn’t have a good place to share them. So they created their own publication.

The magazine celebrates the sort of things that have largely disappeared from mainstream web culture: hand-coded pages, guestbooks, webrings, pixel art, and those tiny 88×31-pixel buttons people once used to link to their favourite websites. It even has an edition that readers can browse online or print and turn into a physical zine.

That last detail made me smile, because I’ve recently been exploring the world of zines (https://en.wikipedia.org/wiki/Zine) myself. Small, independently produced publications are still very much alive, and apparently the people rediscovering the handmade web are also rediscovering ways of publishing that existed long before the internet.

These worlds seem to overlap quite naturally. Both are about making something yourself, sharing it with others, and finding satisfaction in the process rather than measuring success in terms of audience size or commercial potential.

Sometimes an old protocol is enough

The deeper I went into this world, the more familiar names I encountered. For example, ELPiS publishes articles about Gopher (https://gopher.floodgap.com/), the internet protocol that predates the widespread popularity of the World Wide Web. I’ve written about Gopher before on Just Me, partly because I find it fascinating that people are still actively using and maintaining such a simple system for distributing information.

There is also Gemini (https://geminiprotocol.net/), a much newer protocol designed to provide a deliberately lightweight alternative to the complexity of the modern web. Gemini isn’t intended to replace everything the web can do. It focuses on something much simpler: reading, publishing, and navigating information without the enormous technical machinery that often accompanies modern websites. I’ve explored Gemini on Just Me as well (for example here: https://justme.website/tech/there-is-more-to-the-internet-than-the-web/).

Gopher and Gemini aren’t identical, and neither is simply an attempt to recreate the internet of the 1990s. But both demonstrate something interesting. You don’t necessarily need JavaScript frameworks, elaborate user interfaces, tracking systems, or enormous software platforms to share information with other people. Sometimes a document and a link are sufficient.

Of course, that simplicity has limitations. There are excellent reasons why today’s web supports rich applications, interactive services, accessibility features, and multimedia experiences. Nobody seriously needs to suggest that we should give all of that up. But perhaps we have become so accustomed to increasing complexity that we’ve stopped questioning whether it is always necessary. Why should a page containing a thousand words of text need so much technology?

And then Yggdrasil appears

One of the more unexpected details of Web1.0Hosting is that websites hosted on the service are also published through Yggdrasil (https://yggdrasil-network.github.io/). That was a familiar name. I’ve already written about Yggdrasil on Just Me, and I certainly didn’t expect to encounter it again while exploring websites designed for thirty-year-old computers (for more on Yggdrasil, see here: https://justme.website/tech/what-if-your-friends-were-your-cloud/).

Yggdrasil is an experimental decentralised networking project. It allows computers to connect through an encrypted, peer-to-peer routing system. The project explores ways of building networks that don’t depend on the same centralised routing structures we generally associate with the internet. It is important to distinguish this from anonymity networks such as Tor. Yggdrasil isn’t designed to guarantee anonymity. Its primary focus is decentralised networking and routing.

Now consider what Web1.0Hosting is doing. On the one hand, it supports browsers and devices from the 1990s. On the other, it makes websites accessible through an experimental decentralised network. Old and new technologies, working together.

I think that’s a particularly revealing combination. These people aren’t necessarily trying to return to the past. They are quite happy to experiment with new technology. They just don’t accept that new technology must automatically replace everything that came before it. They are choosing which technologies make sense for the things they want to do.

And that, I suspect, is the more important story here.

Perhaps this is about changing our expectations

The more I explore these projects, the more I get the impression that something broader is happening. Not necessarily a large, organised movement and certainly not a revolution. The people building personal websites, publishing small magazines, experimenting with alternative internet protocols, and keeping old computers online have different interests and motivations. Some are motivated by nostalgia. Others enjoy the technical challenge. Some care about privacy, independence, accessibility, or reducing the resources needed to run digital services. And some simply enjoy making things. But many of their activities point towards a similar idea.

At the same time, people are beginning to reconsider not just which digital technologies they use, but what they expect those technologies to do in the first place.

We have become accustomed to the idea that digital services should continually grow. More features, more users, more automation, more personalisation, more integration, more engagement. A personal website should become a professional publication. A small community should grow into a platform. A useful application should acquire dozens of additional features. And sooner or later, almost everything is expected to become a business.

But what if someone doesn’t want any of that? What if a website with twenty regular visitors is exactly what its creator wants? What if a digital magazine doesn’t need a publishing strategy? What if someone prefers a simple text-based service because it does precisely what they need? Or what if an old computer is still useful and enjoyable, even though the technology industry stopped supporting it twenty years ago?

I find those questions increasingly interesting. They also connect with other things I’ve been exploring on Just Me. Communities built around personal websites rather than social media platforms. People exchanging zines simply because they enjoy sharing their ideas. Alternative ways of discovering interesting websites without relying on recommendation algorithms. Even people deliberately choosing devices and applications that do less rather than more. Individually, these may seem like unrelated hobbies or technical experiments. Taken together, they suggest a different relationship with digital technology.

Smaller doesn’t necessarily mean worse

There is a temptation to romanticise the early internet. I occasionally fall into that trap myself. But the internet of the 1990s wasn’t some perfect digital paradise. Connections were slow, websites were frequently broken, finding information could be difficult, and many services were inaccessible or frustrating to use. And let’s not pretend that every personal website was a masterpiece of thoughtful design. Some were practically impossible to read.

Today’s web has brought enormous improvements, and I wouldn’t want to lose them. Nor does a simple website automatically mean a more accessible, secure, or privacy-friendly website. Those things still require careful decisions.

What interests me is something else. The people behind these projects seem unwilling to accept that technological progress can only move in one direction. They are experimenting with the possibility that less functionality might sometimes be enough, that small communities can be perfectly satisfying, and that older technologies can remain valuable alongside newer ones. Perhaps a website doesn’t need to do everything. Perhaps it doesn’t need to grow. Perhaps it doesn’t even need an audience. And perhaps the freedom to make those decisions is a form of digital autonomy that deserves more attention.

The internet is still (once again?) a place to experiment

I started this little exploration wondering why anyone would build a hosting service for computers from the 1990s. I’ve ended up thinking about something much bigger. We talk a great deal about digital autonomy in terms of governments, cloud providers, infrastructure, legislation, and the dominance of large technology companies. Those are important discussions, and I follow them closely in my professional work.

But there is also a much more personal version of digital autonomy. It is the freedom to build a website that looks exactly the way you want it to look. To publish something without worrying about how many people will read it. To continue using a piece of technology because you like it, rather than replacing it because someone has decided it is obsolete. And to experiment with ideas that might never become commercially successful or technologically fashionable.

I don’t know whether the small web will grow into something much bigger. Perhaps it will always remain a collection of relatively small communities, maintained by people who enjoy doing things differently. That would be perfectly fine too. In fact, I suspect many of them would prefer it that way. After all, not everything on the internet needs to become the next big thing. Sometimes a small website is all you need.


(And for those wondering who the young woman in the illustration accompanying this blog post is… Yes, that’s Mara! She’ll be back this weekend with another blog post of her own here on Just Me.)

What If AI Paid for Information Instead of Articles?

A few new developments suggest that the idea of paying journalists and publishers for the information AI uses is becoming a little less theoretical.

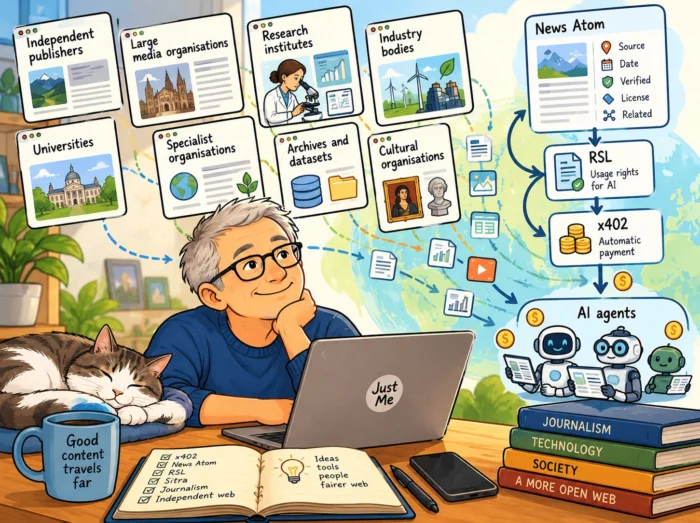
Last week, I published a rather long post called What If AI Had to Pay for the Web It Reads? (https://justme.website/content-creation/what-if-ai-had-to-pay-for-the-web-it-reads/) In it, I explored several initiatives that might eventually help journalists, publishers and other content creators get paid when AI systems use their work. We looked at x402, a protocol that allows software to make payments automatically, and News Atom, which proposes making individual pieces of journalistic information understandable to machines. I also discussed Sitra’s experiment with a marketplace for licensing journalistic content to AI developers, along with initiatives such as RSL, Cloudflare, TollBit and SPUR.

Although these projects approach the problem from different directions, they all touch on the same question: if AI companies increasingly depend on information produced by others, shouldn’t some of the money they make find its way back to the people who created that information?

A few interesting developments have emerged since I wrote that post. One new research paper in particular caught my attention because it takes the discussion beyond simply paying for access to articles. Instead, it asks how we might determine the economic value of the information contained in those articles, and how that value should be distributed among the people and organisations responsible for producing it.

What exactly are we paying for?

On October 21, a group of researchers published a paper titled Paying for Information, Not for Clicks: A Block-Level Publisher Content Marketplace for AI Answers (https://arxiv.org/abs/2610.30324). The title almost says it all. Rather than paying publishers for website visits or even for access to complete articles, the researchers propose a system in which publishers receive compensation for the actual information that contributes to AI-generated answers.

They introduce the idea of lego blocks: individual pieces of information, such as facts, figures, observations or statements. An article might contain dozens of these blocks, and several publications might contain the same information. The challenge is determining who should receive compensation when an AI system uses one or more of those blocks.

Imagine a journalist discovering that a major technology company is planning to build a new data center in the Netherlands. The journalist investigates the project, verifies the information and publishes an article containing details about its location, investment, power capacity and expected completion date. A few hours later, other publications report the same news. Some add useful information of their own, while others largely repeat the original reporting.

Now imagine someone asking an AI assistant how much capacity the planned data center will have. The assistant retrieves several articles, combines the available information and produces an answer. Who should get paid? The publication that originally discovered the project? Every publisher whose article was consulted? Or only those publications that contributed information the AI could not have obtained elsewhere?

These are not merely philosophical questions. They determine how money might be distributed in a future marketplace for journalistic information.

Three ways to divide the money

The researchers developed a framework for comparing three approaches to distributing payments. The first divides the payment equally among publishers that provide the same information. The second rewards the publisher that reported the information first. The third considers how indispensable a particular contribution was. If removing one source would make certain information unavailable, that source receives more credit.

I find the second and third approaches particularly interesting because journalism is about much more than publishing information. A substantial part of its value comes from discovering things that weren’t previously known, checking whether claims are accurate and adding context that others have missed. If an original investigation costs thousands of euros while repeating its findings takes ten minutes, should both activities receive the same compensation?

There is, however, an important complication. The publication that reports something first is not necessarily the one that reports it most accurately. Another journalist might later discover that the original information was incomplete or even incorrect. Rewarding originality makes sense, but accuracy, verification and corrections should remain part of the equation.

The researchers tested their framework using AI-generated answers to 1974 search queries concerning a heavily covered news event. Their results suggest that the method used to distribute payments can make a measurable difference. Under an equal-sharing model, established publishers with substantial news-gathering operations received 42% of the allocated value. When the model rewarded first publication, their share increased to between 46% and 50%, depending on how publication times were interpreted.

Another finding may be even more significant. When researchers examined only the articles retrieved by an AI system for a particular question, many pieces of information appeared unique. Determining who originally published something required a much broader record of the available journalism. A fair payment system might therefore need a shared information index that knows not only what information exists, but also where it first appeared and how it subsequently developed.

Remember News Atom?

That sounds like quite an undertaking. But it also reminded me of something from my previous post. In that post, I discussed News Atom (https://reutersinstitute.politics.ox.ac.uk/introducing-news-atom-metadata-blueprint-journalism-age-ai), a proposal developed by journalist Sannuta Raghu. The idea is to make journalism understandable to machines without losing the information that gives it credibility. An individual piece of information could carry metadata describing its source, publication date, verification status, context and licensing conditions.

Now consider that alongside the new research. News Atom addresses how journalistic information might be represented and described, while the researchers are asking how its economic value could be attributed and distributed. These are different problems, but they fit together rather nicely.

Imagine a future system in which an AI agent can identify a particular piece of information, determine where it originated, establish whether it has been verified, understand the licensing conditions and pay for using it. If several publishers contributed to that information, the payment could be distributed according to an agreed set of rules. That would be very different from today’s situation, where AI services can produce answers based on numerous sources while the original creators may receive little more than a citation, if they receive one at all.

Of course, there are still enormous practical difficulties. Who maintains the shared information index? How do we identify two statements that express the same fact in different words? How do we distinguish original reporting from repetition? And who decides which publisher made the most valuable contribution?

There is also a legal distinction worth remembering. Facts themselves are not necessarily protected by copyright. The commercial value may instead lie in the reporting, verification, structured datasets and services that make those facts available. The research doesn’t solve all these problems, but it does provide a framework for examining them.

What interests me most is that we are beginning to look beyond the traditional article as the basic unit of journalism. Perhaps the information gathered and verified during the reporting process has an economic value of its own, even when it is used outside the article in which it originally appeared.

Mastercard is teaching AI Agents to pay

While researchers are investigating how to value information, payment companies are developing the technology that might eventually allow AI systems to purchase it.

On October 20, Mastercard demonstrated Agent Pay for Machines (https://www.mastercard.com/global/en/news-and-trends/press/2026/october/Mastercard-Agent-Pay-for-Machines-in-action.html), a payment system that builds on x402. The demonstration took place during Cloudflare Connect, an event organised by Cloudflare. It showed how an AI agent could discover digital services, pay for them and continue working without requiring human approval for every transaction.

In the demonstration, a marketing agency asked an AI agent to help prepare a campaign for a protein bar. The agent purchased social media research from one provider and generated eight campaign images through another. In total, it completed nine payments involving two suppliers, all within an approved budget.

The system uses digitally signed payment vouchers, allowing transactions to be grouped and settled later rather than processing every tiny payment individually. That is important because handling thousands of micropayments separately could become expensive and inefficient. Mastercard has also opened an Early Access programme for developers interested in experimenting with the technology.

The demonstration had nothing to do with journalism, of course. But imagine replacing the social media research provider with a specialist news database, an independent research publication or a service offering verified information about industrial technologies. An AI agent researching a particular subject could purchase exactly the information it needs, without requiring a subscription or a separate commercial agreement with every provider. That is essentially the idea behind x402, but the Mastercard demonstration shows how the concept might become part of a broader payment infrastructure.

It doesn’t prove that AI companies will start paying journalists, nor does it mean the technology is already widely available. But it does make machine-to-machine payments considerably more tangible. And when you combine that with research into information-level compensation, you can begin to see how the different pieces might eventually fit together.

But who actually controls the content?

There is another side to this story, and it is considerably less encouraging. While researchers and technology companies are developing ways to pay for information, publishers are still arguing with major platforms about whether their content can be collected and used without permission.

The latest example involves Meta. In October, the company introduced revised commercial terms that raised concerns among publishers and legal experts. The original wording appeared to give Meta broad permission to collect content from websites linked to business accounts using Meta’s services and to use that content to develop or train its products.

Meta subsequently changed the language, removing explicit references to training. Critics argued, however, that the revised terms still left too much room for the company to collect and use publishers’ content. Publishers and advertisers in Europe and the United Kingdom asked competition authorities to intervene, and on October 23 Meta postponed the introduction of the new terms from October 30 to November 20.

Meta disputes the criticism. The company says the changes do not grant new rights to scrape websites and that website owners can continue using robots.txt to communicate their preferences. The dispute is described in more detail by Nieman Journalism Lab(https://www.niemanlab.org/2026/10/meta-delays-rollout-of-terms-that-would-allow-broad-scraping-of-news-sites-legal-experts-are-still-skeptical/).

I find this development interesting because it illustrates how far we still have to go. On the one hand, we are discussing sophisticated systems that could identify individual pieces of information and compensate the people who produced them. On the other, publishers are still trying to establish something much more basic: who gets to decide how their content is used? Without clear agreements about permissions and licensing, payment technology alone won’t solve much.

A marketplace needs more than a payment button

In my previous post, I also discussed the Finnish innovation fund Sitra (https://www.sitra.fi/en/articles/ai-can-create-new-business-opportunities-for-media-a-pilot-project-tests-the-marketplace-concept/), which is experimenting with a marketplace for journalistic content. The idea is that publishers could collectively make their information available to AI developers under agreed licensing conditions.

That could be especially interesting for smaller publishers. A large newspaper might be able to negotiate directly with an AI company, but a small specialist publication probably cannot. A shared marketplace could make its information discoverable and commercially accessible alongside content from hundreds of other publishers.

The new research suggests that such a marketplace might eventually need to do more than simply sell access to articles. It could also require information about where particular facts originated, whether reporting was original or repeated, and how payments should be distributed when several publishers contribute to an AI-generated answer.

That brings us back to the initiatives discussed in my earlier post. News Atom could help describe the information, while RSL (https://rslstandard.org/) could communicate licensing conditions. SPUR (https://www.spurcoalition.org/) is working on standards for tracking how publishers’ content is used, and x402 and related payment systems could handle transactions. Marketplaces such as the one Sitra is exploring could connect buyers and sellers.

None of these initiatives currently forms a complete, integrated solution, and there is no guarantee that they will eventually work together. Nevertheless, I find it fascinating that different organisations are beginning to address the separate components of what could become a new economic infrastructure for journalism.

There is also a question of scale. A marketplace might make sense for large news organisations with extensive archives, but could it also work for independent journalists, small specialist publishers, research institutes and other organisations that produce valuable information? That is where I think the real opportunity lies. A market that only benefits the largest publishers would do little to change the existing balance of power. A system that allows smaller content creators to participate on reasonable terms could be considerably more interesting.

And what about the Independent Web?

There is one concern I keep coming back to. I don’t want the web to become a place where every piece of information has a price tag. One of the reasons I love the IndieWeb is that people share things simply because they want to. They write about their hobbies, document experiments, publish tutorials and tell stories that might interest only a handful of readers. There is no business plan behind every post, and nobody expects every page to generate revenue. I certainly don’t want to lose that.

But I also don’t see why sharing something freely with human readers should automatically mean that commercial AI services can use it without any conditions. Those are two different things, and I think we should be able to treat them differently.

A personal website could remain completely open to human readers while offering paid access to commercial AI agents. A specialist publisher could sell verified information through an API while continuing to publish ordinary articles. A research institute could make certain findings publicly available while licensing structured datasets for commercial applications. And perhaps a journalist could eventually receive compensation not just when someone reads an article, but also when an AI service uses a piece of original reporting.

Whether any of this becomes economically significant remains to be seen. The research is still experimental, the payment systems are developing and commercial demand for paid journalistic information has yet to be demonstrated at scale.

There is also a risk that large publishers, payment providers and technology platforms end up controlling this new market, leaving independent creators with little more influence than they have today. That would be rather disappointing (to say the least), especially when the underlying technologies offer the possibility of a more open and accessible system.

Maybe we are finally asking the right questions

When I wrote my previous post, I was mainly interested in whether AI companies could be made to pay for the web content they use. Maybe there is an even more interesting question: what exactly is the value of journalistic information, and how do we make sure that value reaches the people who created it?

A payment protocol such as x402 can help move money between machines, but it cannot determine who deserves that money. That requires information about sources, originality, verification, licensing and actual usage. It will probably also require considerable cooperation between publishers, researchers, technology companies and standards organisations.

The latest developments certainly don’t mean we have solved the problem. There are still technical, legal and commercial obstacles, and we have very little evidence about how much money such systems might eventually generate.

But the discussion is becoming more interesting. Instead of arguing only about whether AI companies should pay publishers, we are beginning to examine what they should pay for, how those payments could work and who should receive them.

And that is something I intend to keep following. Because I still believe AI can create wonderful opportunities for journalism and the independent web. I’d just like the people who make that web worth reading to benefit from those opportunities too.

My Laptop, My Canvas: The Curious Art of Stickerbombing

I keep coming across photos of laptops that are almost completely covered in stickers. Sometimes there are just a handful. Sometimes there are dozens, overlapping each other until you can barely recognise the laptop underneath. And I have to admit, I rather like them.

Recently, I came across this wonderful stickerbombed ThinkPad T480 (https://drkhsh.at/posts/2026/01/stickerbombed-thinkpad-t480/). It made me realise that there is something rather fascinating about people turning an ordinary laptop into what almost looks like a little piece of art.

I’m not talking about modifying gaming computers with colourful lighting, transparent cases or elaborate cooling systems. Just ordinary laptops. ThinkPads, MacBooks, Dell Latitudes and whatever else people happen to use. So I started looking into it. And as it turns out, there is quite a story behind those stickers.

This is nothing new

First of all, decorating laptops with stickers is hardly a recent invention. People have been doing it for decades. Long before Instagram, TikTok or the current fascination with personalising everything, programmers, hackers, students and other computer enthusiasts were already covering their laptops with stickers.

In the hacker community, particularly, stickers have been part of the culture for a very long time. Visit a hacker conference and you’ll probably find plenty of laptops advertising Linux distributions, programming languages, security tools, obscure projects and jokes that only a handful of people understand. Some stickers are collected at conferences. Others come from friends, open-source projects or organisations people support. And of course, there are those who simply think a particular sticker looks cool.

In an interesting Computer Weekly article (https://www.computerweekly.com/feature/A-sticky-story-How-and-why-hackers-love-stickers-on-laptops), several security professionals explain why stickers became so popular among hackers. One explanation caught my attention. When you’re a programmer, much of what you create is invisible to the outside world. Your work exists somewhere inside a computer. Stickers offer a way to make some of that otherwise invisible world visible. I like that explanation.

A little piece of your identity

But what exactly is stickerbombing? Is it an art form? A way of communicating? A personal statement? Or simply decoration? I think it’s a bit of everything.

There is certainly an artistic element to it. Some people carefully arrange stickers into beautiful compositions. Others deliberately overlap them, creating a colourful mess that somehow works surprisingly well. But I suspect that for many people, the stickers themselves are more important than the final composition. A sticker from a conference you attended five years ago. A band you used to listen to. A political statement. A programming language you particularly like. A cartoon that makes you laugh. A tiny logo from an open-source project you once contributed to.

Individually, these stickers might not mean much to a stranger. Together, however, they tell a story. In fact, I came across a fascinating project at the University of Zurich (https://dlf.uzh.ch/sites/laptopstickers/) where students documented people’s laptops and interviewed their owners about the stickers. What I particularly liked was that the researchers didn’t just look at the images. They wanted to understand why people had chosen those particular stickers and what they meant to them. Sometimes the answer was deeply personal. Sometimes political. Sometimes surprisingly ordinary. And sometimes people couldn’t really explain their choices at all. They just liked the sticker. Which, when you think about it, is a perfectly good reason.

A sticker that started a friendship

One of the nicest stories I found came from that same Zurich project. A student named Konstantin had a laptop covered with stickers, including several from a climbing gym in Baden, Switzerland, where he worked. Another student recognised the gym’s logo because he knew the place and had helped with its renovation and promotion. So he approached Konstantin and started talking. They soon discovered that they had quite a few friends and acquaintances in common. What began with a simple question about a sticker eventually led to them spending time together outside university.

A sticker on the back of a laptop helped two people discover a connection they might otherwise never have noticed. And I can relate to that. Last summer, while walking along a beach in the south of France wearing an old Nextcloud T-shirt, I was approached several times by complete strangers who recognised the logo. Before I knew it, we were standing there in 35-degree heat, talking about Nextcloud, open source and digital autonomy. I actually wrote about it in an episode of De Overstap on Computable.nl (https://www.computable.nl/2026/08/17/de-overstap-9-nextcloud-op-het-strand/; text in Dutch).

There’s another lovely detail in Konstantin’s story (https://dlf.uzh.ch/sites/laptopstickers/konstantin/). He originally started putting stickers on his laptop because a former flatmate had designed one. He wanted to show her that he appreciated her artwork. One sticker led to another. And another. Eventually, his laptop became a collection of little stories.

Sometimes all it takes is The Office

There’s a similar, if slightly less dramatic, story from the Netherlands. Wisang, a student at the University of Twente, wrote about his laptop stickers (https://www.utwente.nl/en/stories/student/612150/what-your-laptop-stickers-say-about-you/) and how they reflect the communities he belongs to, the music he likes and the places he’s visited. He describes his laptop as a kind of time capsule.

But he also explains that stickers can be excellent conversation starters. See someone with a sticker from a band you like? There’s an obvious reason to say hello. He even recalls talking to someone whose laptop featured a sticker from The Office. That led to a conversation about how the person had failed to finish a paper because they were too busy watching the series for the fifth time.

Not exactly a life-changing encounter of course. But that’s rather the point, isn’t it? We spend so much time communicating through screens that it’s quite refreshing to discover how something stuck on the outside of a screen can encourage people to talk to each other.

Your laptop as a personal time capsule

Another interesting aspect is how these collections develop over time. Some people start with a single sticker and gradually add more. Others deliberately cover every available square centimeter. And sometimes the stickers overlap because there simply isn’t any space left. I wonder how many people could still remember where every sticker came from. Perhaps they got one at their first technology conference. Another from a friend. A third from a project they once worked on. Years later, the laptop might be technically outdated, but its cover contains a small history of its owner’s life.

That also raises an interesting question. What happens when you replace the laptop? Do you start again with a clean surface? Try to peel off the old stickers? Or keep the old laptop because you can’t quite bring yourself to throw away all those memories?

In a Hackaday article about laptops and stickers (https://hackaday.com/2022/01/22/hackers-fingerprints-laptops-and-stickers/), Elliot Williams explores how unique these collections can become. He also makes an observation I particularly like: sometimes people have the same stickers because they gave them to each other. In other words, those little images can represent shared experiences and friendships. Not just individual identity, but a bit of collective history too.

There is even a museum for them

And then I discovered Stickertop.art (https://stickertop.art/). Yes, someone has created an online collection dedicated to laptop covers decorated with stickers. Which I think is a wonderful idea. After all, we preserve photographs, paintings, posters and countless other examples of personal creativity. Why not laptop lids?

A laptop covered with stickers is often a completely unique object. There might be thousands of identical ThinkPads in circulation, but probably only one with that particular combination of stickers arranged in exactly that way. And once the laptop disappears, that little collection disappears with it. Unless somebody takes a photograph.

Making something mass-produced your own

Perhaps what appeals to me most is the contrast between the way laptops are designed and the way some people choose to use them. Manufacturers spend enormous amounts of time making their products look sleek, professional and consistent. A ThinkPad is supposed to look like a ThinkPad. A MacBook is supposed to look like a MacBook. And then someone comes along with a handful of stickers and completely ignores all that carefully considered industrial design.

I find that rather charming. Especially because I like the idea of making technology your own. On Just Me, we talk a lot about personal computing, but much of the technology we use today is remarkably uniform. The same devices, the same operating systems, the same applications and increasingly the same online services. Of course, putting stickers on a laptop doesn’t change any of that technically. But it does change the relationship between the owner and the machine, at least a little. It becomes less anonymous. Less like just another product. More like something that belongs to a particular person.

And perhaps that is what stickerbombing really is. Not necessarily art, although it can be. Not necessarily a deliberate statement of identity, although it often is. And not necessarily an attempt to communicate with strangers, although apparently it sometimes works remarkably well. Maybe it’s simply a way of making an otherwise ordinary object a little more personal. One sticker at a time. And if one of those stickers happens to start a conversation, or even a friendship, that’s a rather nice bonus.

What If We’ve Been Looking at the Internet the Wrong Way?

I spend quite a lot of time thinking about technology. Linux, open source, AI, the IndieWeb, journalism, personal websites, and all sorts of little experiments that I probably spend far too many evenings working on. But lately, I’ve been wondering whether I’ve been looking at the internet from the wrong direction.

Or perhaps not the wrong direction. Just one particular direction. When I come across an interesting new technology, my first reaction is usually to wonder what I could do with it. Could I build something? Could it make journalism more interesting? Could it help people become less dependent on big technology companies? Could I run it on my own computer?

Those are perfectly reasonable questions, I think. But they’re not the only questions worth asking.

A conversation in Berlin

One of the things that got me thinking about this happened during the Nextcloud Community Conference 2026 in Berlin. I spent quite some time talking with Christian Fu Müller, Nextcloud’s AI lead. We talked about AI, agentic AI, its possibilities, and the ways people might use it. At some point, Christian showed me a book he had brought along. An actual paper book, which somehow seems worth mentioning at a technology conference.

It was How Not to Use AI, by Abi Awomosu. I hadn’t come across it before, but it caught my attention. And after reading it, I found myself thinking about AI a little differently. Not because I’d suddenly become sceptical about AI. Far from it. I’m still a big fan, perhaps even more so than before.

But the book helped me reconsider something. I tend to approach AI by asking what it can do. What tasks can it perform? What can I build with it? How can it make something easier or more interesting? Increasingly, though, I find myself wondering whether I should spend just as much time asking what people actually need from it. Is that the best possible way to use AI? And perhaps that question shouldn’t be limited to AI. Perhaps I should be asking it about the internet as a whole. In a way, the book made me realise something that had been lurking somewhere in the back of my mind for quite a while, but that I’d never really managed to put my finger on.

What are people actually doing?

A while ago, I came across stories about teenagers using shared Google Docs to communicate with each other. Not because Google Docs is a particularly good messaging platform, but because it was available to them when other forms of communication weren’t. I love that kind of thing. Someone designs a tool for one purpose, and people decide to use it for something completely different. Or consider people who spend hours together in a Discord voice channel without really talking. They’re studying, working, playing games, or just doing their own thing. They’re not necessarily there to have a conversation. They simply like knowing that someone else is around.

Why do they that? That question fascinates me. We’ve spent decades developing increasingly sophisticated ways for people to communicate online. And then some people use those technologies to enjoy being together without communicating very much at all. Or take the people who buy old iPods, even though their smartphones can play practically every song ever recorded. Why? Maybe nostalgia. Maybe they like the physical buttons. But perhaps some of them simply want to listen to music without being interrupted by messages, notifications, recommendations, or the temptation to check something else. What if the attraction of an old iPod isn’t what it can do, but what it doesn’t do?

The things people don’t necessarily ask for

Here’s what makes this particularly interesting to me. People don’t always know how to describe what they want from technology. They don’t necessarily say, “I would like a digital environment where I can experience social presence without the obligation to interact.” They just sit in a Discord channel with their friends. They don’t say, “I need a separate online identity where I can escape the pressure of presenting a carefully curated version of myself.” They create a second Instagram account that only a handful of friends know about. And they don’t necessarily say, “I would like to reduce the cognitive demands of my digital environment.” They buy an old iPod.

Of course, I’m simplifying things here. People have all sorts of reasons for doing what they do. And three interesting examples don’t automatically add up to a trend. But that’s exactly why I find this so fascinating. Because sometimes, the most interesting developments aren’t announced at technology conferences. They don’t appear in product roadmaps or industry reports. They emerge when people start doing slightly unexpected things with the technology they already have. And perhaps those little experiments tell us something about needs and desires that haven’t yet been properly understood.

Looking beyond my own little corner of the internet

There’s another reason I want to explore this. I’m a big fan of the IndieWeb. I like personal websites, RSS, open standards, and the idea that people should have more control over their digital lives.

But I also realise that this probably colours the way I look at the internet. When I see people becoming frustrated with a large social network, I’m inclined to think about independent websites or decentralised alternatives. When I read about concerns over online privacy, I immediately think about local-first software, self-hosting, and open source. And when someone complains about search engines, I start looking at alternative search tools.

But what if that’s not what those people actually want?

Perhaps someone frustrated with Instagram doesn’t want an independent website at all. Perhaps they simply want a place where they can share silly photos with five friends without worrying about everyone else. Perhaps someone concerned about privacy doesn’t want to run their own server. They just want their phone to stop asking them questions.

I think there’s a real danger in looking at people’s behaviour and immediately interpreting it through our own technological preferences. I’d like to become a little better at avoiding that.

The internet’s little understories

I’ve started thinking of these things as digital understories. The small, sometimes strange things people do online that might tell us something bigger about being human. Not necessarily trends. Certainly not predictions about the next big thing. More like little clues. Why do people talk to AI chatbots about things they hesitate to tell their friends? Why do some online communities deliberately try to remain small? Why do people create elaborate digital spaces that hardly anyone will ever visit? Why do we save thousands of photographs, only to become uncomfortable when our phones unexpectedly remind us of something from ten years ago? And why do people sometimes seem to want less technology, while spending more and more of their lives online?

I don’t know the answers. But I’d love to spend more time looking for them. And not just within the IndieWeb. In gaming communities, fandoms, online classrooms, group chats, hobby forums, and all those other corners of the internet that technology journalists don’t necessarily pay much attention to. Especially when people are doing things that don’t quite make sense at first. Those are often the most interesting things.

And then there’s Mara…

There’s another idea I’ve been playing with. Just Me is, well, just me. My own little corner of the internet, where I write about whatever catches my interest. But what if I invited a second voice into the mix?

Someone who isn’t particularly interested in Linux distributions, open-source software, or building yet another little tool with AI. Someone who’s much more interested in people. Why they behave the way they do online. What makes them feel connected. Why they invent strange little digital habits. And what all of that might tell us about the internet we’re creating together. I’ve even been thinking about giving this digital person a name.

So far, her name is Mara. Now, before anyone gets confused, Mara isn’t a real person. She is a fictional, AI-based character. A little experiment in creating a different perspective on the digital world, with real sources and facts behind the stories.

But I’m not sure I want to introduce her as a fully fledged contributor right away. Maybe she will just turn up in the comments occasionally. Perhaps I’d write something enthusiastic about a new technology, and she asks a question I hadn’t considered. Or maybe she points out that the interesting part of a story isn’t the technology at all, but what people are doing with it.

And yes, I wrote that in present tense. Because she’s already been doing exactly that. How? Well, I started by giving her a name and a personality. Once I was happy with who she is and the role she might play here at Just Me, I simply asked her: “Have a look around my blog and pick three posts you’d like to comment on, based on your personality and the role we’ve discussed. Then write those comments so I can review them.” And that’s exactly what she did. They were interesting and relevant. So I published them.

I rather like the idea of a curious fictional character slowly finding her place on Just Me. And who knows? Perhaps one day I’ll ask her to write a post of her own (spoiler: I will). Or perhaps she’ll turn out to be rather annoying. That could be interesting too. I’m simply becoming increasingly fascinated by the things people do with the internet when nobody is telling them how they’re supposed to use it. And I have a feeling there are a lot of stories hiding there. I just need to learn where to look.

What If We Could BookCross the Internet?

I stumbled upon a website the other day that I hadn’t thought about in years: Bookcrossing (https://www.bookcrossing.com/). Remember BookCrossing? The idea is wonderfully simple. You take a book you’ve finished reading, register it on the website, and leave it somewhere for a complete stranger to find. That might be a park bench, a café, a train station, or wherever you think someone might come across it. Inside the book is a unique identification number. If the person who finds it visits BookCrossing and enters that number, they can leave a message. Perhaps they’ll tell you where they found it, whether they enjoyed reading it, or where they plan to leave it next. And so the book continues its journey.

I remember the idea from years ago. But I had absolutely no idea that BookCrossing was still around. It turns out that it is. Very much so.

More than twenty years of books travelling around the world

BookCrossing started in 2001, which means it has been around for a quarter of a century. Just think about that for a moment. Facebook didn’t exist. Twitter didn’t exist. YouTube didn’t exist. Smartphones, at least as we know them today, were still years away. Yet people were already using the internet to connect complete strangers through something as ordinary as a paperback. And they’re still doing it.

BookCrossing has attracted more than a million registered members over the years, and books are still being released into the wild. There are dedicated BookCrossing locations, local meetups, online discussions, and people who have been participating for decades. Of course, that doesn’t necessarily mean BookCrossing is experiencing some huge revival. It may simply be a community that never really went away.

I actually like that possibility even more. Not everything on the internet needs to grow exponentially. Sometimes, an idea is simply good enough to keep people interested for twenty-five years.

There’s something wonderful about not knowing what happens next

The part of BookCrossing that appeals to me most isn’t necessarily the book itself. It’s the uncertainty. You leave a book somewhere, and that’s it. You have no idea who might find it. Perhaps a student picks it up on the way to university. Perhaps a tourist takes it home to another country. Perhaps it ends up on a bookshelf for ten years before someone decides to release it again. Or perhaps nobody ever registers it. That’s fine too.

For me, the interesting thing is that you’ve put something into the world without knowing who will receive it or what they’ll do with it. No followers. No likes. No algorithm carefully selecting an audience for you. Just a book and a stranger. And, with a little luck, a story that continues.

Then there’s Postcrossing

While looking into BookCrossing, I came across another project that follows a remarkably similar idea: Postcrossing (https://www.postcrossing.com/). This one started in 2005 and revolves around postcards. You sign up, request an address, and send a real postcard to a randomly selected participant somewhere in the world. When your postcard arrives and gets registered, you become eligible to receive a postcard from another random participant. It’s such a simple concept. And yet millions upon millions of postcards have travelled around the world because of it.

What fascinates me is that the internet is only part of the process. The website helps people find each other, keeps track of the postcards, and makes the whole thing possible. But the actual experience happens away from the screen. Someone chooses a postcard, writes a few words, attaches a stamp, and drops it into a mailbox. Days or weeks later, somebody else discovers it among their regular mail. I can easily imagine the pleasure of opening your mailbox and finding a postcard from a stranger in Japan, Brazil, or Finland. Not because you bought something. Not because somebody wants to sell you something. Just because another person somewhere in the world decided to send you a postcard.

People are doing similar things digitally

Naturally, I started wondering whether people had come up with digital versions of these ideas. And of course they have. Take Bottled (https://www.bottledapp.com/), for example. It’s essentially a digital version of putting a message in a bottle and throwing it into the sea. You write a message, place it in a virtual bottle, and send it on its way. A random stranger receives it and can decide whether to keep it and start a conversation or let it continue its journey.

Then there’s Slowly (https://slowly.app/), an app that brings back the idea of pen pals. You write digital letters to people around the world, but there’s a twist: delivery takes time. The farther away the recipient lives, the longer your letter takes to arrive. Which is slightly ridiculous when you think about it. We’re deliberately slowing down technology that could deliver a message in milliseconds. But that’s exactly the point. Not every digital interaction needs to happen instantly. Sometimes waiting is part of the fun.

These projects aren’t identical to BookCrossing or Postcrossing, of course. They have their own rules and communities. But there’s a common thread. They use technology to introduce a little unpredictability into our lives. To connect people who otherwise wouldn’t have met. To make receiving something from a stranger feel like a small event.

And that got me thinking.

What if we did this with digital content?

Here’s an idea I can’t seem to get out of my head. Why couldn’t we do something similar with blog posts? Or essays, short stories, photographs, little digital magazines, or whatever else people create and publish online?

Imagine writing a blog post and registering it with something we might call DigitalCrossing. You publish your article on your own website, just as you normally would. The content stays there. Nothing needs to be uploaded to another platform. But you also give that article a unique identification number and release it into the digital wild. Somewhere in the world, another participating blogger or reader receives a link to your article. Not because they follow you. Not because an algorithm has decided your interests are similar. And certainly not because you’ve paid to reach them. They receive it simply because someone has released it into the wild.

Perhaps they read it. Perhaps they leave a comment. Perhaps they discover that they really like your writing and decide to explore the rest of your website. And then they have a choice. They can keep the link, ignore it, or pass it along to another randomly selected participant. Just like a BookCrossing book.

Imagine following the journey of your blog post

This is where it gets really interesting. Suppose I publish an article here on Just Me about one of my experiments with Linux or some obscure corner of the internet. I register the post with DigitalCrossing and release it. The first person to receive it lives in Finland. They read it, leave a short message, and pass it along. Next, it arrives in Brazil. The Brazilian reader happens to know somebody in Japan who might enjoy the article, so they send it there. That person forwards it to someone in Canada. And suddenly, my little blog post has travelled around the world.

I could visit a page showing its journey. Not a dashboard full of impressions, engagement rates, conversion funnels, and all the other stuff that seems to dominate the modern internet. Just a simple record of where my article has been and, if people choose to leave them, a few comments from the people who encountered it.

Of course, it wouldn’t really be tracking every visit. It would record the people who voluntarily acknowledge receiving and passing along the article. That’s perfectly fine. BookCrossing doesn’t know about every person who picks up a book either. The gaps are part of the story.

This could actually be quite simple

The more I think about it, the less complicated it seems. You’d need a website where people can register their own content, a way to assign unique IDs, a mechanism for randomly passing links between participating users, and a simple page showing where each item has travelled. That’s basically it.

And there’s no reason it would have to become another giant social platform. In fact, I’d prefer it didn’t. The whole thing could be built around RSS, links, and perhaps Webmentions to allow participating websites to communicate with each other. You wouldn’t need to copy anyone’s content or store everybody’s articles in one central database. The original piece would remain on its creator’s website. And perhaps individual bloggers could run their own little DigitalCrossing nodes, connected to others.

It would take some work to build something reliable and prevent spam and abuse, obviously. People would also need control over what they receive and whether their participation is visible. But the basic concept doesn’t seem particularly difficult to implement. Especially now that AI-assisted coding makes it easier for people like me to experiment with software ideas without having to become professional developers first. And experimenting with ideas like this is something I enjoy doing anyway.

Not another recommendation engine

There’s one thing I would absolutely want to avoid. I wouldn’t want DigitalCrossing to become a recommendation engine. We already have plenty of those. You read about Linux? Here’s more Linux. You like photography? Here’s another photography blog. You follow someone who writes about retro computers? Here’s a list of other retro-computing enthusiasts. There’s nothing necessarily wrong with that. But it tends to give us more of what we already know.

One of the lovely things about BookCrossing is that you might find a book you would never have chosen for yourself. Maybe you’re interested in technology, but the book you discover on a train is about gardening in the nineteenth century. You pick it up anyway. And who knows? Perhaps you enjoy it.

I’d want DigitalCrossing to work in much the same way. Someone who normally reads about cooking might receive one of my posts about a strange Linux experiment. I might receive a beautifully written story about somebody restoring an old boat in Norway. Would I ever have searched for that? Probably not. Would I read it? Quite possibly. And that’s what makes the idea interesting to me.

Perhaps we should let our content go travelling

I don’t know whether somebody has already built exactly what I’m describing. I’ve found several projects that do parts of it, but not a well-established community where digital content travels from person to person in quite the same way as a BookCrossing book. Maybe it exists somewhere in a forgotten corner of the internet. And perhaps I’ll stumble across it one day.

But if it doesn’t, I think it would be a fun thing to build. Not as a business. Not as a new social network. And certainly not as yet another way to maximise traffic to our websites. Just as a small experiment in connecting people and helping them discover things they weren’t looking for. After all, isn’t that one of the reasons many of us fell in love with the internet in the first place?

BookCrossing has been sending physical books around the world since 2001. Postcrossing has been doing something similar with postcards since 2005. Maybe it’s time we gave our blog posts the same opportunity. Write something. Release it into the wild. See where it goes. I rather like that idea.

The IndieWeb Needs More Builders and AI Can Help

I came across an interesting discussion about AI and the IndieWeb today. And I have to admit, I was a little surprised by it.

It started with Brennan Kenneth Brown (https://brennan.day/the-indieweb-now-has-genai-and-claude-built-in-what-do-we-do/), who noticed that Aaron Parecki, one of the people behind the IndieWeb movement, had been using Claude Code to rebuild several important IndieWeb tools.

Brennan wasn’t particularly happy about this. To him, the IndieWeb is about people building their own little corners of the internet, away from the influence of Big Tech. Using generative AI from a company like Anthropic to build those websites and tools seems to go against that idea. Aaron responded (https://aaronparecki.com/2026/10/17/5/rebuilding-my-indieweb-projects) with a blog post explaining why he uses Claude Code and why he doesn’t see a problem with it.

I understand Brennan’s concerns. But I’m definitely on Aaron’s side here.

Does everything have to be handmade?

I love the IndieWeb. I like personal websites, blogs, RSS feeds and people who build strange little things simply because they feel like building them. I also like the idea that my website is mine, my content is mine and I decide what happens to it. And yes, I understand that some people want to keep the IndieWeb pure. Whatever that means. They want websites built by humans, with code written by humans, without AI getting involved. Fair enough. If that’s how you enjoy building websites, please continue doing exactly that. But why should everybody else have to work the same way?

I’ve been using WordPress for years. I didn’t write WordPress. I didn’t write the theme or most of the plugins I use. Does that make my website less personal? Of course not. The same goes for people using Hugo, Jekyll or one of the many other tools available. We all use software that somebody else created. We copy bits of code, read tutorials, borrow ideas and use libraries that save us from reinventing everything ourselves.

So why is asking an AI to help write some code suddenly such a big problem? I don’t see the difference as being quite as fundamental as some people apparently do.

I have more ideas than programming skills

I’m a big fan of AI. I use it for all kinds of things, including coding. Or vibe coding, if you prefer that term. I’m not a professional programmer. I understand quite a bit about technology, but that doesn’t mean I can sit down and write a complete application from scratch.

What I do have is ideas. Lots of them. I regularly think of little tools that might be useful for my work as a journalist, for my blog or simply because I want to see whether something is possible. In the past, many of those ideas went nowhere. I could search for existing software, try to modify something or spend a lot of time figuring out how to write the code myself. Sometimes that worked. Quite often it didn’t.

Now I can sit down with an AI coding tool and start experimenting. Sometimes I have something working in an evening. Sometimes it takes days. Sometimes the AI makes a complete mess of things and I have to start again. But I’m building things I probably wouldn’t have built a few years ago. For example, I’ve been experimenting with software that collects IT news from websites in more than 23 languages. I also play around with Hugo, Docsify, local AI models and various little tools for my own publishing projects. I enjoy the process enormously. Not because every experiment produces something useful, but because I can finally try out ideas that would otherwise have remained ideas. And isn’t that exactly the sort of thing we want people to do on the IndieWeb?

Think about all the people who aren’t programmers

This is what I think is missing from some of the discussions about AI and the IndieWeb. Not everybody knows how to code. And not everybody wants to spend months learning. Someone might have a wonderful idea for a personal website but no idea how to build it. Someone else might want to add a special feature to an existing blog. Or create a small application that lets friends share photographs, book recommendations or whatever else they find interesting.

Without programming skills, those ideas can be difficult to turn into something real. AI changes that. Not perfectly, and certainly not without risks, but it does make building software much more accessible. I think that’s fantastic. Imagine someone who has never built a website discovering that, with a little help from AI, they can create something of their own. Perhaps they start with a simple page. Then they add a blog. Then an RSS feed. And before they know it, they’re experimenting with features they never thought they could build. They might even become interested in learning how the code actually works. I would much rather see thousands of people experimenting with their own websites, even with AI-generated code, than see them spend another ten years publishing everything on Instagram, TikTok or Facebook.

There’s a difference between AI code and AI slop

Now, I do think there’s an important distinction to make. Using AI to help build a website is not the same as using AI to fill that website with hundreds of meaningless articles. I don’t particularly enjoy visiting a personal blog only to discover that the content is generic AI-generated text with no real personality, experience or interesting ideas behind it. I visit personal websites because I want to read what people think, what they’re working on, what they’ve discovered or what made them laugh.

That’s the human part I care about. But if someone uses AI to create a clever publishing tool, improve the design of their blog or add some functionality they couldn’t have built themselves, why would that bother me? The same applies to writing, by the way. AI can help with research, editing, translations and getting a difficult paragraph into shape. The interesting part is still what the person behind the blog has to say.

Of course, AI can also produce terrible code. It can introduce security problems, misunderstand requirements or create software that is difficult to maintain. If you’re publishing a tool that other people depend on, you have a responsibility to check what you’re putting online. And that’s another reason I found Aaron’s response interesting.

What if the alternative is shutting things down?

Aaron explains in his blog (https://aaronparecki.com/2026/10/17/5/rebuilding-my-indieweb-projects) that some of his IndieWeb projects are around fifteen years old. They were built with technologies that are now outdated and increasingly difficult to maintain. Two examples are Webmention.io and IndieAuth.com, services used by many independent websites. He wanted to modernize them, but there was always something else to do. Sound familiar? With Claude Code, he has finally been able to tackle much of that work. He has rewritten old software, introduced new features and dealt with problems that had been sitting on his to-do list for years.

And here’s the important part: Aaron says that without these rewrites, he might eventually have had to shut some of those services down. That would hardly have been good news for the IndieWeb.

There’s another issue here. Many open-source projects depend on a surprisingly small number of people. People who maintain software in their spare time, often without being paid. They have jobs, families and other things to do. If AI helps them maintain their projects, fix bugs or finally implement features they’ve wanted to add for years, I see that as a good thing. Of course, AI doesn’t magically make software maintenance free or effortless. Someone still has to understand what the software does and take responsibility when something goes wrong. But if it helps keep useful projects alive, why reject it?

And what about Big Tech?

Brennan does have a point when he questions the use of AI services provided by large technology companies. I share some of those concerns. I’m not particularly interested in replacing our dependence on large social media platforms with a new dependence on a handful of AI companies. But I don’t think the answer is to reject AI altogether.

For one thing, we increasingly have open-weight AI models that can run on our own computers. I find that particularly interesting, and I’ve been experimenting with local AI myself. For another, using a commercial tool to build something doesn’t automatically mean that the thing you’ve built belongs to the company providing that tool. If I use Claude Code to help create a website that runs on my own hosting, uses open standards and stores my content in formats I can easily move elsewhere, I still have a considerable amount of control. And if I can replace Claude with another coding tool tomorrow, even better. For me, that’s much more important than whether every line of code was typed by a human.

There is also something rather nice about the fact that AI can help people create alternatives to the big platforms. We can use these tools to build more independent websites, more personal applications and perhaps even better ways for those websites to communicate with each other. That doesn’t solve every problem with AI. But it certainly makes the discussion more interesting.

Please, let’s not make the IndieWeb a club for programmers

Perhaps that’s what bothers me most about the idea that IndieWeb projects should be entirely handmade. It risks turning something that should be open to everybody into something primarily for people with the right technical skills. I don’t think anybody actually wants that. But it could easily happen if we start judging personal websites by the tools used to build them.

One of the things I enjoy about the personal web is how different everything is. Some websites are beautifully designed. Others look as though they haven’t changed since 1998. Some people write long essays. Others publish photographs, short notes or lists of interesting links. And I would love to see more people joining in. If vibe coding helps someone create their first personal website, that’s great. If it helps an experienced developer maintain an old IndieWeb service, that’s great too. And if someone prefers writing every single line of HTML by hand, that’s equally fine. There’s room for all of them.

After all, the IndieWeb is supposed to be about having your own place on the internet and doing things your own way. So let’s not start telling people that their way is wrong because they used AI. The IndieWeb doesn’t need fewer tools. It needs more people building things, experimenting, writing and sharing. And if AI helps make that happen, I’m all for it.

What If AI Had to Pay for the Web It Reads?

This is a long one, so bear with me. But I’ve really wanted to write about this for a while now, because it’s been on my mind for quite some time. So, here we go!

I love AI. I use it almost every day, experiment with local language models, and build little tools with it. Some of those experiments are useful. Others are simply fun to build. And quite a few are related to journalism, which is how I make my living.

But there is something about the AI industry that has bothered me for quite some time. AI companies have built incredibly powerful products using enormous amounts of information from the web. Articles, blogs, tutorials, research papers, discussions, documentation. Much of that material was written by people who never received a penny from the companies using it.

Whether all that training was legally permitted is still being debated in courts and elsewhere. But regardless of the legal arguments, there is an economic question here. If AI becomes one of the main ways we consume information, shouldn’t some of the money flow back to the people who create that information? Especially when those people are independent writers, bloggers, journalists and small publishers who don’t have the resources to negotiate licensing agreements with companies like Google or OpenAI.

Recently, I came across something called x402. And it made me wonder whether we might finally be seeing the beginnings of a different model. The interesting thing is that x402 isn’t the only initiative moving in this direction. There are experiments involving machine-readable journalism, new licensing standards and even marketplaces where publishers could sell their information to AI companies and others. Individually, these developments are interesting. Put them together, and something rather fascinating begins to emerge.

Two Cents for an Article? Why Not?

The idea behind x402 (https://x402.org/) is surprisingly simple. When your browser requests a webpage, the website normally sends the requested information back. Sometimes it refuses access, perhaps because you need to log in or don’t have permission. There is also an HTTP status code called 402, which stands for Payment Required. It has existed for decades but has never become a widely used way of paying for things on the web.

x402 builds on that idea. Imagine an AI agent looking for information about a particular cybersecurity vulnerability. It finds a relevant article on an independent technology website and requests access. Instead of simply handing over the article, the website responds: this will cost you two cents. The agent pays, the website verifies the payment, and the article is delivered. No subscription. No registration form. No credit card details to enter. No human intervention. The payment becomes part of the normal communication between two pieces of software.

Technically, x402 can use digital currencies such as stablecoins, which are designed to maintain a relatively stable value. That doesn’t mean a publisher has to become a cryptocurrency enthusiast. It does mean that wallets, payment providers and conversion into ordinary money are practical issues that need to be solved.

And two cents is just an example. A publisher could charge a fraction of a cent for a short piece of information or considerably more for access to a specialist report. For humans, paying separately for every article would probably be rather annoying. For software that automatically collects and processes information, however, such payments could be perfectly manageable.

This is what makes x402 interesting. It was originally developed by Coinbase and is now being developed as an open protocol under the Linux Foundation (https://www.linuxfoundation.org/press/linux-foundation-is-launching-the-x402-foundation-and-welcoming-the-contribution-of-the-x402-protocol). That matters because the web doesn’t particularly need another proprietary payment system controlled by a single company.

The Web Is Getting Some New Customers

There is another reason I find this interesting. For years, websites have largely been designed around human visitors. We write articles, people find them through search engines or social media, and hopefully they visit our websites. Those visitors might see advertisements, subscribe to a newsletter or pay for content.

AI is changing that relationship. Increasingly, people ask an AI assistant a question and receive an answer without visiting the websites where the underlying information originated. And AI agents are taking this further. They can search, compare sources, retrieve documents and process information without a human opening a browser at all.

For publishers, that creates a rather strange situation. Their information might become more useful than ever, while the number of people visiting their websites declines. A small specialist publication could produce an excellent article that is consulted by dozens of AI agents. Yet the publisher might receive no traffic, no advertising revenue and no indication that the article was used. That doesn’t sound like a particularly sustainable future for independent journalism.

But what if AI agents became paying customers? A specialist publication might offer its articles free to human readers while charging commercial AI services for automated access. Or it could offer a paid feed containing structured information specifically intended for machines. The website would no longer depend entirely on persuading humans to visit it. It could also earn money when software uses its work.

x402 Is Only One Piece of the Puzzle

Of course, the problem is more complicated than simply asking an AI agent to pay two cents. And x402 isn’t the only initiative trying to address it. Cloudflare, for example, has been developing several approaches to monetizing content used by AI. One is Pay Per Crawl (https://blog.cloudflare.com/introducing-pay-per-crawl/), which allows website owners to charge AI crawlers for accessing their pages. Another is Pay Per Use (https://blog.cloudflare.com/pay-per-use/), which takes a different approach. Rather than charging when information is collected, it aims to charge when that information is actually used by an AI service.

That distinction is important. An AI company might collect a thousand articles but use only a handful to produce an answer. Should it pay for collecting all thousand? Or only for the information it actually uses? There are arguments for both approaches, and they might eventually coexist.

Cloudflare has also introduced a Monetization Gateway (https://blog.cloudflare.com/monetization-gateway/) that supports x402, bringing automated payments closer to the infrastructure websites already use. Some of these services are still experimental or geographically restricted, so they are not yet ready-made solutions for every European blogger.

Then there is Tollbit (https://tollbit.com/), which focuses on licensed access to publishers’ content. Its approach includes different ways of charging for different uses, such as summarizing an article or reproducing more of its contents.

Another initiative worth watching is Really Simple Licensing (https://rslstandard.org/), or RSL. I particularly like the thinking behind this one. RSL is about making licensing conditions understandable to machines. A website could specify whether its content may be used for AI training, whether commercial AI services must pay, and which conditions apply. Think of it as a way for a website to tell automated visitors what they are allowed to do with its content. RSL could describe the rules, while x402 could handle a payment.

Another interesting development is SPUR, the Standards for Publisher Usage Rights coalition (https://www.spurcoalition.org/). It brings together more than 80 publishers and media organisations, including the BBC, Financial Times, The New York Times and AFP, to develop common standards for how AI companies use journalistic content.

One of its first initiatives is the Content Telemetry Standard, which aims to make AI systems record and report how they use publishers’ information. That addresses another important question: how can publishers charge for the use of their content if they don’t even know when or how it is being used? SPUR doesn’t solve that problem overnight. AI companies would still need to adopt these standards, and publishers would need ways to verify the information they receive. But it could provide another important piece of the puzzle: transparency. After all, before you can expect someone to pay for using your work, you need to know what they’re doing with it.

These initiatives don’t all solve the same problem. Some focus on payments, others on licensing, access control or measuring usage. But together they suggest something interesting: we may be moving towards a web where machines can negotiate access to information instead of simply taking whatever they can retrieve.

What If We Stopped Selling Articles and Started Selling Knowledge?

There is another idea that I think fits beautifully into this discussion: News Atom (https://reutersinstitute.politics.ox.ac.uk/introducing-news-atom-metadata-blueprint-journalism-age-ai). Developed by journalist Sannuta Raghu, News Atom starts with a rather interesting observation. Journalism isn’t just a collection of articles. Every article contains smaller pieces of information: facts, statements, figures, events, sources and context.

Those pieces of information have value of their own. Imagine a journalist writing about a new data center in Europe. The article mentions the investment, the planned power capacity, the location, the companies involved and the expected opening date. Now imagine an AI agent that only needs to know the power capacity of that data center. Why should it retrieve and process an entire article when it could obtain that particular piece of information directly?

More importantly, why shouldn’t the journalist or publisher who researched and verified that information receive something in return? News Atom proposes a way of making such information machine-readable while preserving the details that make journalism valuable in the first place. Where did the information come from? Who verified it? When was it published? Has it been corrected? What licensing conditions apply?

That last point is particularly interesting. Combine the thinking behind News Atom with machine-readable licensing and a payment protocol such as x402, and something new becomes possible. Not just for publishers, large and small, but also for the many other organisations that produce valuable content, from research institutes and industry bodies to all kinds of specialist organisations. An AI agent could potentially find a specific piece of verified information, check where it came from, understand the conditions for using it, pay for access and retrieve it. All without human intervention. Of course, News Atom itself is not a payment system, and this combination is still more of a possible future architecture than an established business model.

There is also an important distinction between facts and the journalism that produces them. A bare fact may not be protected by copyright, but the reporting, verification, context and structured data services surrounding it can still have commercial value. And that is precisely why I find this idea so interesting. Perhaps journalism’s future isn’t just about finding new ways to sell articles. Perhaps it is also about recognising that the knowledge journalists produce can have value independently of the articles in which it originally appeared.

For someone like me, who spends quite a bit of time experimenting with AI, journalism and automated news websites, that opens up some fascinating possibilities.

And What If Publishers Joined Forces?

There is another experiment worth mentioning, this time from Finland. Sitra, the Finnish Innovation Fund (https://staging.sitra.fi/en/articles/ai-can-create-new-business-opportunities-for-media-a-pilot-project-tests-the-marketplace-concept/), has been exploring something that sounds remarkably logical: a marketplace where news organisations can license their content to AI developers. And this isn’t just a theoretical exercise. Several Finnish media organisations, including Sanoma, Alma Media and public broadcaster Yle, are participating in a pilot that tests how journalistic content can be licensed, what AI developers actually need, and how much they might be willing to pay.

I find this particularly interesting because it addresses a problem that protocols such as x402 cannot solve on their own. A small publisher might have valuable information, but how does an AI company discover it? How does it know what rights are available? And how does the publisher find potential customers without employing a team of lawyers and salespeople? A shared marketplace could help solve those problems.

There is also a fascinating observation in Sitra’s research. AI developers training models often care more about having large quantities of usable information than about obtaining one particularly well-written article. That is not necessarily encouraging for an individual journalist or a small publisher. But it suggests that publishers might have more opportunities if they work together. Imagine hundreds of independent European publications making their journalism available through a shared marketplace. Each would retain control over its content and licensing conditions, while AI developers could discover and purchase information from many different sources. Combine that with ideas such as News Atom, machine-readable licensing and automatic payments through x402, and you can begin to imagine a rather different information economy.

Of course, we aren’t there yet. Sitra’s initiative is still testing the market, and nobody has demonstrated that this approach will generate substantial revenue for small publishers. But I like the direction. Instead of every publisher individually trying to negotiate with a handful of enormous AI companies, perhaps we could create an infrastructure where even the smallest independent publication can participate.

That sounds like a much more interesting future for journalism than simply putting another paywall in front of another article.

What About All the Content AI Has Already Consumed?

There is, however, an uncomfortable issue. Much of the content used to train today’s AI models has already been collected. And in many cases, the people who produced it weren’t asked for permission or offered compensation. I don’t think x402 solves that problem. A payment protocol cannot retroactively compensate millions of writers for material used in previous training runs. Nor can it decide whether a particular use of copyrighted material was legal. Those questions involve copyright law, licensing, transparency and, probably, a fair number of court cases.

But x402 and the other initiatives could help establish a different arrangement for the future. And I think that matters. I am not against AI companies making money. I use their products myself, and some of the technology is genuinely remarkable. But journalism costs money. Research costs money. Maintaining specialist knowledge costs money. Even writing a personal blog requires time, effort and usually a few hosting bills.

If AI services increasingly depend on information created by others, there should at least be practical ways for those creators to receive something in return. Not necessarily for every sentence an AI system reads. And not necessarily through one universal payment model. But the current situation, in which much of the economic value accumulates around the companies operating AI systems, deserves to be questioned.

Could This Work for a Tiny Independent Website?

This is where my curiosity really kicks in. Imagine a small independent technology publication that produces original reporting about European data centers, industrial automation or cybersecurity. It doesn’t have millions of readers. It doesn’t employ a sales team. And it certainly doesn’t have the negotiating power of The New York Times or the Financial Times. But it does produce information that might be valuable to AI services.

With an open payment protocol, the publisher could theoretically make that information available to automated customers without negotiating individual contracts. An AI agent requests an article. It receives a price. It pays. It gets access. That sounds almost too simple.

And perhaps it is. There are still plenty of unanswered questions. How does a website distinguish a legitimate paying AI agent from a crawler that ignores the rules? How do publishers know what their information is worth? Who pays the transaction fees? How do they prevent someone from buying an article once and redistributing it indefinitely? And perhaps most importantly: will AI companies actually be willing to pay? A technically elegant payment system is not much use if nobody wants to use it.

The economics are also uncertain. Ten thousand paid requests at one cent each would generate €100 before costs. That might be a nice contribution towards hosting expenses, but it isn’t going to finance a newsroom. A specialist publisher would need either substantial demand, higher prices, or other sources of revenue.

Still, I wouldn’t dismiss the idea just because the first numbers might be small. The important development is that a small publisher could potentially participate in a market that previously required direct commercial agreements with large technology companies.

Please Don’t Turn the Entire Web Into a Paywall

There is one thing I would hate to see happen. Imagine an internet where every article, blog post, tutorial and personal website demands a payment before anyone can read it. That would be awful. One of the things I love about the independent web is that people publish information simply because they want to share it. Someone writes about an obscure music genre. Someone else documents a strange Linux experiment. Another person explains how they built a little tool that nobody else thought of. There is no business plan. No marketing funnel. No expectation that every page must generate revenue.

I certainly don’t want to lose that. But I don’t think we have to choose between an open web and a web where creators can get paid. A personal blog could remain completely free for human visitors. The owner could allow non-commercial crawlers to access it, while requiring payment from commercial AI services that use the material in their products. Or the owner could decide not to charge anyone.

The important thing is that the website owner gets to decide.

That fits rather nicely with the whole idea of the IndieWeb. Own your website. Own your content. Choose your tools. Decide how your work may be used. And, perhaps, decide whether someone should pay for using it commercially.

Maybe This Is a New Opportunity for Journalism

I have been experimenting with AI and journalism for quite some time. One of my projects is an automated technology news website that collects information from sources in more than 23 languages, using two local language models running on a server in my own workroom. Experiments like this have made me increasingly aware of how much modern information systems depend on the work of other people. Without those sources, there is very little for the software to work with.

That is one reason I find this whole development so fascinating. I can imagine independent publishers offering machine-readable news feeds, specialist databases, research archives or individual articles through systems like x402. I can also imagine AI agents with small budgets that decide which information is worth buying. Some information might be free. Some might cost a fraction of a cent. Some highly specialised material might cost considerably more. And perhaps we could finally develop business models that don’t depend entirely on advertising, subscriptions or the goodwill of readers.

Will that happen? I have no idea. x402 might become an important part of the web’s infrastructure. Or another standard might take its place. Perhaps licensing systems and payment services will develop in completely different directions.

But something is clearly changing. For years, the conversation about AI and publishers has largely revolved around whether AI companies should be allowed to collect and use content. Now we are beginning to discuss how they might pay for it. And thanks to initiatives such as News Atom and Sitra’s marketplace experiment, we are also beginning to think differently about what exactly journalism could sell. Not just articles, but verified information, context and knowledge.

That is a much more interesting conversation. And for someone who loves both AI and the independent web, it is one I intend to follow closely. Because I don’t want a future without AI. But I certainly don’t want a future where AI has consumed the very web that made it possible.

You Can Bomb a Data Center, But the Bots Just Move Elsewhere

There is something fascinating about the way the Internet works. We tend to think of it as an enormous collection of servers, data centers, cables and networks. Destroy enough of that infrastructure and surely whatever is running on it will disappear too. Well, apparently not.

I came across a fascinating analysis by Cloudflare (https://blog.cloudflare.com/yandex-outage/) about what happened when Ukrainian drone strikes reportedly hit three Russian Yandex facilities between October 7 and 11. Yandex, for those unfamiliar with the company, is often described as the Russian equivalent of Google. It operates a search engine, but also provides cloud infrastructure and numerous other online services.

The attacks caused enormous disruption. According to Cloudflare, traffic from Yandex’s search network dropped by an astonishing 99% at one point. Traffic from its cloud network fell by 90%. And almost immediately, people started celebrating the apparent disappearance of Russian bot farms and online influence operations. There was just one problem: the bots hadn’t necessarily disappeared. Many had simply moved.

Not all bots are bad bots

Before getting into what Cloudflare discovered, there is an important distinction to make. Not every bot is malicious. A bot is simply a piece of software that automatically performs tasks on the Internet. Search engines use bots to discover and index websites. Monitoring services use them to check whether systems are working. And, increasingly, AI companies use them to collect information.

Cloudflare distinguishes between different types of automated traffic. One category is called verified bots. The word “verified” simply means that Cloudflare has confirmed that a bot really belongs to the organization it claims to represent. For example, a verified YandexBot is genuinely operated by Yandex rather than someone pretending to be its search crawler.

Being verified doesn’t automatically mean everyone welcomes that bot. It simply means its identity has been established. This distinction turned out to be rather important. Cloudflare discovered that most of the traffic disappearing from Yandex’s search infrastructure came from legitimate search crawlers. These were bots indexing websites, downloading images and collecting information for search results.

In other words, a substantial part of the spectacular traffic collapse was simply Yandex becoming less capable of indexing the web. Not quite the same thing as destroying a Russian army of malicious bots.

The bots that changed address

The situation was more interesting on Yandex.Cloud, the company’s cloud-hosting infrastructure. Here, Cloudflare did observe a significant decline in suspicious activity. Automated attempts to identify vulnerable WordPress plugins, for example, fell by 90%. Other scanning activity dropped by 93%.

That sounds like excellent news. But Cloudflare looked beyond the overall traffic numbers. It examined how individual bots behaved, which websites they contacted and what technical characteristics their connections shared.

One particularly interesting example involved automated traffic targeting gambling websites. Immediately after the disruption, requests originating from Yandex.Cloud disappeared. But almost identical requests started appearing from other Russian hosting providers.

Cloudflare could recognize them through something called a JA4 fingerprint. This is a technical signature based on how software establishes a secure Internet connection. Think of it as a way to recognize the same kind of software even when it starts operating from a different server or IP address. The bots were using the same unusual request patterns, the same identifying information and the same technical fingerprints.

They hadn’t stopped working. They had changed hosting providers. In fact, the total volume of Russian-origin bot traffic targeting gambling accounts remained remarkably stable. It actually increased slightly during the period Cloudflare examined.

The Internet is surprisingly portable

This is what makes the story interesting to me. We have spent decades making computing infrastructure increasingly flexible. Virtual machines, containers, cloud platforms and automation allow applications to move between systems with relatively little effort. That flexibility is one of the great achievements of modern computing.

But it works for malicious software too. If an operator can move an application from one cloud provider to another, why wouldn’t someone running a bot network be able to do exactly the same thing? The physical infrastructure may be destroyed or disconnected, but the software itself can survive somewhere else. Provided, of course, that the operators still have access to their code, data and alternative infrastructure. And apparently, some of them did.

There is also a lesson here about how we interpret Internet statistics. A dramatic graph showing traffic falling to almost zero looks convincing. It creates an impression that something has been eliminated. But what exactly has disappeared? The servers? The network connections? The software? Or merely the traffic coming from a particular group of IP addresses? Those are very different things.

What about Russian disinformation?

Another interesting aspect of Cloudflare’s investigation concerns claims that the attacks had disrupted Russian influence operations on social media. Cloudflare examined traffic associated with social media activity, including automated requests involving posts, replies and likes. It found no unexpected changes that would support claims of a major collapse in these operations.

That doesn’t prove that no influence operation was affected. Cloudflare can only analyze the traffic visible to its own network, and not every social media operation can be identified through HTTP requests. But it does demonstrate why we should be careful about drawing conclusions from spectacular traffic charts.

A decline in traffic from Russian infrastructure does not automatically mean that Russian disinformation has stopped.

Destroying infrastructure is not the same as destroying an operation

What I particularly like about this Cloudflare investigation is that it illustrates something much broader than the consequences of a few drone strikes. We have created an Internet where software is increasingly independent of the physical machines on which it runs. That is exactly what cloud computing was supposed to achieve. Applications should be portable. Services should survive infrastructure failures. Workloads should be able to move between providers. And when we celebrate those capabilities, we usually think about legitimate businesses, websites and applications. But the same principles apply to people using the Internet for less legitimate purposes.

The Cloudflare findings don’t mean that attacks on infrastructure have no consequences. Clearly, Yandex suffered a substantial disruption, and legitimate services were affected. Nor do they mean every malicious operation can relocate without difficulty. They do show, however, that destroying infrastructure and stopping an online operation are two very different challenges.

Perhaps that is the most interesting conclusion of all: we have made software so good at surviving infrastructure failures that even the bad guys benefit from it. And somehow, that seems a very Internet-like outcome.

What If Your Friends Were Your Cloud?

I have a soft spot for local-first software. And for slightly crazy ideas that make you wonder why we accepted the current way of doing things as the only logical option. Yggstore ticks both boxes (https://github.com/peterretief/yggstore).

Yggstore is an experimental open-source project that basically asks a very simple question: what if we could build our own cloud using the computers of people we trust? No Google Drive. No Dropbox. No OneDrive. No giant data centre somewhere. Just computers. Your computer. Mine. A mini PC at my brother’s house. An old laptop at a friend’s place. Maybe a Raspberry Pi somewhere else. Together, they become the cloud.

Your file is everywhere. And nowhere.

The basic idea behind Yggstore is surprisingly easy to understand. Suppose I have a large file that I want to store. Instead of uploading that file to a cloud provider, Yggstore encrypts it and chops it into pieces. Those pieces are then distributed across different computers participating in the network.

Importantly, Yggstore adds redundancy. It doesn’t simply cut a file into four pieces and hope that all four computers remain online forever. It creates additional pieces that can be used to reconstruct missing data. So if one of the machines disappears, breaks down or is temporarily offline, I can still retrieve my file. In that sense, it reminds me a little of RAID. Except that instead of several disks sitting inside one server, the “disks” can be computers sitting in different houses. That immediately makes the idea much more interesting.

The tiny file that matters

There is another clever part. After storing something in Yggstore, you keep a small .ystub file locally. Think of it as a luggage tag. The suitcase itself may be somewhere in the enormous luggage system of an airport. The tag contains the information needed to find it again. The Yggstore stub performs a similar role. Give it back to Yggstore and the software can retrieve enough pieces from the network, reconstruct the data and decrypt the original file.

That also means those tiny stub files are rather important. Lose them and retrieving your data becomes a problem. So yes, you need to back up the information that tells your backup system how to find your backups.

Your own little internet

Yggstore doesn’t do all this over the normal internet in quite the same way that Dropbox does. It uses Yggdrasil, an encrypted IPv6 overlay network. In simple terms, Yggdrasil allows computers to create their own peer-to-peer network on top of the existing internet. That network can consist of machines belonging to people you trust.

Which is where the whole concept becomes particularly appealing. Imagine four or five friends each buying a cheap second-hand mini PC with a reasonably large SSD. Everyone puts one somewhere in their house and makes part of the storage available to the others. My encrypted data might partly reside in Amsterdam, another piece in Brussels and another somewhere in Germany. Your data might partly reside on my machine. Nobody needs to be able to read anybody else’s files.

There is no central cloud company. Because we are the cloud.

I rather like that sentence

Because somewhere along the way, “the cloud” became synonymous with Amazon, Microsoft, Google and a relatively small number of other enormous companies. Technically, of course, it never had to mean that. Cloud computing is fundamentally about abstracting computing resources. Where those resources physically live is a different question. Yggstore takes that idea in almost the opposite direction from Big Tech. Instead of:

my laptop → Big Tech cloud → my data

we get something closer to:

my computer ↔ your computer ↔ his computer ↔ her computer

It is distributed computing brought back down to human scale. And that fits remarkably well with what I find interesting about the current local-first movement.

Local-first doesn’t have to mean local-only

This is an important distinction. When I talk about local-first computing, I don’t mean that everything has to live on one laptop disconnected from the rest of the world. That would throw away many of the genuinely useful things we gained from cloud computing. I want synchronization. I want backups outside my house. I want to access information from different devices.

The interesting question is whether achieving all of that automatically requires handing our data to a giant technology company. Projects like Yggstore suggest another answer. You can have distributed storage without necessarily having centralized ownership. That is a rather important distinction.

And apparently storage isn’t enough

Yggstore is already experimenting with more than simply storing files. There is versioning. There is file sharing. Nodes can exchange messages. The project even experiments with distributed website hosting and receiving email for your own domain.

There is also an interesting “give and use” principle. If I use storage provided by other people, I should provide storage to the network myself. Yggstore keeps track of that balance, although the mechanism is not yet strictly enforced. Instead of paying a company €10 every month for 2 TB of storage, I contribute resources to a community and receive resources from that community in return. It feels surprisingly old-fashioned. In a good way, that is. It reminds me of the earlier internet, when the idea wasn’t necessarily that every useful online activity needed a company, a subscription and a platform sitting in the middle.

Don’t cancel Dropbox just yet

There is, however, a rather large disclaimer attached to all of this. Yggstore is a proof of concept. The developer explicitly warns that the cryptography has not been independently audited. There are also technical limitations. For example, lost storage fragments aren’t yet automatically rebuilt elsewhere.

I would therefore not put the only copy of my life’s work on Yggstore. Actually, I wouldn’t put the only copy of my life’s work on anything. Backups are backups because there is another copy. But that isn’t really why I find Yggstore interesting. I am interested in the idea behind it.

Personal computing 2.0?

Over the past few years we have started seeing lots of small projects pointing roughly in the same direction. Local-first software. Self-hosting. Small servers at home. Open-source AI models running locally. Peer-to-peer networks. Personal knowledge systems where the files remain ours. And now experiments where a group of ordinary computers can collectively behave like cloud infrastructure.

Individually, none of these projects is going to replace Big Tech tomorrow. Together, however, they suggest that another architecture for personal computing is possible. One where the laptop becomes important again. Where a €150 mini PC can actually be useful infrastructure. Where cloud services complement our computers instead of replacing them. And, most importantly, where ownership starts with the user.

Yggstore may never become mainstream. It may remain an experiment. Another project may eventually implement the same idea much better. That doesn’t really matter. The interesting part is the question it asks: What if we didn’t need a cloud provider to have a cloud?

Put a few computers in a few houses, connect them securely, contribute some disk space and distribute encrypted data between them. Suddenly the answer becomes surprisingly tangible. Maybe the cloud doesn’t have to be someone else’s computer after all. Maybe it can be ours.