The Smartphone Features We Should Have Had Years Ago

Smartphones are astonishingly capable devices. They have cameras that would have seemed impossible twenty years ago, processors powerful enough to run serious software, satellite connectivity, increasingly sophisticated AI and enough sensors to know roughly what we are doing most of the day. And yet I regularly find myself wondering: why can’t my phone do this?

Not because I am waiting for some spectacular new technology. Quite the opposite. Many of the features I would like to see seem surprisingly simple. I recently came across a post on Curvise about phone features that really should exist by now, and that got me thinking about a much broader question. Smartphones have evolved enormously, but the way we interact with them has remained remarkably conventional. We still open apps. We still move information manually from one app to another. We still hunt through settings menus. And when we want privacy, we often need to disable several different things separately. Surely we can do better.

Why is my smartphone still a collection of apps?

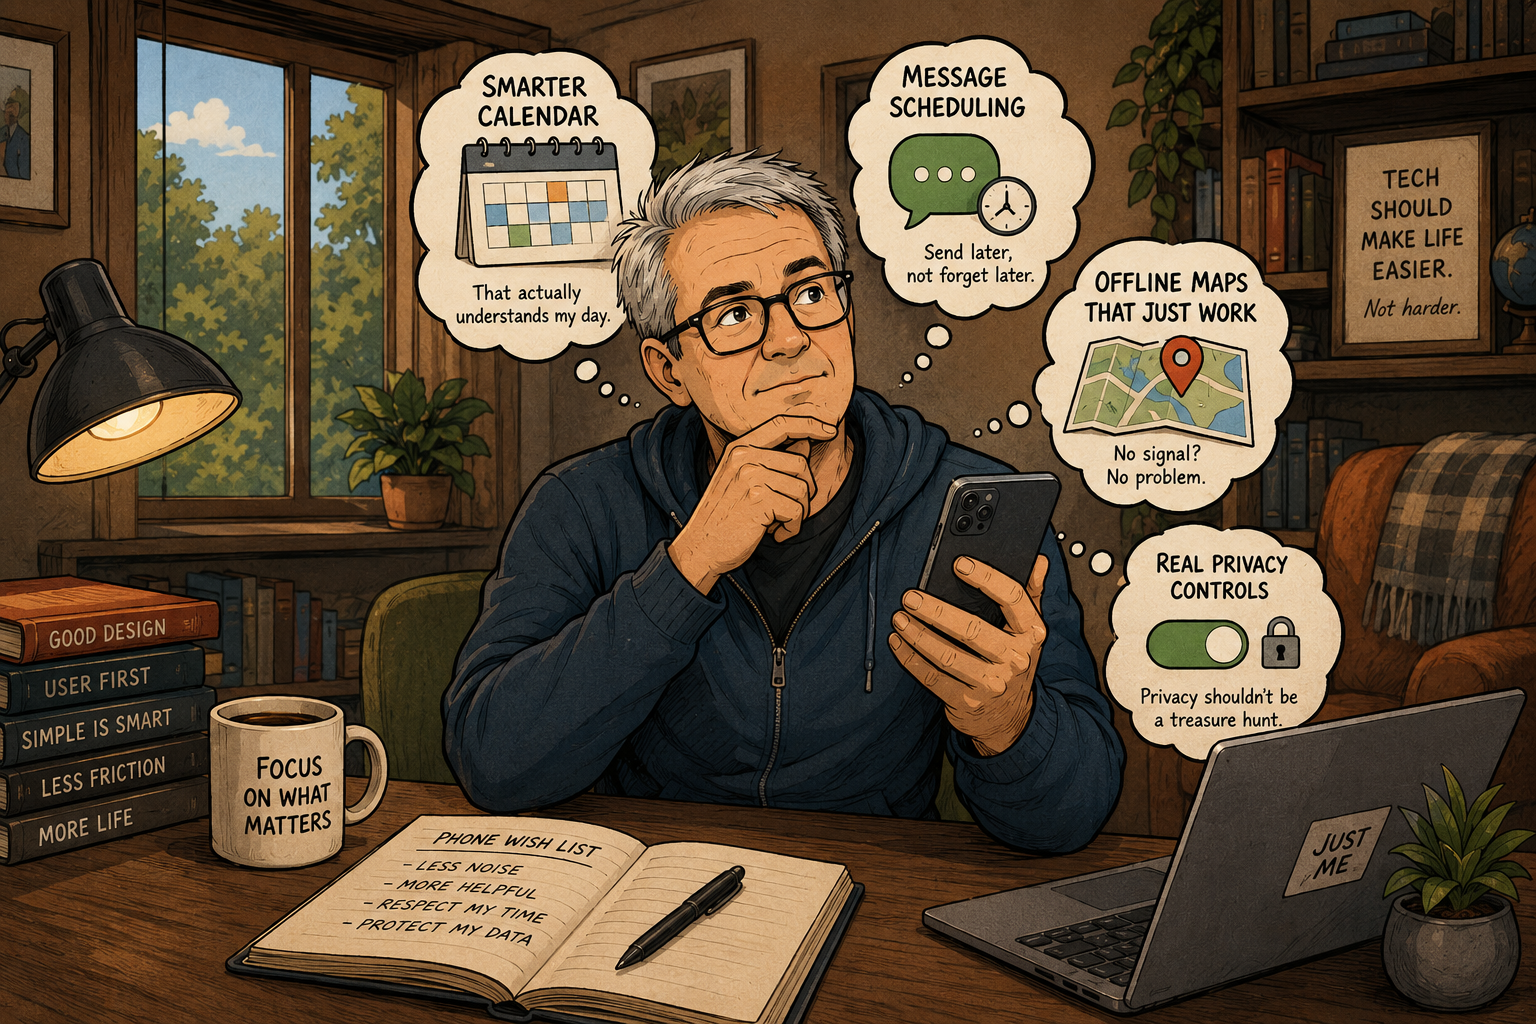
This is probably the biggest one for me. Suppose someone sends me a message asking whether we can meet next Wednesday at 11:00 at a certain café. What do I do? I open my calendar to check whether I am available. Then I open Maps to see where the café is and perhaps check how long it takes to get there. After that I return to the messaging app, confirm the appointment and finally go back to the calendar to create an event.

None of this is difficult, of course. But why am I doing all those individual steps? My phone already has access to the relevant information. It knows what is in my calendar, it knows where the café is, it can calculate travel time and it knows who sent the message. I should simply be able to say: “Yes, that works. Put it in my calendar and send the details back.” The phone should handle the rest.

This is where AI on smartphones could actually become useful. Not by generating funny pictures or summarising emails I could read myself, but by acting as a layer across the operating system. At the moment, smartphone software is still built largely around applications. Every app is its own little island, and we are the ones moving between those islands and performing a sequence of actions.

A smarter operating system could understand the intention behind what you are doing. You could say: “Send the photos I took yesterday to Anna,” or “Find the PDF Peter sent me last month and attach it to this email.” You might also ask: “During my holiday, silence all work notifications except messages from these three people”, or “Whenever I arrive at the office, switch my phone to silent mode and start my work timer.”

Some of this can already be achieved through automation tools, shortcuts or individual AI assistants, but that misses the point. It should not require programming your phone. The operating system itself should understand these kinds of instructions.

Small features can make a big difference

There is another category of missing smartphone features that is far less ambitious. These are the things where you discover an idea and immediately think: of course a phone should be able to do that. Curvise has collected several examples of this type, and I think this is an interesting reminder that innovation does not always have to mean adding another camera, making a screen slightly brighter or putting a faster processor inside a phone.

Sometimes innovation is simply about removing small irritations. Take notifications. Smartphones have become much better at managing them, but notification controls are still often strangely primitive. You can allow an app to send notifications or block them. Sometimes there are categories, and sometimes you can silence them temporarily. But I would like much more contextual control.

For example, I might want to tell my phone not to show me any news notifications while I am working, to mute a certain app until tomorrow morning, or to notify me only when a message in a group contains my name. I would also like to be able to say: “Never show promotional notifications from this app, but keep service notifications.” None of this sounds futuristic to me. It simply sounds useful.

The same applies to sound. Why isn’t there a proper mixer on every smartphone? My laptop lets me control the volume of individual applications, while on phones sound control is often still surprisingly basic. Perhaps I want Spotify playing quietly while a language-learning app is louder. Perhaps I want navigation instructions at one volume and music at another. Or perhaps I want one game permanently muted without disabling sound for everything else.

These are tiny improvements, but they can dramatically change how pleasant a device is to use. And that is something smartphone manufacturers sometimes seem to forget. A phone does not necessarily become better because it gains another headline feature. It becomes better when it gets out of your way.

Give me one big privacy switch

Then there is privacy. Modern smartphones contain microphones, cameras, GPS receivers, Bluetooth, Wi-Fi, motion sensors and plenty of other ways to collect information about us. Both Android and iOS now provide reasonably good permission controls, allowing you to decide which applications can use your microphone, camera or location.

But the controls are still fragmented. What I would really like is a huge, obvious privacy switch. One tap and camera access is off, microphone access is off, location access is off, Bluetooth scanning is off and background sensor access is disabled. Perhaps it could even temporarily disable network access for applications. Basically: a leave-me-alone-mode.

Android has experimented with sensor controls that come close to this idea, and individual privacy settings already exist on most phones. But there should be a simple universal control that temporarily shuts everything down. Imagine walking into a confidential meeting. Instead of checking five different settings, you tap one button and privacy mode is enabled. When the meeting is finished, you switch it off again.

Or perhaps you are visiting somewhere and simply do not want apps collecting location information for a few hours. Again: one tap, done. Of course there would need to be exceptions. Emergency calling, for example, should continue to work, and you might also want to allow certain devices or apps. But technically this does not seem particularly difficult.

More importantly, it would make privacy visible. At the moment privacy settings tend to be buried inside menus. That makes them something you configure once and then forget. A privacy switch would turn privacy into something you actively control.

Maybe we don’t need another AI button

What I find interesting about all these examples is that none of them require a radically different smartphone. The hardware is already there, the sensors are already there, the processing power is certainly there and even much of the software already exists in one form or another.

What is missing is integration. Smartphones have become enormously sophisticated devices, but we still interact with them in ways that often feel surprisingly manual. We open an app, tap something, copy information, switch apps, paste it somewhere else, change a setting and then switch it back later.

Perhaps the next big improvement in smartphones should therefore not be another camera lens or another AI button. Perhaps smartphones simply need to become better at understanding what we are actually trying to achieve.

Give me an operating system that can perform tasks across applications, give me much smarter contextual controls and please give me one enormous privacy switch. None of these ideas sound revolutionary, which is exactly why I find it so strange that we still don’t have them.

Here are two links to interesting blogs and ideas about this topic:

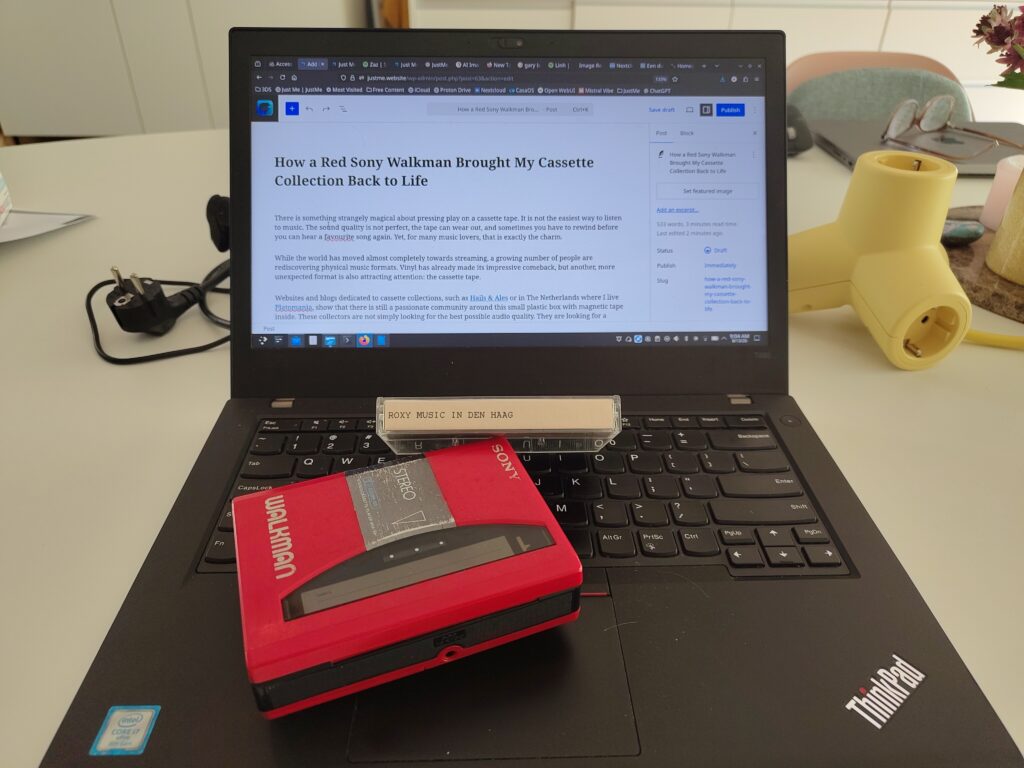
How a Red Sony Walkman Brought My Cassette Collection Back to Life

There is something strangely magical about pressing play on a cassette player. It is not the easiest way to listen to music. The sound quality is not perfect, the tape can wear out, and sometimes you have to rewind before you can hear a favourite song again. Yet, for many music lovers, that is exactly the charm.

While the world has moved almost completely towards streaming, a growing number of people are rediscovering physical music formats. Vinyl has already made its impressive comeback, but another, more unexpected format is also attracting attention: the cassette tape.

Websites and blogs dedicated to cassette collections, such as Hails & Ales or in The Netherlands where I live Platomania, show that there is still a passionate community around this small plastic box with magnetic tape inside. These collectors are not simply looking for the best possible audio quality. They are looking for a connection with music.

And that connection is something I completely understand.

Earlier this year, I bought a bright red second-hand (third-hand or maybe even seventeenth-hand?) Sony Walkman. It was not a practical purchase. In fact, from a purely technical perspective, it makes little sense. I have access to millions of songs through streaming services. I have high-quality digital files at home. I can listen to music anywhere, anytime.

But I bought that Walkman for one specific reason: a cassette recording I have been keeping for years. It is a recording of a Roxy Music concert in The Hague. A fantastic performance by a band that was always about atmosphere, detail and musicianship. When I put that cassette into the Walkman and press play, something remarkable happens. The music itself is already special, but then there is the mechanical sound of the Walkman: the tiny motor running, the subtle noises from the tape mechanism, the feeling that the music is physically moving through the device. That combination creates a completely different atmosphere.

The little imperfections become part of the experience. The slight hiss, the mechanical sounds, the fact that this is not a perfectly clean digital stream — they all add something human. It feels less like playing a file and more like opening a small time capsule.

Of course, my new Walkman did not arrive quickly. Earlier this year, The Netherlands experienced a period with unusually heavy snowfall, and deliveries were delayed. For a while, I was wondering when my little red music machine would finally arrive. But when it finally appeared, the wait was completely worth it.

That is why I enjoy following websites and communities that focus on cassette music. They understand that listening to music is not only about convenience or technical perfection. It is also about memories, stories and rituals.

At home, I still have a small collection of cassettes. Some are old recordings that have been with me for decades. Others are newer releases that show that the format is not just a nostalgic curiosity. Among them are tapes from the Dutch band Alquin, a group that played an important role in the Dutch progressive rock scene. And I also have a much newer cassette release from Cigarettes After Sex, proving that even modern artists see value in this old-fashioned medium.

Green Claims Are Easy. Proving Them Is the Hard Part

A friend of mine, Marco Verzijl, has been fighting for more transparency around data center sustainability and energy consumption for years. Whenever we talk about data centers, energy efficiency or sustainability, Marco usually comes back to the same basic point: claims are easy. Measurements are much more interesting. That is also the central idea behind a recent article he wrote for DCpedia.net (text in Dutch). Marco argues that a sustainable data center should not simply say it is sustainable. It should be able to prove it with reliable, traceable and independently verifiable data. I think that distinction is becoming increasingly important.

AI changes the discussion

Data centers have always consumed substantial amounts of electricity, but AI is rapidly changing the scale of the discussion. Powerful GPUs increase power densities, cooling becomes more demanding and access to sufficient grid capacity is turning into an important economic issue. At the same time, we increasingly depend on data centers. Hospitals, banks, government services, industrial systems, cloud platforms and, of course, AI applications all rely on physical digital infrastructure.

So the useful discussion is probably not whether we should have data centers at all. As Marco puts it, the real question is: which data centers do we need, for which applications, in which locations and with what demonstrable energy and societal performance? Answering that requires data.

PUE is only part of the story

One thing I particularly like about Marco’s argument is his criticism of looking at isolated sustainability indicators. Take PUE, or Power Usage Effectiveness. It is an important metric because it tells us something about how efficiently a data center uses energy for cooling, power distribution and other supporting infrastructure. But it does not tell us whether the servers themselves are doing anything useful.

Marco uses a nice analogy: an extremely fuel-efficient truck that drives around almost empty is still being used inefficiently. The same applies to a data center. A facility may have an excellent PUE while large amounts of IT capacity are hardly being used.

That becomes especially interesting with AI. Two models performing roughly the same task can require very different amounts of computing power and therefore energy. Eventually, we need to look beyond energy consumed per building and start asking how much useful digital output we receive per kilowatt-hour.

Green electricity is not enough

The same applies to renewable energy claims. Saying that a data center uses “100 percent green electricity” sounds convincing, but it does not necessarily mean renewable electricity physically powers that facility every hour of every day. Certificates and annual contractual arrangements can make the reality considerably more complicated. Water consumption, backup generators, heat reuse, hardware utilisation and even the lifetime and recycling of servers should also be part of the picture.

Which brings us back to transparency. Marco writes that sustainability data should be based on actual measurements, connected to known measuring points, traceable to source data and independently verifiable. Otherwise, sustainability risks becoming primarily a communications exercise. That seems like a useful principle far beyond the data center industry. Because in the end, as Marco concludes, a sustainable data center is not one that calls itself sustainable. It is one that can prove it.

You can read his article here: https://dcpedia.net/een-duurzaam-datacenter-begint-niet-bij-een-belofte-maar-bij-controleerbaar-bewijs/.

How I Use AI to Give Just Me Its Own Illustration Style

When I started Just Me, I quickly realised that writing the articles was only part of the job. A blog also needs a visual identity. Not necessarily a complicated one, but something that makes the site feel consistent. For me, illustrations are an important part of that.

I could of course use stock photography. There is certainly enough of it available. But I find that stock images often look exactly like what they are: stock images. The same smiling people behind laptops, the same futuristic server rooms and the same glowing AI brains seem to appear everywhere. That is not really what I wanted for Just Me. So I started experimenting with AI-generated illustrations instead.

Finding a style instead of generating random images

The interesting part is that I don’t simply ask AI to create an image for every article. That would be easy, but it would also produce a fairly random collection of pictures. Instead, I use AI to create illustrations within a recognisable style.

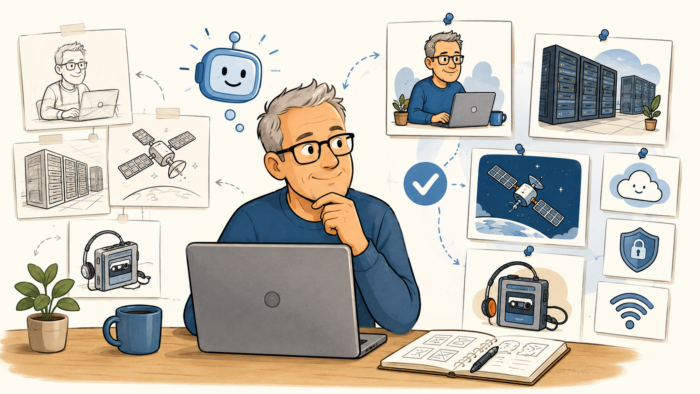
Most Just Me illustrations are deliberately cartoon-like. They are fairly simple, friendly and colourful without becoming childish. They should support the article, not compete with it. Sometimes there is a person working behind a laptop. Sometimes it is a data center, a satellite, a cassette player or somebody struggling with a piece of software. The subjects can be completely different, but I try to make the illustrations feel as if they all belong to the same website. That consistency is important.

AI gradually learns what I mean by “Just Me style”

This is also where working with AI becomes interesting. Over time, I have developed a kind of shorthand. I can ask for an illustration “in Just Me style”, while also describing the subject of the article and the scene I have in mind. That doesn’t mean the AI magically understands a formal design manual. There isn’t one.

The style has developed through repetition. I generate an illustration, look at the result and adjust it. Perhaps the image is too realistic. Perhaps the person looks too young. Maybe the background is too busy or the whole thing has that slightly overproduced AI look that I try to avoid. Then I refine the instruction.

After doing that repeatedly, certain elements start returning. The drawing style, the level of detail, the way people are depicted and the overall atmosphere gradually become more consistent. In other words, I am not asking AI to invent a new visual style every time. I am using it to keep working within a visual direction that has already been established.

Sometimes the character is me

There is another small detail. In some illustrations, the person is supposed to represent me. That means I don’t want the standard AI-generated young tech worker with perfect hair sitting behind an impossibly clean laptop. I am somewhat older. I have grey hair. And my desk is probably not quite as perfectly organised either.

Once that character had appeared in a few illustrations, it became another recurring element of the visual language of Just Me. That is something I rather like. The blog is called Just Me, after all.

The AI does the drawing, but I still make the decisions

Using AI for illustrations doesn’t mean pressing a button and accepting whatever comes out. I still decide what I want the illustration to communicate. Should it be serious or slightly humorous? Should the technology itself be visible? Does the illustration need a person at all? What should be happening in the image? There are often several iterations before I use one. In that sense, AI is less of an automatic illustration machine and more of a tool that makes it possible for someone who isn’t an illustrator to develop a reasonably consistent visual identity. And that, for me, is the useful part.

Consistency matters more than perfection

I don’t think every illustration needs to be perfect. In fact, I probably prefer them not to be. Just Me isn’t meant to look like a carefully polished corporate publication. It is a personal website where I write about technology, digital autonomy, sustainability, space, music, personal knowledge management and whatever else catches my attention.

The illustrations should have the same feeling. They make the site more recognisable, add a little personality and help connect articles about very different subjects. AI simply gives me a practical way to create them.

And after generating enough of them, something interesting happens: what started as a few experiments gradually becomes a style of its own. Not because I designed an elaborate visual identity beforehand. Mostly because I kept saying: make it a little more like Just Me.

Open or Open (AI) Washing?

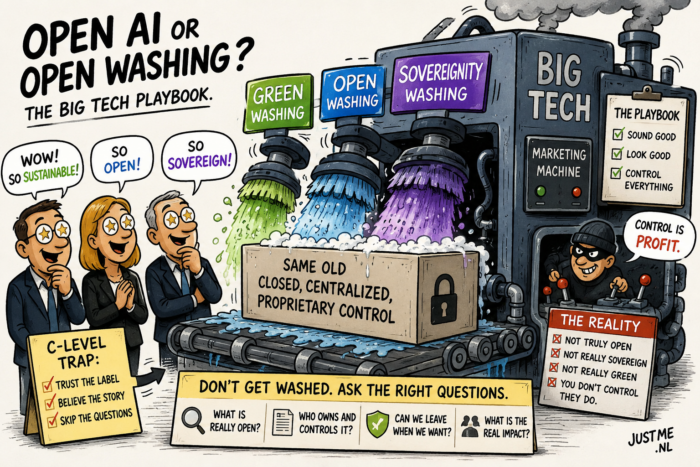
The technology industry has a long history of using attractive words to create a positive image. “Green”, “sustainable”, “responsible”, “sovereign” and now “open” are all terms that sound reassuring. But increasingly, these words are also becoming part of a familiar marketing strategy: make a product or service appear more independent, transparent or responsible than it really is.

We have seen this before with greenwashing. Companies present themselves as environmentally friendly while the reality behind their operations is often much more complex. A few sustainability initiatives or carefully chosen words can create the impression that a company is leading the way, even when the underlying business model has barely changed.

The same pattern is now appearing in other areas of technology. Open washing and sovereignty washing have become part of the same playbook.

Recently, I read an interesting article on Tech Policy Press titled “Open washing is everywhere in AI. Four criteria cut through it.” The author is J.J. Jasser, a professor and director of data analytics at Rollins College in Winter Park, Florida. His research examines artificial intelligence, open-source development, and digital literacy. He also contributes commentary on technology and digital literacy to the Orlando Sentinel.

Jasser explains how the word “open” is increasingly being used in artificial intelligence as a marketing term rather than as a clear technical description. The problem is that “open” can mean many different things. A company may release parts of an AI model, publish limited documentation or offer access through an interface, and then present the technology as open. But true openness requires much more: transparency about development, access to relevant information, the ability to inspect and adapt the technology, and meaningful freedom for users. As the author points out, companies often highlight the elements that support the “open” label while keeping important limitations less visible.

This is exactly why open washing deserves attention. The term creates a sense of trust and independence, while the actual level of openness may be far more limited. The same applies to digital sovereignty. In Europe, concerns about dependence on large technology providers have grown significantly. Organisations want more control over their data, infrastructure and AI capabilities. Big Tech companies have responded by introducing so-called sovereign cloud offerings and European cloud regions.

At first glance, this sounds like the solution Europe has been looking for. Data is stored in Europe, services are operated locally and the word “sovereign” appears prominently in the marketing material. But sovereignty is about much more than location. Who owns the technology? Who controls the software? Which laws apply? Where is the company based? Can customers realistically move away if circumstances change? These are the questions that matter.

Using a European data center does not automatically create digital sovereignty. Just as adding a green label does not automatically make a company sustainable, adding the word sovereign does not automatically create independence.

Unfortunately, many C-level executives still fall for these messages. Under pressure to make decisions about cloud, AI and digital transformation, it is tempting to rely on vendor promises and attractive terminology. But technology leaders need to look beyond the marketing language and examine the real level of control they have.

The lesson from the discussion around open AI is therefore much broader. Whether it is greenwashing, open washing or sovereignty washing, the mechanism is the same: take a concept with a strong positive meaning and use it to improve perception.

The answer is not to reject everything Big Tech offers. Many of these technologies are valuable and play an important role in modern organisations. But companies need to ask harder questions and demand more transparency. Because in the end, words like “open”, “green” and “sovereign” only matter when they are backed by reality. A label is easy to create. Genuine openness, sustainability and independence are much harder to achieve.


The Space Economy Is Taking Off

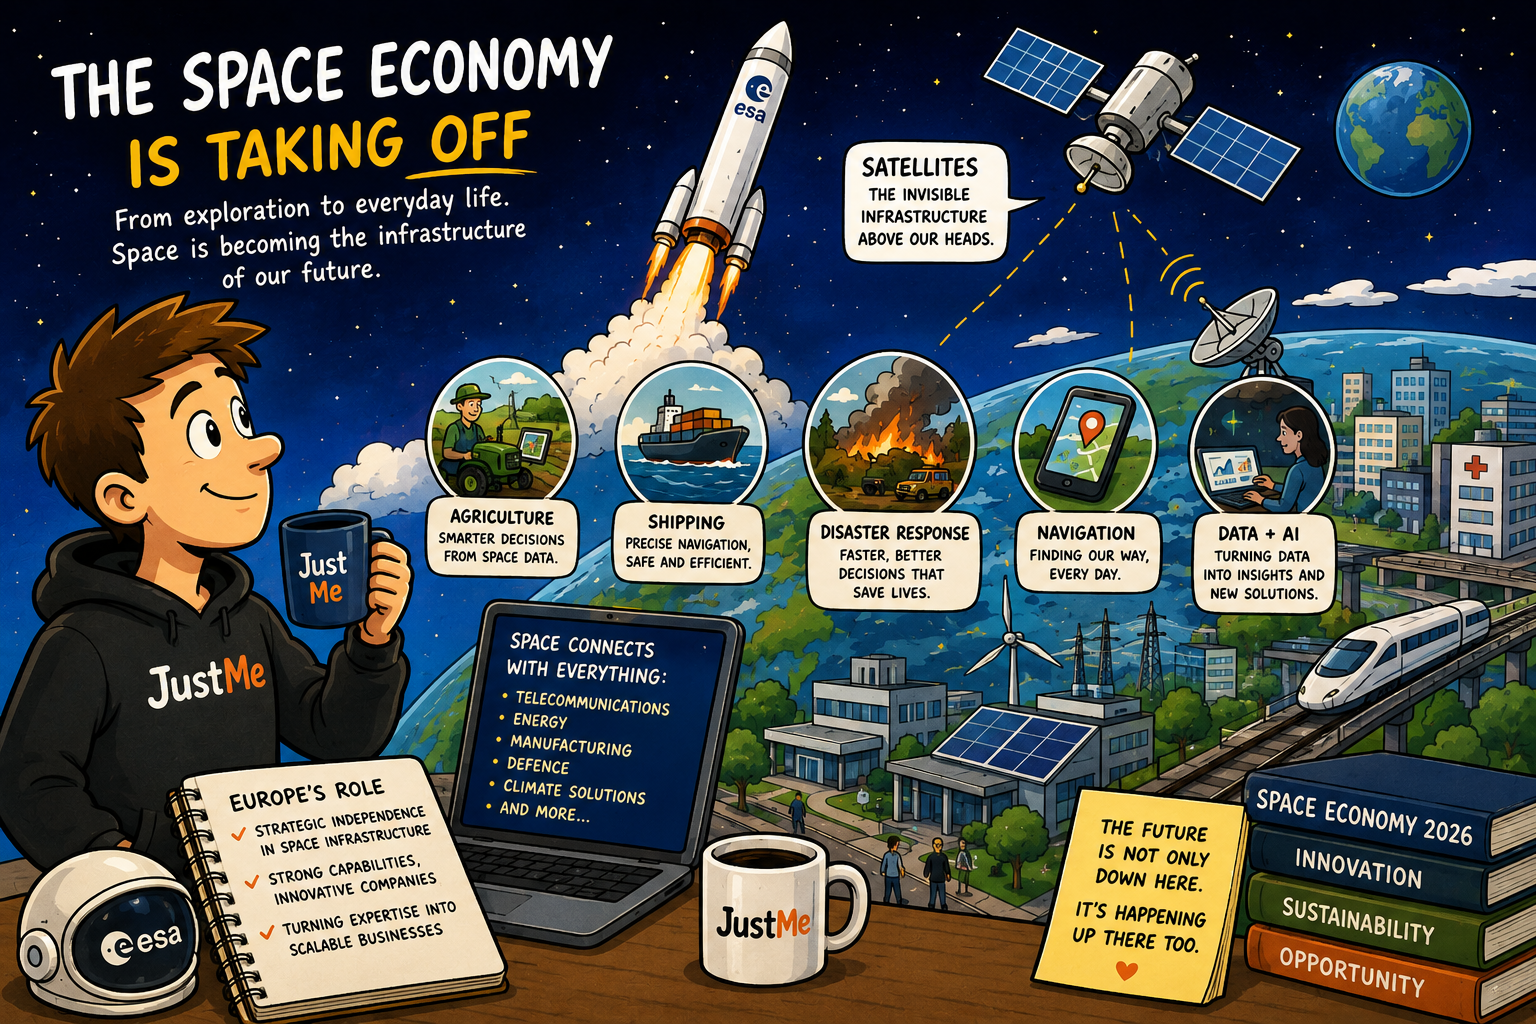
I have always been fascinated by space. Not only because of the spectacular images from distant galaxies, the engineering challenge of launching rockets, or the incredible scientific discoveries made by missions exploring our solar system. What fascinates me even more is the fact that space technology is increasingly becoming part of our everyday lives.

For many years, space was something that belonged mainly to governments, research institutes and a handful of large aerospace companies. Satellites were expensive, rockets were rare, and space exploration felt like something far removed from our daily reality. That is changing rapidly.

The latest Space Economy Report from the European Space Agency (ESA) shows how quickly space is developing into a mature economic sector. Space is no longer only about exploration and scientific missions. It has become an essential infrastructure layer for modern society — supporting communication, navigation, climate monitoring, agriculture, logistics, security and many other industries. And this is only the beginning.

From government projects to a global commercial ecosystem

One of the most interesting developments of recent years is the shift from a government-driven space sector towards a much broader commercial ecosystem. Companies are building satellites, developing launch services, analysing Earth observation data and creating completely new services based on information collected from orbit. The cost of entering space is decreasing, partly because of reusable launch technology, smaller satellites and more efficient manufacturing processes.

This has created opportunities for thousands of companies that would never have been considered “space companies” in the past. A farmer using satellite images to optimise irrigation is benefiting from space technology. A logistics company using precise positioning data relies on satellites. A telecommunications provider offering connectivity in remote areas depends on orbital infrastructure. And thanks to satellite data, governments can respond much more effectively to natural disasters such as wildfires, floods and earthquakes. In many ways, satellites are becoming the “cloud infrastructure in space”.

Europe’s role in the new space economy

As someone who follows technology, digital sovereignty and autonomy, and European innovation closely, I find the European perspective particularly interesting. The space economy is not only about economic growth. It is also about strategic independence. Just as Europe is discussing digital autonomy in areas such as cloud computing, artificial intelligence and semiconductor technology, space infrastructure is becoming a strategic asset as well.

Reliable access to satellite data, navigation systems and communication capabilities is increasingly important for governments, companies and society as a whole. Europe has strong capabilities in space technology. Organisations such as ESA, national space agencies, research institutes and a growing number of innovative companies are contributing to a competitive European space ecosystem. The challenge therefore is not whether Europe has the knowledge or the technology. The challenge is turning that expertise into scalable businesses and ensuring that Europe remains an important player in a rapidly growing global market.

The connection between space and artificial intelligence

Another reason why the space economy is becoming increasingly interesting is the connection with artificial intelligence. Satellites generate enormous amounts of data. Every day, they collect information about our planet, weather systems, oceans, cities and industrial activities. But collecting data is only the first step. The real value comes from analysing it.

AI will play a crucial role in turning satellite data into information we can actually use in daily (business) life. At the same time, space itself creates new challenges for AI. Processing data closer to where it is generated — potentially directly in orbit — could become increasingly important as the amount of information from satellites continues to grow.

One of the reasons I enjoy following developments in space technology is that they show how innovation often crosses traditional boundaries. Space is no longer an isolated industry. It connects with telecommunications, energy, manufacturing, defence, agriculture, logistics, climate technology and artificial intelligence. The same technologies that help us explore distant planets are also helping us solve problems here on Earth. This is perhaps the most exciting aspect of the new space economy: it is not about escaping from our planet. It is about understanding, protecting and improving it. And that makes this report a very interesting read.

Nextcloud on the Beach

A new episode of my “De Overstap” series has just been published on Computable.nl. In this series, I write about my own attempts to move away from the usual Big Tech ecosystem and see how far you can get with European, open source and more independent alternatives.

Episode 9 became something of a holiday edition. This summer I travelled with my family to the south of France with a tech setup that was almost completely free of the platforms I used to depend on. My laptop was my Slimbook Evo running Linux Mint, while my phone was a Fairphone 6 with Murena’s /e/OS. And yes, for the most part it worked remarkably well.

There was one small adventure on the way. As soon as I crossed the border, my phone suddenly had no mobile internet. Everything seemed to be configured correctly, but eventually I discovered (thank you Mistral Vibefor helping me) that the correct KPN APN setting was simply missing. Once I added it manually, everything worked again.

That experience actually illustrates one of the main points of this new episode. Alternatives to Big Tech increasingly work perfectly well from a technical point of view. But if we really want ordinary users to adopt them, the learning curve still needs to come down. People should not have to know what an APN is just because they choose a different mobile operating system.

And then there was Nextcloud. I happened to wear an old Nextcloud T-shirt on the beach in France. To my surprise, several French people recognised the logo and started talking to me about Nextcloud, digital autonomy and European alternatives. Hardly scientific market research, of course, but still interesting. Open source alternatives such as Nextcloud seem to be slowly moving beyond their traditional technical audience.

The article also includes my latest experiences with Capacities.io for personal knowledge management, plus a few other interesting alternatives I recently came across, including littleFedi, soev.ai and the Dutch Matrix service mtux.nl.

You can read De Overstap 9: Nextcloud op het strand on Computable.nl: https://www.computable.nl/2026/08/17/de-overstap-9-nextcloud-op-het-strand/.

AI Can Write The Code, But Do We Understand It?

There is something slightly strange happening in software development. For decades, one of the main challenges was writing the code. You had an idea, figured out how to translate it into software, wrote the code, discovered that it didn’t work, stared at it for half an hour, changed three characters and suddenly it did work.

AI changes that process dramatically. Today you can describe what you want and watch an AI coding agent produce hundreds or even thousands of lines of code. And it is only getting better at it. That sounds wonderful, but it also creates a problem that I find increasingly interesting: what happens when AI can write code faster than we can understand it?

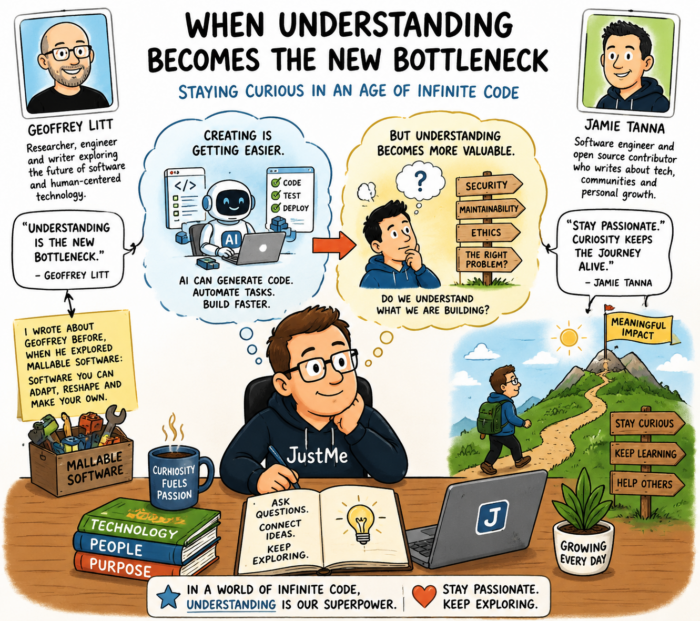
That is exactly the question Geoffrey Litt explores in his excellent article Understanding is the New Bottleneck. You can reda it here: https://www.geoffreylitt.com/2026/07/02/understanding-is-the-new-bottleneck. Geoffrey is a design engineer at Notion who writes and experiments extensively with new ways for humans to interact with software and AI. I have written about him before, especially when he was exploring the concept of malleable software: software that users can adapt, reshape and truly make their own instead of simply consuming it as a finished product. But also software you create when you need it and simply throw away when you don’t need it anymore.

In his new article, Geoffrey takes that thinking in an interesting direction. “It’s still important to understand the code that our agents write,” he argues. That sounds almost ridiculously obvious. Of course we should understand our software. But think about what happens when you actually start using AI coding tools seriously. You ask for a feature. The AI changes twelve files. It adds a library, modifies an API, creates some tests and changes part of the data model. Everything compiles. The tests pass. You run the application and it seems to work. Nice! On to the next prompt. And that is precisely where the danger begins.

The code works, so what?

Geoffrey Litt makes an important distinction between understanding code to verify it and understanding code so you can participate in developing it. Verification is basically asking whether the AI did its job correctly. Does the code compile? Do the tests pass? Does it match the specification? Is the architecture reasonable? AI is becoming increasingly capable of doing some of that verification itself.

But understanding has another purpose. If we really understand how a system works, We can think about what it should do next. We can see alternatives. We can recognise that a particular architectural choice will become a problem later. We can connect one part of the system with another. As Litt puts it, understanding allows us “to participate.”

I think that is an extremely useful way of looking at AI-assisted programming. If an AI agent has created half my application and all I can say about the result is, “Well, it seems to work,” I am no longer really developing that application. I am supervising its development.

Every time we accept code we do not understand, we also accumulate what Litt describes as cognitive debt. It resembles technical debt. You can ignore it for a while, particularly when everything is working. But sooner or later you need to change something and suddenly discover that you have lost your mental model of your own software.

So how do we prevent that? This is where Litt’s article becomes particularly useful, because he doesn’t just identify the problem. He experiments with practical ways of solving it.

Use a literate diff

One of the most obvious ways to review AI-generated code is to look at the diff. But imagine an AI agent has changed twenty files. Reading hundreds of changed lines from top to bottom is technically reviewing the work, but it isn’t necessarily a very good way of learning what happened.

Litt suggests turning the process around. Before looking at individual lines of code, ask the AI to explain the change. And not simply: What did you change? Ask it to teach you. What did the system look like before? What problem were we trying to solve? Which concepts do we need to understand? What architectural decision did you make? Which components interact with each other? What alternative approaches were possible? Why did you choose this one? Only then move towards the actual code.

Litt calls one version of this a literate diff. Instead of presenting changed files in whatever order Git happens to show them, the changes are presented as a story: first the background, then the idea, followed by the relevant pieces of code in an order that makes conceptual sense. That is an interesting idea. The AI wrote the code, so why not also make the AI write the manual that teaches us what it just built?

Ask for intuition

There is another subtle but important point in Litt’s approach: intuition before details. Suppose an AI has implemented a caching system. Before studying the implementation, we could ask: What exactly are we caching? Why will that make the application faster? When is the cache invalidated? What happens if it contains stale information? Where does the cache live? What happens after a restart?

Only once we understand those concepts does it make sense to study the classes, functions and data structures implementing them. The same applies to almost anything an AI creates. If it adds authentication, first understand the authentication flow. If it creates a database abstraction, first understand how data travels through the application. If it introduces asynchronous processing, first understand which things now happen in which order. If it creates an API, understand the contract before studying its implementation.

That sounds like basic software engineering. And I guess it is. The difference is that AI makes it extremely easy to skip these steps because the implementation can appear almost instantly.

Make the AI test you

This is perhaps my favourite suggestion from Litt. After the AI has explained the code, ask it questions about the system. Or even better: ask the AI to quiz you.

Litt actually does this. His code explainers contain five questions about the change, and he has a simple rule: he doesn’t send the code to other people until he can pass the quiz. That may sound a little like going back to school, but it solves an interesting problem. Reading something is not the same as understanding it. We can read a beautiful AI-generated explanation and think: yes, perfectly clear. Then somebody asks us five minutes later how the data actually gets from A to B and wemight very well discover that we don’t know.

So after an AI has generated something substantial, ask it: What are the five things I really need to understand about this implementation? Then close the explanation and try answering them yourself. Or ask the AI to give you scenarios. What happens if this API call fails? What happens when two users update this record simultaneously? Which component owns this data? What breaks if I remove this function? Where would I make a change if I wanted to add feature X?

If you cannot answer those questions, you probably don’t understand the software yet. says Litt. He describes these quizzes as a kind of speed regulator. AI can move much faster than human understanding, so occasionally we need to deliberately slow the loop down.

Tools for understanding AI code

Then comes an idea I hadn’t really considered before reading Litt. AI doesn’t only have to generate the application. It can also generate temporary software that helps you understand the application. Litt calls these micro-worlds. For example, while working on a Prolog interpreter, he had an agent create a debugger that allowed him to step through execution and see what was happening internally. In another project, an AI-generated interface let him migrate his website step by step while watching the old and new versions side by side.

That opens up all sorts of possibilities. Ask an AI to create a visualisation showing how data flows through the application. Ask it to build a tiny dashboard displaying internal state. Ask it for a stripped-down version of a complicated algorithm with sample data. Ask it to create a sequence diagram. Ask it to instrument the software so you can see which functions are being called. Or ask it to create a small playground where changing one variable immediately shows the consequences.

The important difference is that you do the exploring. As Litt notes, there is a big difference between asking an agent to debug something for you and using a tool created by the agent to investigate the problem yourself. In the second situation, AI hasn’t removed you from the process. It has given you better instruments.

Explain the code back to the AI

We could also add another simple technique: reverse the conversation. Don’t always ask the AI to explain things to you. Explain the software to the AI. Write down your understanding: As I understand it, request A enters here, is validated by B, stored through C and eventually triggers D. Component E is only used when… Then ask the AI: What have I misunderstood or missed?

This forces you to construct your own mental model instead of merely consuming the model’s explanation. You can do something similar by drawing the architecture yourself and asking the AI to check it against the codebase.

That distinction is important. The goal isn’t to have an AI that understands your software perfectly. The goal is for you to understand it.

Sometimes just write the code yourself

Which brings me to Jamie Tanna. Jamie is a software engineer and open-source maintainer who writes extensively about Go, open source, software engineering and his experiences with AI-assisted development. In his writing around GopherCon UK 2026, another question appears that fits remarkably well with Litt’s argument: how do you stay passionate about programming when increasingly powerful tools can do so much of the programming for you? You can read his report here: https://www.jvt.me/posts/2026/08/14/gophercon-uk-2026/.

That is a highly relevant question, because there is another risk here. You can understand perfectly well what an AI agent has built and still find the whole experience rather boring. For many developers, programming isn’t merely a mechanism for producing software. Solving the puzzle is part of the attraction. You try something. It fails. You discover why. You try something else. And somewhere during that process you learn something you didn’t know when you started.

If our interaction with software development becomes prompt, wait, accept, prompt, wait, accept, we may become extremely productive while slowly removing the thing that made programming interesting in the first place. That is why I think understanding and passion are closely connected.

Do not outsource all the interesting bits

There is no rule saying that because AI can do something, we have to let it. Let AI generate boilerplate, write repetitive tests, search through unfamiliar APIs and suggest solutions. But occasionally keep the interesting problem for yourself. Use AI as a teacher rather than a replacement. Ask it to give you hints instead of complete solutions. Ask it to explain an unfamiliar concept and then implement it yourself. Ask it to create an experimental environment where you can play with an algorithm. Or simply turn it off for an hour.

Efficiency isn’t always the objective. Sometimes learning is. Sometimes curiosity is. And sometimes spending an evening solving something that an AI could probably generate in thirty seconds is still worthwhile because we want to know how it works.

That is what I take away from these two authors. Litt’s argument isn’t really that we need to carefully inspect every line an AI generates. That would quickly become impossible. Instead, we need better ways of building and maintaining mental models of increasingly AI-generated systems. Explanations, literate diffs, quizzes, visualisations and micro-worlds can all help.

And Tanna’s thoughts about staying passionate add another line of thought. We shouldn’t only ask how AI can make us faster at programming. We should also ask how AI can make us better at understanding programming. That is a very different objective.

Perhaps the most interesting sentence in Litt’s article comes near the end: “The point was always to augment, not just automate.” I think that captures it perfectly. AI can write the code. It can test the code. It can explain the code. It can even write little tools that help us explore the code. But we still want to understand what is happening. Because the moment we stop understanding our, we also lose much of our ability to decide where it should go next.

AI Is Learning From Books by Destroying Them?

I use AI a lot. I find the technology fascinating and useful. But every now and then I come across a story that makes me wonder whether we have completely lost sight of what we are doing. This is one of those stories.

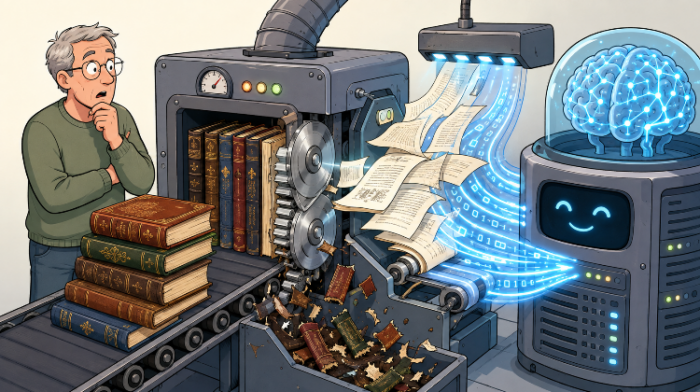
404 Media reports that Amazon is buying large quantities of physical books, scanning them to create AI training data and destroying the books in the process. The journalists even placed a tracker inside a shipment of rare books and followed it to an Amazon facility in Las Vegas where, according to employees, books are cut apart so they can be scanned more efficiently. Amazon itself confirmed that it purchases books through commercial channels to help develop and improve its products and services.

If this report is accurate — and there are now quite a few similar stories appearing elsewhere — I find this astonishing.

The basic process is brutally simple. Cut off the spine, separate the pages, scan them at high speed and turn the text into training data. The physical book is effectively gone afterwards. And apparently this does not only involve cheap mass-market paperbacks. 404 Media says the shipment it followed contained books that were rare in the sense that relatively few copies were in circulation.

This is not an isolated story either. Court documents previously revealed that Anthropic bought and destructively scanned millions of books for AI training. The Washington Post reported on the project, while Ars Technica described how bindings were removed, pages scanned and the original books discarded. Booksellers in Europe and Australia have meanwhile reported unusual bulk purchases of obscure and sometimes rare titles, although in many of those cases they cannot prove who the ultimate buyer is or what happens to the books afterwards.

I understand why AI companies want books. Compared with much of the web, books contain carefully edited, structured, human-written information. Older books also have another attractive property: they predate the current explosion of AI-generated text. For companies desperately looking for clean training data, that makes them extremely valuable. 404 Media previously reported that printed books are actively being marketed to AI companies for exactly this reason.

But surely there has to be a better way. A book is not simply a convenient container for a sequence of tokens. Especially with older or uncommon books, the physical copy can itself be part of our cultural and intellectual history. Once a scarce edition has been cut apart and recycled, having its text somewhere inside a gigantic training dataset is not quite the same thing.

What makes this even stranger is the contradiction. We are destroying human-made objects containing carefully collected human knowledge so machines can learn from that human knowledge.

Maybe all these reports will eventually turn out to be less dramatic than they currently appear. I hope so. But if AI really needs books this badly, I would much rather see us invest in ways of digitising and preserving them at the same time. Teaching machines should not require destroying the things from which they learn.

in Tech | 504 Words

The Curiosity That Makes a Great Tech Journalist

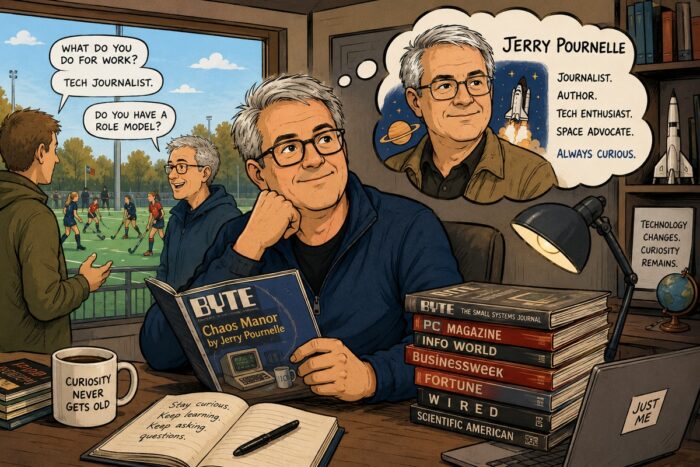
Recently, I was standing beside a hockey field, watching one of my daughters play a match. Like so often happens at these events, conversations with other parents started. At some point, someone asked me: “What do you actually do for work?” I explained that I am a technology journalist. That naturally led to a conversation about technology, innovation and the way the world is changing.

After a while, he asked me a interesting question: “Do you have a kind of role model? Someone you consider to be a really great technology journalist?” I did not have to think for even a second. “I guess that would be Jerry Pournelle,” I said.

For many people today, that name probably does not immediately ring a bell. But for me, Jerry Pournelle represents something that has always been at the heart of technology journalism: curiosity.

Pournelle was not just a journalist. He was also a science fiction author, a computer enthusiast and someone who had a deep connection with the world of space exploration. For many years, he wrote the famous “Chaos Manor” column for Byte magazine, one of the most influential computer magazines of its time. His writing was different from many traditional technology articles. He did not simply describe products or repeat announcements from vendors. He experimented. He built things. He tested technology himself and shared his experiences, including the problems and frustrations he encountered along the way.

That was what made him special. He approached technology as something you had to understand by using it. He was not only interested in what a computer could do according to a specification sheet. He wanted to know what happened when a real person worked with it. Learning by building and experimenting.

I became a technology journalist in a time when technology magazines were still big and influential. I remember waiting for those international technology publications to arrive. Computerworld, PC World, NetworkWorld, Byte. When the latest issues came in, I immediately wanted to take them home. I loved those magazines. In the evenings I used to read them back to front.

At the publishing company where I worked, we had a library with many international business publications. Magazines like BusinessWeek and Fortune were primarily there for the management team. They were considered important reading for directors and executives. But I was fascinated by them too. Whenever I had the chance, I would “steal” those magazines from the library and read them at home. I wanted to understand what was happening beyond the world of IT. What were companies thinking about? Which technologies were changing industries? How were leaders looking at the future?

Looking back, I realize that those moments shaped the journalist I became. Technology journalism is not only about knowing the latest processor, ERP-solution, 4GL tool, cloud platform or software release. It is about understanding the bigger picture. It is about being curious about people, businesses, society and the impact of technology.

That is exactly what I admired about Jerry Pournelle. Even at an age when many people would have slowed down, he remained incredibly active and curious. He continued writing, experimenting and exploring new developments. Technology kept changing around him, but his curiosity never disappeared.

I am younger than Jerry Pournelle was when he was still actively writing, but I recognize that same curiosity. I still enjoy discovering new technologies, reading about unexpected developments and diving into subjects I know little about. Whether it is artificial intelligence, space exploration, digital autonomy or completely new ideas that appear out of nowhere, there is always something new to learn.

And that might very well be the most important lesson from people like Jerry Pournelle. Technology changes constantly. The tools we use today will eventually become outdated. The platforms we consider revolutionary will one day be replaced. But curiosity remains. Or maybe I should say: curiosity needs to remain.

Because that is what makes a great technology journalist like Jerry Pournelle. Not the ability to predict the future perfectly. Not knowing every technical detail. But having the desire to keep asking questions, keep experimenting and keep learning.

I see that Jerry’s website is still available at https://www.jerrypournelle.com/.

in Tech | 697 Words