Building Robots Is Not Enough

I keep coming back to the same question when writing about European technology: what exactly do we want to keep in Europe? The usual answer is something like: semiconductor production, cloud infrastructure, AI models and perhaps a few strategically important factories. But after reading about French robotics company Wandercraft (https://en.wandercraft.eu/) and its cooperation with Renault, I think there is another part of the story that deserves much more attention. Europe should not only build products. It should also build the machines that build those products.

That may sound slightly old-fashioned in a world where almost every discussion about technology quickly turns into a discussion about software and AI. But there is a very practical reason for it. If you build your own production machines, you learn from them. You discover that a certain component is unnecessarily expensive. That another part could be lighter. That a production step takes too long. That a tolerance does not need to be quite so precise. Or that changing some software, mechanics or electronics could make the entire production process better.

In other words, a factory is not simply a place where products come off a production line. It is also a rather large laboratory.

Robots building European industrial knowledge

Wandercraft is an interesting example. The French company originally developed robotic exoskeletons for people who have difficulty walking. More than ten years of developing balance systems, actuators, mechanics and control software eventually resulted in something else: Calvin, a humanoid robot designed for industrial work.

And importantly, this isn’t primarily a robot designed to dance on a stage or generate spectacular YouTube videos. It is designed to work in a factory. Renault is already testing Calvin in its factory in Douai, where the robot moves things such as car tyres. Renault plans to have around 350 humanoid robots working in its French and Spanish factories by the end of 2027.

But the really interesting part is the relationship between the two companies. Renault is not simply buying robots from Wandercraft. It is also helping the company figure out how to manufacture those robots at scale. Wandercraft brings robotics and AI knowledge. Renault brings decades of experience in mass production, supply chains, quality control and designing products that can actually be manufactured at an acceptable cost. That combination makes a lot of sense.

Keep the feedback loop close

There is another detail I particularly like. Wandercraft says the components in its current robot all come from Europe. That matters. Because if the robot is designed in Europe, manufactured using European components, deployed in European factories and improved based on what happens in those factories, you create a very useful feedback loop: engineers see what breaks, factories discover what works, production specialists improve how the robot itself is manufactured and developers adjust the software and control systems. And then you do it all over again. That is industrial knowledge being created continuously. Move too many parts of that chain elsewhere and eventually part of that knowledge moves with it.

Europe already has an enormous high-quality manufacturing base, many specialised machine builders and companies that know how to manufacture complicated products at scale. We sometimes seem strangely eager to underestimate how valuable that is.

Perhaps technological sovereignty is not only about owning an AI model or running a European cloud. Sometimes it is also about knowing how to build the machine that builds the machine.

Here is a video of Andreas Klinger from the European investment fund PROTOTYPE (https://www.prototypecap.com/) visiting Wandercraft.

School Directors Are Making the Wrong Choice Between Tech and Privacy

I came across an article by Privacy First about the digital student, and it touches on something that continues to bother me about the way we discuss technology in European education. The discussion is often framed as a choice: we can embrace digital technology in schools, or we can protect the privacy of our children.That is the wrong choice.

You can find the article here: https://privacyfirst.nl/artikelen/de-digitale-leerling/ (text in Dutch). Privacy First rightly points out that schools process enormous amounts of information about pupils, ranging from names and contact details to school results, behaviour and sometimes information about a child’s development. Children are particularly vulnerable because they usually have little choice about the software their school tells them to use.

But the conclusion shouldn’t be that schools therefore need less technology. They need different technology: technology that respects privacy and complies with privacy laws.

Digital does not automatically mean Google

There is absolutely no law of nature saying that digital education requires Chromebooks, Google Workspace, Microsoft 365, Windows laptops or MacBooks. A school can give students Linux laptops. It can use Nextcloud or similar open source platforms for storing and sharing files, working together on documents, calendars, video calls and all the other things schools nowadays expect from a digital workplace.

And before somebody says that this sounds nice in theory but could never work for hundreds of thousands of users: it already does. The French region Île-de-France has deployed a sovereign collaboration environment based on Nextcloud for around 550,000 pupils, teachers and administrative staff. The system is part of the regional monlycée.net environment and was explicitly designed as an alternative to Microsoft solutions. It includes document collaboration through Collabora Online, file storage and integration with the region’s existing systems. The infrastructure is operated in France.

You read that right: half a million users. So perhaps we can finally stop pretending that European and open source alternatives are lovely little hobby projects that might work for three enthusiasts and a Raspberry Pi. See https://nextcloud.com/fr/blog/cloud-souverain-plateforme-collaborative-ile-de-france/ for more information.

We became lazy buyers of IT

There is another part of this discussion that I think we don’t talk about enough. A Belgian CIO recently said something to me that stuck: we have forgotten that we actually have to make conscious choices ourselves.

For many years it was incredibly easy not to choose. Microsoft was already there, so you bought some more Microsoft. Your organisation was using AWS, so the next workload went to AWS as well. Google offered a complete education package, so schools bought Chromebooks and Google services.

You could call that standardisation. I increasingly call it convenience. Or perhaps there is a better word for it: laziness. And that is dangerous, because over time, that convenience has turned into dependency.

That dependency matters much more today than it did ten or fifteen years ago. Europe has become deeply dependent on a relatively small number of American technology companies for cloud computing, productivity software, communication and increasingly AI. In their article, Privacy First has made essentially the same broader point about Europe’s dependence on foreign technology providers and the consequences for autonomy and control over data. With today’s geopolitical uncertainty, treating that dependency as merely a procurement detail is becoming increasingly difficult.

Of course you cannot migrate an entire organisation in a day. Nobody sensible is suggesting that. Île-de-France didn’t do that either. But that argument is rapidly becoming an excuse. If you are responsible for IT in a sizeable European organisation and you are still not investigating alternatives, testing them, identifying dependencies and developing a realistic migration path, I think you have a problem. Migration takes years. Which is precisely why you need to start before circumstances force you to.

And then there are the children

There is something particularly uncomfortable about teaching children about privacy, data protection and digital literacy while at the same time making them use platforms built by some of the world’s largest data-driven technology companies. Privacy First argues that privacy should not simply be another compliance box for schools to tick. It should be a basic design principle of the digital environment children grow up in.

I couldn’t agree more with that conclusion. We have GDPR. We have endless discussions about children’s online safety. We teach pupils to think carefully about what they share online. And then institutions themselves make the fundamental technology choices on their behalf.

Schools deserve support from governments and IT specialists to make better choices. But eventually somebody also has to take responsibility. The technology exists. The alternatives exist. Large-scale examples exist. Île-de-France is already showing that hundreds of thousands of pupils and teachers can work digitally without simply handing the entire environment to Microsoft or Google.

So this really isn’t a discussion about digital versus privacy. It is about whether school directors are willing to do the homework required to have both.

You’re Not Just Publishing Posts. You’re Building a Habit for Your Readers

I only discovered Blaugust when August was almost over. Which is slightly unfortunate, because I like the idea.

Blaugust is one of those wonderfully IndieWeb-ish initiatives where people encourage each other to blog more. See for more here: https://tagn.wordpress.com/2026/07/21/. It originally started as a challenge to publish every day during August, although over the years it has become somewhat less strict. The idea now seems to be at least as much about participating, meeting other bloggers and keeping personal blogging alive.

Sebastian Malloy participated this year and wrote an interesting post about what the experience taught him (https://sebastianmalloy.bearblog.dev/what-blaugust-has-taught-me-about-my-blogging/). He managed 30 posts in 31 days, but discovered that producing something simply because today’s post still had to be produced wasn’t really for him. Some posts felt as if they existed mainly because there was a quota to meet. What he did enjoy was reading what everybody else had written.

I didn’t participate in Blaugust. There are several reasons for that. The most obvious one is that I already publish something on Just Me almost every day. So adding a challenge to make me write regularly would be slightly odd. The other reason is much simpler: I discovered Blaugust too late. Maybe next time.

There is a whole world of these things

What surprised me is that Blaugust isn’t some isolated event. There appears to be an entire world of challenges built around the simple idea of committing yourself to making things.

There is 100 Days To Offload, for example, where the challenge is to publish 100 posts on your personal blog within 365 days (https://100daystooffload.com/). And the rules explicitly say those posts don’t have to be long, profound or particularly polished. The important part is to write.

Then there is the IndieWeb Carnival (https://indieweb.org/IndieWeb_Carnival). Every month another blogger chooses a subject and other bloggers write their own posts about it. At the end of the month, the host collects the contributions. The IndieWeb wiki actually describes one of its purposes as motivating people to publish more on their personal websites and giving them inspiration for things to write about.

And there are many more. The DS106 Daily Create (https://daily.ds106.us/) offers small daily creative assignments involving photography, drawing, audio, video and writing. There are similar initiatives for musicians, pixel artists, zine makers and people building websites. There is even a site that collects these challenges.

And, of course, there is NaNoWriMo or National Novel Writing Month (https://nanowrimo2.com/), probably the best-known variation on the general idea: commit to creating something, set yourself a target and do it together with other people.

In other languages we see the same (more or less). In Germany there are quite of few challenges as well. See for example here https://judithpeters.de/50-blogparaden-im-sommer-2026/. I found fewer direct French-language blogging equivalents. There are plenty of French community writing challenges, though. For example, Scribonautes (https://scribonautes.fr/a-propos/) runs ongoing “défis d’écriture” where participants respond to community-created prompts and read and vote on each other’s work. It is closer to creative writing than personal blogging, but the community/regular-creation principle is very similar.

I find all this fascinating. Not necessarily because I need somebody to tell me to write another blog post. At the moment, I have rather the opposite problem. There are far more things I want to write about than I have time for. But these challenges provide something else. They are a very nice way to discover people. You follow links to participants, encounter blogs you have never seen before and suddenly end up reading about someone’s record collection, Linux setup, garden, travels, books or strange little hobby you didn’t know existed. That might actually be the most interesting part.

But what if you have nothing to say?

There is another side to all this. Sebastian Malloy’s experience also points to an obvious problem with publishing challenges: what happens when you simply have nothing you consider interesting enough to publish? I recently came across this post, Why People Quit Blogging (see here: https://unattributed.cc/2026/08/27/why-people-quit-blogging/), which looks at some of the reasons people eventually stop.

It certainly isn’t an exhaustive list, but I think the question itself is interesting. Starting a blog is easy. Continuing one for years is something else entirely. Perhaps you run out of subjects. Perhaps life changes. Perhaps writing starts feeling like an obligation. Or perhaps you begin wondering whether anybody is actually interested in what you have to say.

Challenges such as Blaugust, 100 Days To Offload and the IndieWeb Carnival can probably help with that. They provide a reason to sit down again. A subject. A small deadline. And, importantly, other people who are doing exactly the same thing.

Your readers notice when you disappear

But I think there is another reason to keep going that bloggers themselves may underestimate. What bloggers perhaps don’t always realise is that readers aren’t only interested in subjects. Over time, they also become interested in you. They want to know what you have discovered. What you are doing. What you think about something. Which book you are reading. Which piece of software you are experimenting with. Or why something completely ordinary suddenly caught your attention.

That creates a small social connection. It is very different from following a professional publication where another author can simply take over. A personal blog has a person attached to it. That person is part of the reason people return. And once you establish some kind of rhythm, people get used to that rhythm too. If it suddenly changes, I suspect some regular readers really do notice. Not necessarily in a dramatic way. Nobody will organise a search party because you haven’t published anything for four days. But perhaps there is a tiny moment of disappointment when they check your blog or their RSS reader and there is nothing new. Oh. You’re not here today.

I think that is rather nice. And perhaps that small relationship between writer and reader is something worth remembering whenever blogging starts to feel like talking into an empty room.

This is Why I Love Hackers So Much

Years ago I read The Cuckoo’s Egg by Cliff Stoll. It is one of those technology books that somehow sticks in your memory, probably because it hardly feels like a technology book at all. It is more like a detective story, except that the detective is an astronomer turned system administrator, the clues are hidden inside Unix systems and telephone networks, and the whole thing starts with an accounting discrepancy of just 75 cents.

That tiny discrepancy eventually led Stoll into a year-long hunt for cyber criminals who were breaking into American computer systems and passing information to the East German Stasi and the Soviet KGB. This was 1986, long before cybersecurity became an industry filled with SOCs, SIEMs, threat intelligence platforms and impressive-looking dashboards.

I hadn’t thought about the book for a long time. Then I came across a recent video of Stoll speaking at DEF CON 34, forty years after that original 75-cent discovery. And yes, he is quite a remarkable presenter.

No cyber, just curiosity

Stoll describes how they had essentially none of the tools we now associate with cybersecurity. There was no budget, no roadmap and not even much of a vocabulary for what they were doing. Instead, they used soldering irons, shell scripts, printers, logbooks and lots of improvisation.

Watching him talk about it reminded me why I have always liked the world of developers and hackers so much. Not the criminal kind of hacker, obviously, but the original meaning of the word: people who are intensely curious about how things work. People who see something strange and immediately want to understand why. People who happily open things, connect things that were never supposed to be connected, write a little piece of software to solve a problem and then build something slightly ridiculous because it might just work. Stoll seems to embody that attitude almost perfectly.

Following the strange little clue

There is also something wonderfully old-fashioned about the whole story. Today, a 75-cent discrepancy would probably generate a ticket somewhere. It might be assigned a severity level, automatically enriched with telemetry and eventually end up on somebody’s dashboard. Stoll simply wanted to know why the numbers didn’t add up. And that curiosity turned a tiny accounting error into an investigation that crossed networks and international borders.

Technology has changed enormously since then. The internet has changed. Cybersecurity has become a huge professional industry. Attackers have changed too. But perhaps one thing hasn’t changed at all. Someone still has to look at something slightly unusual and think: That’s strange. I wonder why that happened. And then keep digging.

Maybe that is why I enjoyed watching Stoll’s presentation so much. It isn’t only an interesting piece of computing history. It is also a reminder that some of the most interesting things in technology still start with curiosity, experimentation and somebody refusing to ignore a tiny detail. That wonderfully stubborn, slightly (very?) eccentric hacker mentality.

I hope we never professionalise it out of existence.

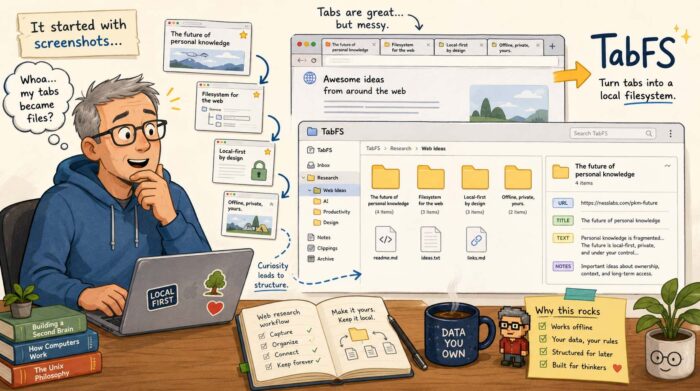
I Went Looking at a Conference About Screenshots (About What?) and Found a Filesystem for Browser Tabs

Sometimes you find interesting software because you are looking for it. And sometimes you arrive there through a rather strange series of clicks. TabFS definitely belongs in the second category.

It started with a very short message I saw somewhere about something called Screenshot Conf (https://cristobal.arquipelago.org/writing/screenshot.html). My first reaction was more or less: a conference about screenshots?

Obviously, I had to know more. And yes, Screenshot Conf really was a conference entirely about screenshots. It was organised in New York by Cristóbal Sciutto and Omar Rizwan, with talks about things such as screenshot archives, information storage, image-based computing and the surprisingly important role screenshots play in the way we collect and share information. I will come back to Screenshot Conf in another post, because I have the slightly strange feeling that I have just discovered an entire world I didn’t know existed.

But Screenshot Conf also led me to the website of one of its organisers, Omar Rizwan (https://omar.website/). And that turned out to be another rabbit hole.

Turning browser tabs into files

Rizwan is interested in new computer interfaces and new ways of programming. His website contains a collection of experiments and projects that approach computers in ways that are often very different from the standard application-and-window model we are used to. One of those projects is TabFS (https://omar.website/tabfs/).

The idea is wonderfully strange: TabFS turns the tabs in your web browser into something that looks like an ordinary filesystem on your computer. Every open browser tab becomes a directory. Inside that directory are files representing things such as the URL, the title and the text of the page. Those aren’t simply exported copies. They reflect the current state of the browser tab. So suddenly your browser becomes accessible using all those boring old tools computers have been very good at for decades: files, directories, shell commands, scripts, text editors and file managers.

Your browser becomes scriptable

And that is where it becomes interesting. Suppose you have 40 tabs open while researching something. With TabFS, you can simply list the titles of those tabs as if you were reading files from a directory. You can also save the text of all your open tabs into one file. Or search those files. Or process them with Python. Or write a little shell script that selects certain tabs. Rizwan gives the example of closing every tab containing “Stack Overflow” in its title. Instead of building a special browser extension, you can essentially delete those tabs as if you were deleting files.

TabFS can go considerably further. It can expose images, JavaScript and other resources loaded by a page as actual files. You can evaluate JavaScript on a page through the filesystem, monitor values on a page and use scripts on your computer to interact with what is happening inside the browser.

It is experimental software, and some of the ideas Rizwan describes are explicitly still TODOs. But that almost makes it more interesting.

Browsing as information gathering

What particularly interests me is what this could mean for people who spend much of their day collecting information. That is basically what I do continuously. I open articles, reports, company websites, research papers, videos and all sorts of other sources. Some are immediately useful. Others might become useful several days or months later.

The browser is very good at finding and displaying all that information. It is much less good at turning it into something you can systematically work with afterwards. Bookmarks help, of course. So do read-later services and knowledge management tools. But they usually introduce yet another application and yet another database.

TabFS approaches the problem from an entirely different direction. It says: what if the browser simply became part of the filesystem?

Then you could write a script that periodically stores the text and URLs of your research tabs. You could sort them into project directories. You could use command-line tools to search through them. You could feed selected material into another processing workflow. You could create an archive containing the source URL, page title and extracted text. And because we are dealing with ordinary files, you could potentially combine this with almost anything else that understands files. That includes tools which haven’t even been designed to work with browsers.

I like this kind of software

TabFS probably isn’t something most computer users are going to install tomorrow. Its current setup requires a browser extension and a filesystem component, and Rizwan describes Chrome support as the main target, with more limited Firefox and Safari support. It currently runs on macOS and Linux.

But that isn’t really the point for me. What I like about projects like TabFS is that they question assumptions that have become so normal that we rarely notice them anymore. Why should information inside a browser be trapped inside a browser? Why shouldn’t my existing tools be able to access it? And why do we keep building separate applications for managing information when operating systems already have a perfectly good universal abstraction for storing and manipulating things?

I really like unpredictable journeys like that. I started out wondering why anyone would organise a conference about screenshots. A few clicks later, I found myself thinking about browsers as filesystems. Not a bad rabbit hole to fall into.

The Web Has a Memory Problem

I recently came across a post on Ctrl+Shift+3 from someone who had found an old backup of their del.icio.us bookmarks (https://ctrlshift3.com/post/cQHW0GSYNypR). The conclusion was concise and predictable: roughly 75 percent broken links and 80 percent obsolete technology. It made me sigh, because it reminded me of something I’ve been thinking about for quite a while: link rot.

Link rot is simply what happens when links that once worked stop taking you to the information they originally pointed to. A website disappears, an article is removed, a company changes its CMS, pages get reorganised or an entire domain simply vanishes. The result is the familiar 404 page, a redirect to somewhere irrelevant, or sometimes a completely different page at the same address.

And it happens a lot. A recent 20-year study of almost 2900 web citations found that accessibility dropped from 87 percent for citations less than five years old to only 38 percent for those more than ten years old. You can find the study here: https://www.sciencedirect.com/org/science/article/pii/S2050380626000220. That is quite a problem for something we tend to regard as permanent.

Why I don’t use URL shorteners

Link rot is also one reason why I prefer using the actual URL when I link to another website instead of putting a URL-shortening service in between. There is a very practical advantage: you can immediately see where you are going. A link beginning with w3.org, github.com or the website of a newspaper tells me considerably more than an address such as bit.ly/3Xf92Kd.

But there is another reason. A URL shortener adds an extra dependency. Instead of:

my website → source

you get:

my website → shortening service → source

That shortening service now controls all those redirects. If it disappears, changes the way it works, gets acquired, loses data or simply decides to discontinue the service, a potentially enormous collection of links can stop working overnight. It seems “slightly” strange to me to deliberately introduce another possible point of failure into something that is already rather fragile.

Of course, using the original URL doesn’t solve link rot either. If the original page disappears, the link still breaks. But at least there is one less organisation involved in keeping the link alive.

Keeping your own URLs boring

The Unattributed article “Digital Legacy: Link Rot Mitigation Issues” (https://unattributed.cc/2026/08/23/digital-legacy-link-rot-mitigation/) approaches the problem from the perspective of preserving a website over a long period. That is an interesting way of looking at it, because preventing link rot isn’t only about the sites we link to. It is also about the links other people create to us.

One of the most useful principles is actually very boring: don’t unnecessarily change URLs. If an article lives at a particular URL today, keeping it there for the next ten or twenty years is probably one of the best things you can do. The US Library of Congress makes the same recommendation: maintain stable URLs and, when a URL really has to change, redirect the old address to the new one. (https://www.loc.gov/programs/web-archiving/for-site-owners/creating-preservable-websites/)

That sounds obvious, but website redesigns have a remarkable ability to destroy perfectly good URL structures. A new CMS gets installed, /blog/interesting-article.html suddenly becomes /posts/2026/interesting-article, nobody bothers to create redirects, and thousands of old bookmarks and incoming links instantly become useless overnight.

Archive what matters

Another important defence against link rot is archiving. If I refer to something that is particularly important to an article, I can save the page in the Internet Archive’s Wayback Machine (https://web.archive.org/) or use a service such as Perma.cc (https://perma.cc/). That gives readers another route to the information if the original disappears.

This is especially useful for pages that are likely to change while keeping the same URL. Think of government policy pages, documentation, company announcements or so-called living documents. In those cases you can have something slightly different from link rot: content drift. The URL still works, but the information behind it is no longer what you originally referred to.

For sources like these, preservation guidance increasingly recommends keeping both the live URL and an archived snapshot. Have a look here for an interesting article about this topic: https://casrai.org/guides/link-rot-in-citations-and-how-to-prevent-it

For academic papers, reports and datasets, there is another option: use a persistent identifier such as a DOI whenever one exists (https://en.wikipedia.org/wiki/Persistent_identifier). The entire idea behind these identifiers is that the identifier remains the same even when the actual location of the document changes.

Give readers enough information to recover a link

There is also a wonderfully low-tech solution: don’t make the URL the only information you provide. When referring to an interesting article, mention its title, author and website. If the link dies in five years, someone can still search for it. If all I write is “read this” behind a hyperlink, the reader has almost nothing to work with once that link disappears.

The same applies to my own bookmarks. Saving only a URL isn’t particularly useful if that URL later breaks. A title, short note and perhaps publication date make the bookmark much more valuable as a record of what was actually there. Perhaps that old del.icio.us backup illustrates this perfectly. A dead URL on its own is almost meaningless. A dead URL combined with a title and description can still tell you what you once found interesting.

Check your old links

There is one final, rather mundane solution: occasionally check links. There are plenty of tools that can crawl a website and report broken external and internal links. Examples are LinkChecker (https://github.com/linkchecker/linkchecker) or Broken Link Checker (https://github.com/stevenvachon/broken-link-checker). For a small personal website you could run such a check every now and then and repair the links that matter. Sometimes the article simply moved. Sometimes there is an archived version. Sometimes another reliable source covers the same information.

But I wouldn’t turn this into an endless maintenance project either. Because ultimately link rot cannot be solved completely. Someone else’s website can disappear tomorrow. A company can close. A domain registration can expire. An organisation can deliberately remove twenty years of old material. Even archives cannot preserve everything, particularly today’s highly dynamic websites.

Perhaps the goal therefore shouldn’t be to create a Web in which no link ever dies. It should be to make links less disposable. Use stable URLs. Avoid unnecessary intermediaries. Redirect old pages when you move them. Archive important sources. Use persistent identifiers when they exist. And leave enough context around a link so somebody has a chance of finding the information again. Because the Web may look permanent when we use it every day. That old del.icio.us backup suggests otherwise.

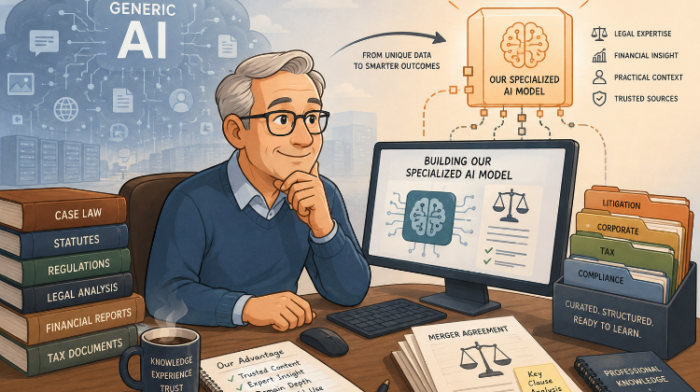
Why Thomson Reuters’ Own AI Model Is More Interesting Than It First Seems

Thomson Reuters has launched its own AI model, called Thomson, and I think the most interesting part of the story is not that yet another company has built an AI model. It is how they did it.

You can read the original press release here: https://www.thomsonreuters.com/en/press-releases/2026/august/thomson-reuters-leverages-its-world-class-data-assets-to-launch-its-own-frontier-model. I wrote about it here (text in Dutch): https://ai-visie.net/thomson-reuters-bouwt-eigen-frontier-ai-model/.

Thomson Reuters is not trying to beat OpenAI, Google or Anthropic by training a gigantic general-purpose model from scratch. Instead, it started with an existing open model and then trained and specialised it using its own data and expertise. The company reportedly invested around $40 million in talent and compute. That is still a serious amount of money, of course. But compared with the billions now being spent on the largest frontier models, it is almost modest.

The real advantage may be the data

Thomson Reuters has something most companies simply do not have: decades of highly structured, professionally maintained legal, tax and financial information. That may turn out to be much more valuable than simply having access to more GPUs.

For certain legal tasks, Thomson Reuters says its model can compete with, and in some cases outperform, much larger general-purpose frontier models. That makes sense. A specialised model does not need to be brilliant at everything. It needs to be exceptionally good at the tasks for which it was designed.

And that raises an interesting question. If Thomson Reuters can do this, why don’t more large companies simply build their own frontier models?

Because having lots of data is not enough

Many large organisations have enormous amounts of data. Banks have transactions. Manufacturers have huge amounts of product(ion) data. Telecom companies have network data. Healthcare organisations have huge collections of medical information.

But having data and having usable AI training data are two very different things. Corporate information is often scattered across thousands of systems, poorly structured, duplicated, lacking useful meta data, outdated or difficult to use because of privacy, intellectual property and compliance restrictions.

Then there is the technology itself. Training and maintaining a serious model still requires specialised AI engineers, infrastructure, evaluation methods, security expertise and a lot of compute. And once the model exists, you have to keep operating, testing and improving it.

So perhaps the interesting lesson from Thomson Reuters is not that every large organisation should now build its own model. It is that some organisations may have a very valuable combination: unique data, deep domain knowledge and enough resources to turn an existing open model into something that is better than a general-purpose AI system for their particular field.

Maybe “frontier” is becoming more specialised

I find that a particularly interesting development. Until now, we have tended to think of frontier AI as a race to build ever larger models. More parameters, more compute, bigger clusters. But perhaps there will also be another kind of frontier: not a model that knows everything, but one that knows one domain exceptionally well.

For companies sitting on decades of carefully curated specialist knowledge, that could make owning at least part of their AI stack increasingly attractive. And it may also change the AI discussion inside companies. The question may no longer simply be: which frontier model should we buy? It could increasingly become: What knowledge do we have that nobody else has, and can we turn that into our own AI advantage?

China is Doing what Europe keeps Talking about — But Moving Much Faster

I recently went looking for a story I remembered reading about China replacing Windows with Linux. I could not find it at first, probably because I was searching for the wrong thing.

There is no single Chinese order saying that everybody has to throw Windows out. What China has been doing is much more interesting: step by step, it has been reducing its dependence on foreign technology, particularly within government organisations, state-owned companies and strategically important sectors.

The name that keeps coming up is Xinchuang, China’s programme to replace foreign technology with domestic alternatives (https://www.mof.gov.cn/jrttts/202312/t20231226_3924138.htm). That includes processors, databases, applications and operating systems. Chinese government procurement rules introduced in recent years increasingly require systems to meet domestic “safe and reliable” requirements. In practice, that has created much more room for operating systems such as Kylin and UnionTech UOS, both based on Linux.

And China has just taken another step. In August 2026, reports emerged (for example https://www.tomshardware.com/software/operating-systems/china-reportedly-orders-state-agencies-to-uninstall-its-government-only-edition-of-windows-10) that China’s Ministry of State Security had instructed some state-linked organisations to remove Windows 10 China Government Edition earlier than originally planned. This is important nuance: China has not banned Windows everywhere. The order concerns a special government version and a limited part of the Chinese market. Windows is still widely used by consumers and businesses.

Perhaps we should pay more attention to China

Still, I think the direction is interesting. Not because Europe should copy China’s political system or its approach to technology. Obviously not. But there is one thing China seems to understand very well: becoming extremely dependent on a handful of foreign technology companies is a strategic risk.

That is something Europe has been talking about for years. Digital sovereignty, strategic autonomy, European clouds, open source, sovereign AI. Plenty of conferences, reports and policy documents. But meanwhile we keep buying. And buying. And buying.

The numbers are rather impressive. A European Commission document published this year cites research estimating that European companies’ purchases of cloud software add around €264 billion annually to the US economy (https://eur-lex.europa.eu/legal-content/EN/TXT/?qid=1745691400115&uri=CELEX%3A52026SC0502&)

Then there is the price issue. Research commissioned by French CIO association Cigref found that European organisations saw cloud and software costs increase by an average 8.7 percent per year during the past three years. Some organisations experienced much larger increases when contracts were renewed. The same research expects average annual increases of around 12 percent during the coming five years. (https://www.cio-platform.nl/en/weblog/nieuws-extern-detailpagina/2026/07/02/rapidly-rising-cloud-and-software-costs-weigh-on-the-european-economy?)

That 8.7 percent figure is not specifically an “American cloud inflation rate”, so we should be careful with that. But combine rapidly increasing software and cloud prices with Europe’s enormous spending on predominantly American technology and it becomes clear that we are talking about very serious amounts of money. Digital sovereignty is therefore not just about geopolitics. It is also about economics.

I decided to start with myself

I have been gradually trying to reduce my own dependence on Big Tech. My laptop comes from a European company (Slimbook), although calling a computer completely European is almost impossible: the CPU and GPU in mine are from AMD. I use Linux as my operating system. Nearly all the software and cloud services I use are now European, open source, or both.

I came from a MacBook and an iPhone and switched to Linux Mint and Murena /e/OS, a de-Googled version of the open-source version of Android. And to be honest, it works differently in some ways, but certainly not worse.

So personally, I made the switch, and I’m perfectly happy with the result. The difficult part is often not my own technology. It is other people’s technology. Clients still invite me into SharePoint environments. People create WhatsApp groups and simply assume everybody uses WhatsApp. Publishing workflows are still often built around Adobe software. In those situations, digital independence suddenly becomes less of an individual decision. You are part of an ecosystem, and ecosystems are difficult to leave.

But migration costs money…

This is probably one of the biggest obstacles Europe faces as well. One argument I often hear is that replacing existing technology is expensive and risky. Of course it is. If an organisation has spent ten or twenty years building processes around Microsoft 365, Azure, AWS, Google Cloud or Adobe, you cannot simply switch everything off on Friday afternoon and start again with European alternatives on Monday morning. People have to be trained. Applications have to be migrated. Interfaces have to be rebuilt. Data needs to move. Some functionality may not have an equivalent. And some projects will undoubtedly go wrong.

So yes, reducing dependency costs money. But keeping the dependency has a cost too. And that part of the calculation seems to receive much less attention – even by business managers who consider themselves financially savvy. What happens if prices continue to rise by almost 9 percent every year? What happens if a supplier changes its licensing model? What happens if political relations deteriorate badly? And, perhaps the uncomfortable question: what happens if access itself becomes part of a geopolitical conflict?

Canada suddenly makes that question less theoretical

This is why I am watching the current trade conflict between Canada and the United States with some interest. See for example here: https://www.reuters.com/business/trump-time-teach-canada-you-cant-do-this-anymore-2026-08-26/?. Relations between two countries that have been extremely close economic partners for decades have deteriorated remarkably quickly. In August, the US imposed 50 percent tariffs on roughly $20 billion worth of Canadian goods, after which Canada announced matching retaliatory measures.

So far, this is a trade conflict involving physical goods and tariffs. I have seen no evidence that the US government intends to restrict Canadian access to Microsoft 365, Azure, AWS, Google Cloud or other American digital services. But it does raise an interesting question.

Could digital services eventually become economic or political leverage as well?

I don’t know. And that is precisely the problem.

For years we have treated cloud platforms, office software and other digital services almost as utilities. They are just there. We log in every morning and assume they will still be there tomorrow. China clearly doesn’t want to make that assumption. Europe shouldn’t either.

We don’t have to replace everything tomorrow. That would be unrealistic and probably counterproductive. But we could start doing exactly what China has been doing for years: identify dependencies, develop alternatives, change procurement policies and gradually move critical systems to technology over which we have more control. We do not need yet another conference about digital sovereignty. Not another declaration.

What we do need: start migrating. Because the best moment to reduce a dependency is probably while everything is still working.

AI and Art: Maybe the Interesting Part Is Somewhere in the Middle

Every now and then I watch a presentation about AI that actually adds something to the discussion. Jack Conte’s recent talk at SXSW is definitely one of those. Conte is not only the CEO and co-founder of Patreon, but also a musician and filmmaker himself, which probably explains why his presentation feels so personal. And passionate. Very passionate.

His SXSW session took place in Austin in March 2026, and the video has since been published as The future of creativity on the internet in a world with AI. Conte clearly struggles with AI himself. He is excited about what the technology could make possible, but at the same time angry about what is happening to artists and their work. That conflict is exactly what makes his presentation so interesting.

We have been here before

Conte spends quite a bit of time looking back at previous technological changes. Film initially copied theatre. Recorded music disrupted musicians playing live in cinemas. Synthesizers created fears that orchestras and musicians would become unnecessary. New technology repeatedly destroys existing business models, after which artists start figuring out what they can do with the new technology that simply wasn’t possible before.

He believes generative AI is currently going through a similar phase. Much of what we now see is what he describes as AI “slop”: technology being used mainly to imitate things we already know. Generate another picture. Another song. Another video. Another piece of text. Faster, cheaper and in almost unlimited quantities.

I think that distinction is important.

The debate about AI and creativity has become incredibly black and white. On one side are people who want nothing to do with AI-generated music, images or text because a human didn’t make it in the traditional sense. On the other side are people who seem determined to use AI for virtually everything.

I don’t find either position particularly useful.

Making more isn’t necessarily creating more

I use AI myself, including when writing. So obviously I don’t believe that using AI automatically makes something worthless. But there is a big difference between using AI as a creative tool and simply switching on some sort of content machine that produces hundreds of songs, articles or images because you hope to make money from the volume.

That doesn’t particularly interest me. What does interest me is someone taking these new tools and trying to do something genuinely new with them.

This is also where Conte makes an interesting point about creativity. Today’s AI models have learned from enormous amounts of existing human work. They are extraordinarily good at recognising patterns and recombining what already exists. That can produce impressive results, but it is fundamentally different from a human artist deliberately taking a creative risk, developing an unusual idea or deciding to make something nobody asked for.

Conte puts a lot of emphasis on precisely that human element. Art, in his view, is connected to difficulty, scarcity, risk and the person behind the work. We don’t just listen to music because certain sounds have been arranged correctly. We are also interested in the person who made it and what that person was trying to express.

Use AI to make your ideas possible

That is a much more useful way to look at AI and creativity. Don’t ask AI to come up with as much stuff as possible. Come up with ideas yourself and see whether AI can help you realise ideas that previously would have been too difficult, expensive or perhaps even impossible.

That applies to music, photography and video, but just as much to writing. AI can help me research, experiment, restructure, translate, challenge an argument or try a completely different approach. But there still has to be an idea. A reason for creating something.

That is why I like the double feeling in Conte’s presentation so much. He doesn’t pretend everything about AI is wonderful. Far from it. He is highly critical of how creators have been treated, including the use of their work for AI training without permission, attribution or compensation. At the same time, he refuses to conclude that the technology itself can therefore bring nothing worthwhile to art.

That middle ground is where this discussion becomes much more interesting to me. AI can produce more. Much, much more. But producing more isn’t the same thing as having a new idea. And perhaps the artists, musicians and writers who understand that difference will eventually do the most interesting things with AI.

Your AI Tool May Be Using More of Your Data Than You Think

I use AI tools a lot. And like many people, I have gradually become accustomed to typing quite a lot of information into them: ideas, drafts, questions, pieces of text and sometimes work-related information. That makes a recent piece of research highlighted by Cybernews rather uncomfortable reading.

Here is the full article: https://cybernews.com/ai-news/ai-companies-lack-disclosures-on-data-training-and-retention/. The research comes from the Production AI Institute, which created an AI Data Use Index covering 63 AI products. It looked at what companies publicly disclose about the use of customer and user data: whether data can be reused for AI training, whether users can opt out, how long information is retained and whether humans may review it. Assuming the research has been carried out properly, I find the results pretty shocking.

So what exactly happens to our data?

The important point is not that all these AI companies are secretly feeding everything we type into their models. That is not what the research says. The problem is that in many cases it is surprisingly difficult for an ordinary user to determine exactly what happens to their data. According to the researchers, only a relatively small number of products clearly state that they use customer data for training, while others offer user-controlled settings or provide information that is spread across several privacy policies, help pages and product-specific terms.

That alone is worrying. With AI, we are no longer talking about entering a few search terms into a search engine. We increasingly paste complete documents, source code, meeting notes, business plans, customer information and personal questions into these systems. The more useful AI tools become, the more information we tend to give them.

One thing that becomes clear from the research is that there is no obvious industry standard for how AI companies deal with training data. Consumer ChatGPT, for example, can use conversations to improve models depending on the user’s Data Controls settings, while OpenAI says business workspace data is not used for model training by default. Perplexity has its own settings around AI data retention, while Cursor distinguishes between users who enable Privacy Mode and those who do not. Other services, including GitHub Copilot, Slack and Notion, again apply different policies.

Your data may still be stored

So the apparently simple question, does my AI tool train on my data?, often has no simple answer. It can depend on the product, the type of account you have, the subscription you pay for, your individual privacy settings and sometimes even the specific feature you are using.

That raises another question which I find even more interesting. In cases where an AI service has a setting that allows users to opt out of data being used for model training, what exactly does that opt-out mean? Does it apply immediately? Does it also cover previously stored conversations? What happens when you provide feedback on an answer? And does opting out of training also mean your information is no longer stored, reviewed for abuse prevention or shared with third-party service providers?

These are not the same things. The Production AI Institute’s research is primarily about transparency: it examines what companies publicly say about their data practices. It is not a technical audit that verifies what actually happens inside every company’s infrastructure. That means the research does not show that companies continue using data for AI training after users have opted out. But it also does not independently prove that every opt-out is implemented exactly as users might assume.

There is another distinction that deserves much more attention: not using your data for training is not the same as not storing your data. An AI provider may promise that prompts and responses are excluded from model training while still retaining them temporarily for security, abuse monitoring, troubleshooting or other operational purposes. Enterprise and API services often have separate rules again, with different retention periods and contractual protections.

For business users in particular, asking only whether an AI company trains on your data is therefore not enough. You also need to know what information is stored, for how long, where it is processed, who can access it, which third parties may receive it and whether deleting a conversation actually removes the underlying data. You should also know whether the privacy rules for a consumer account are different from those for a business or enterprise subscription.

For years, most of us have become used to clicking through privacy notices and terms of service without paying much attention. With AI, that habit is becoming considerably more risky. Both business users and private users probably need to become much more conscious about the services they use and the information they provide.

We need to pay more attention

Before using an AI tool for anything sensitive, it makes sense to check its privacy and data controls. Is model improvement enabled by default? Is there an opt-out? Does the opt-out apply to all data or only certain types of conversations? Are consumer and business accounts treated differently? And perhaps most importantly, what exactly does the company mean when it says it does not use your data for training?

I would like AI companies to make this much simpler. Every AI service should have one clearly visible page explaining in plain language what happens to everything you submit: whether it is used for training, whether that is opt-in or opt-out, how long data is retained, whether humans can review it, whether third parties receive it and whether you can permanently delete it.

That information should not require digging through five different policy documents. Because if this research is even broadly representative of the market, we have probably been paying far too little attention to a very basic question: What actually happens to our data after we press Enter?