Printed Link Rot: The Internet Problem That Escaped the Internet

A few days ago I came across an article about a rather unusual book. It is a big yellow book full of websites. A kind of printed directory of the internet. The author describes it as an “Internet Phone Book” — a physical snapshot of a digital world that changes every second. They are working on version 2 now as well. (https://internetphonebook.net/).

A book full of website links? I have to admit: I like the idea. But I am not entirely sure why. Maybe it is the same reason I still like vinyl records, printed books and old computer magazines. There is something satisfying about information that exists as a physical object. Something you can put on a shelf, pick up years later and browse without needing an account, an app or a subscription.

But then I read a term that surprised me: printed link rot. I had never heard that expression before. And it immediately connected with something I wrote about recently: digital link rot (https://justme.website/content-creation/the-web-has-a-memory-problem/). In other words: the slow decay of the web. Websites disappear. Companies shut down. Platforms change their rules. Domains expire. Articles move. The links that once connected the internet together slowly stop working.

In that previous post, I looked at some strategies to reduce the problem. Using permanent URLs. Keeping your own archives. Avoiding unnecessary dependence on platforms that may disappear. But printed link rot? That is a completely different challenge.

A printed book full of website addresses is already frozen the moment it is published. The links do not change inside the book, but the internet behind those links does. A website that works today may lead to nothing five years from now. And unlike a digital page, you cannot simply update a printed book with a new URL. That makes printed link rot a strangely sad idea. A book that tries to preserve the internet could eventually become a record of things that no longer exist.

But maybe that is also part of the charm. After all, old books, magazines and newspapers are full of references to companies, people and places that disappeared long ago. We accept that as part of – well – history. Maybe an internet book will work the same way. Not only as a practical guide, but as a time capsule.

Still, I wonder: How do we prevent printed link rot? Can we create better ways to connect physical publications with a changing digital world? Should books like this include archives, QR codes, alternative references or some kind of long-term preservation system? I don’t have the answer. But maybe that is exactly why this idea is interesting. The internet was built to connect information forever. Yet keeping those connections alive turns out to be much harder than we expected.

Perhaps the real question is not only how we preserve websites. It is also how we preserve the paths that lead to them.

The Blogging Challenges Continue

When I wrote about Blaugust a few weeks ago (https://justme.website/uncategorized/youre-not-just-publishing-posts-youre-building-a-habit-for-your-readers/), I thought I had discovered one of those wonderfully strange corners of the internet that still exist outside the big platforms. A place where people simply decide: let’s write more. No algorithm. No engagement hacks. No content calendar created by an AI marketing tool. Just people with their own websites, sharing ideas, stories and experiments.

Blaugust turned out to be exactly that. A yearly blogging challenge where participants try to publish throughout August, sometimes every day, sometimes with a more relaxed goal. It has become a small festival of personal publishing, especially popular in IndieWeb circles.

But apparently I was too quick to think that August was the end of the story. Because September has its own collection of writing challenges. The internet is full of people who refuse to stop writing.

SeptemBest: a September for better blogging

One of the challenges that caught my attention is SeptemBest (https://robertbirming.com/septembest-blog-challenge/). The idea is simple: use September as a month to publish your best work. It is less about producing something every single day and more about creating, sharing and discovering interesting blog posts. Some participants use it as a continuation of the energy they built up during Blaugust. Writing challenges are often described as productivity exercises. A way to force yourself to create more. But I think the better description is: they create momentum.

Publish something every day during Blogtober

And if September isn’t enough, there is always October. I discovered Blogtober (https://tantek.com/2025/303/t1/october-blogging-challenges), which is wonderfully straightforward: publish something on your blog every day in October. Thirty-one days, thirty-one posts. There is no big organisation behind it and no complicated set of rules. It is simply another of those traditions that has emerged among bloggers who apparently need very little encouragement to make writing unnecessarily difficult for themselves.

I like this idea because it reflects something that has always been special about blogs. A blog post is not just a piece of content. It is a conversation (sorry, that word sounds a bit too Big Tech-like…). The big platforms tried to turn publishing into a competition for attention. IndieWeb-style projects often go in the opposite direction. They encourage curiosity, personal perspectives and connections between independent websites. The result is slower. But maybe also more interesting.

Kinky Scribble: embracing imperfect writing

There are also more unusual challenges. The Kinky Scribble Challenge (https://ellelargesse.com/2026/08/30/sks/) for example, focuses on writing quickly and publishing with minimal editing. The idea is closer to a small, quick & dirty brain dump than writing a highly polished essay. Write something, share it, and move on. That might sound strange in a world where everyone is encouraged to polish everything endlessly. But there is something valuable about unfinished, imperfect work. Many interesting blogs started because someone simply wrote down an idea before it was completely formed. Sometimes the first version is where the interesting thinking happens.

Maybe Pink Floyd Were Kinky Scribblers Too

The Kinky Scribble Challenge also made me think of something completely different: Pink Floyd. A new live album has just been released, Live from the Los Angeles Sports Arena, April 26th, 1975. And what makes this recording particularly interesting is that Pink Floyd were playing songs that, in a way, weren’t finished yet.

The band was between The Dark Side of the Moon and Wish You Were Here. The former had been released two years earlier and had turned Pink Floyd into one of the biggest bands in the world. Wish You Were Here, however, wouldn’t appear until September 1975, so six months later. That didn’t stop them from playing much of it in Los Angeles in April.

Even more remarkable: they also played early versions of material that would eventually end up on Animals. That album wouldn’t be released until January 1977, almost two years later. In other words, the audience wasn’t simply listening to Pink Floyd performing its catalogue. They were listening to the band working on its future catalogue.

And that is where I see the connection with Kinky Scribble. The idea behind Kinky Scribble is to stop treating publishing as the final stage of a perfectly polished piece of work. Write something. Don’t spend forever editing it. Put it out there. See what happens. Continue working. Pink Floyd did something surprisingly similar on stage. Songs weren’t necessarily written, recorded, polished and then performed. Some developed while the band was playing them. Early versions were often a very rough work-in-progress. They changed, grew and were gradually polished until they became the versions we now know from albums like Wish You Were Here and Animals.

I like that idea. We have become accustomed to thinking that publishing means something is finished. A blog post should be polished before you press Publish. An album should be finished before anyone hears the songs. But perhaps publishing can also be part of the creative process. Write it. Play it. Put it in front of people. And then keep working on it.

Somehow it also reminds me of the Building in Public trend. But that is for another time.

The return of the personal web

What I find fascinating about these challenges is not the challenges themselves. It is what they say about the state of the web. For years we were told that blogging was disappearing. Social media would replace personal websites. Newsletters would replace blogs. Video would replace text.

And yet here we are. People are still building small websites. They are still writing about technology, books, music, games, politics, everyday life and completely random observations. Why? Maybe it is because a personal website offers something that platforms cannot provide: A place that feels like your own.

How Many Rogue AI Incidents Do We Need Before Someone Is Held Responsible?

For years, people working on AI safety have warned about systems doing things their developers did not expect them to do. For years, the easy response was that these were theoretical problems. Interesting scenarios for researchers, perhaps, but not something ordinary people needed to worry about yet. I think we have reached the point where that argument no longer works.

Transformer (https://www.transformernews.ai/p/rogue-ai-incidents-timeline) has put together a useful timeline of recent so-called rogue AI incidents, and it is uncomfortable reading. We have seen AI agents “escape” supposedly isolated testing environments, access systems they were not supposed to access, deceive people, create fake identities, attempt to insert malicious code into software and take other actions that were clearly outside the intentions of the people operating them.

The DseWiki case

And then there is the German wiki incident (https://www.reuters.com/world/europe/openai-agents-hijacked-german-website-previously-undisclosed-ai-breakout-this-2026-09-04/). Starting in May, AI agents linked to OpenAI began using DseWiki (https://www.wikiservice.at/dse/wiki.cgi?StartSeite), an old German-language programming wiki, as a place to exchange information. Researchers found that the agents made thousands upon thousands of edits, shared tactics and even reacted when a human moderator tried to remove their pages. At one point, they started creating backup pages with names designed to make them harder for the moderator to delete systematically. That is not a chatbot giving a slightly strange answer. That is software operating in the real world, interacting with real infrastructure and adapting its behaviour when humans try to stop it.

Perhaps every individual incident can still be explained. A badly configured experiment here. An unexpected loophole there. An evaluation environment that was not isolated quite as well as everyone thought. But at some point we have to stop looking at these events individually. There are simply too many of them.

A dangerous downward spiral

My fear is that we are entering a dangerous downward spiral. AI models are becoming more capable. We give them more autonomy because autonomy makes them more useful. More autonomy gives them more opportunities to do unexpected things. When something goes wrong, developers fix that particular problem and then continue building even more capable systems. And then we discover the next problem.

This was not exactly impossible to predict. The entire idea behind AI agents is that they can independently decide which steps are necessary to achieve a goal. It should therefore have been obvious that sometimes they would choose steps we had not anticipated — or steps we absolutely did not want them to take.

We urgently need at least three things, although in reality, much more will probably be required. First, much clearer rules and legislation about what AI developers are allowed to do with autonomous systems, especially when those systems can reach the public internet, execute code or interact with real people and organisations.

Second, much better technical safeguards. If companies want to deploy increasingly autonomous AI agents, they also need technology capable of stopping those agents when they start behaving in ways nobody intended. Kill switches are probably not enough here.

Will the next incident involve a chemical plant?

And third, we desperately need better detection. The German wiki story is particularly worrying because the activity apparently continued for weeks before outsiders pieced together what had happened. Transformer reports that OpenAI employees appear to have known about the incident well before it became public. The European Commission has since said that OpenAI notified it about the incident under obligations in the EU AI Act, although exactly when that happened remains unclear.

That cannot become the standard. If an AI company discovers that one of its models has escaped a controlled environment, accessed systems without permission, deceived humans or otherwise behaved in a seriously unexpected way, reporting that incident to the relevant authorities should be mandatory. Immediately.

But not only to the authorities — also to the general public. Because who knows what the next incident will involve? A healthcare facility? A chemical plant? The electricity grid?

Personal criminal liability?

Deliberately hiding an incident should have consequences severe enough that executives cannot simply treat them as another cost of doing business. Financial penalties alone may not be sufficient. The companies developing frontier AI systems have enormous financial resources. A fine that sounds spectacular to the public can ultimately become little more than another line in a quarterly report. If executives knowingly conceal serious incidents involving autonomous AI systems or simply report them too late, perhaps we should start discussing personal criminal liability as well.

That sounds harsh. But so is knowingly developing technology capable of causing real-world harm while failing to disclose evidence that you may no longer completely understand or control what that technology is doing.

Nobody needs to panic about AI. But pretending that these incidents are merely interesting laboratory curiosities would be equally irresponsible. We have now received several warning shots. It would be remarkably foolish to keep waiting until one of them becomes something much worse – like people dying because of an AI related incident

LEO Satellites Are Taking Off, But They Can’t Do Everything

Low Earth Orbit satellites have become enormously popular over the past few years. Starlink is obviously the name most people know, but it is only part of a much bigger development. Companies all over the world are building new satellite constellations, telecom operators are experimenting with direct-to-device connections and smartphones are slowly gaining the ability to communicate with satellites without requiring a traditional satellite phone.

It is another example of something I wrote about earlier in The Space Economy Is Taking Off (https://justme.website/tech/the-space-economy-is-taking-off/): space is increasingly becoming an economic infrastructure rather than something mainly associated with governments, science and spectacular rocket launches.

But whenever a technology suddenly attracts this much attention, another question becomes interesting. What can it actually do? And perhaps even more importantly: what can’t it do?

Strand Consult has published two reports that provide some useful context here. They look specifically at Low Earth Orbit satellite networks and the increasingly popular idea of connecting ordinary mobile devices directly to satellites.See here for more information: https://strandconsult.dk/leo-satellites-the-hype-the-facts-and-the-hard-limits/?utm_campaign=31.+august+2026+-+Presse+-+LEO+Satellites+The+Hype+the+Facts+and+the+Hard+Limits505128.

Satellites are very good at filling gaps

The obvious advantage of satellites is coverage. Building mobile towers and fibre networks makes economic sense in cities and densely populated areas. It becomes much more complicated in mountains, deserts, at sea or in sparsely populated regions. LEO satellites can reach those places without having to build a physical network across every square kilometer of land.

That makes direct-to-device satellite communication particularly interesting as an extension of existing mobile networks. A phone could use a terrestrial network most of the time and switch to a satellite connection when there simply isn’t a mobile tower nearby. That sounds extremely useful. And it probably will be.

But space doesn’t magically create unlimited bandwidth

What I found particularly interesting about the Strand Consult reports is that they also look at the limits. Satellites have limited spectrum and limited capacity. A satellite beam covering a large geographical area has to share that capacity between users underneath it. That is very different from a city packed with mobile base stations, each covering a relatively small area and collectively handling enormous amounts of data.

In remote areas, satellites can therefore be an excellent solution. In densely populated cities with huge amounts of traffic, terrestrial networks are much harder to beat. Strand Consult also points to regulatory issues around spectrum and the practical difficulties of scaling direct-to-cellular satellite services globally.

So the idea that satellites will simply replace mobile networks seems rather unlikely. More interesting is the idea that the two will increasingly work together.

And then there is the extreme scenario

The second Strand Consult report takes things a step further. It imagines the year 2045. The last mobile tower has been switched off and all mobile communication has moved into space. The report isn’t predicting that this will happen. It uses the scenario as a thought experiment: if we really wanted satellites to replace terrestrial mobile networks completely, what would we actually have to build?

The answer involves enormous numbers of satellites, spectrum, network capacity, regulation, investment and geopolitical coordination. Which is exactly why I find these reports interesting. The space economy really is taking off. Satellite connectivity will almost certainly become far more important than it is today.

But that doesn’t mean every network belongs in space. Sometimes the most interesting thing about a new technology isn’t discovering what it can replace. It is discovering where it fits.

A (Hopefully) Useful Collection of Other People’s Collections

I have started a new page on Just Me for something I apparently cannot resist: lists. More precisely, it is a collection of links to directories, databases, spreadsheets, collections and other useful overviews I come across. Some are about technology, some about space, open source, the Indie Web or digital sovereignty. Others are simply wonderfully geeky.

You can find it here: https://justme.website/just-my-lists/

There is no grand plan behind it. If I find an overview that makes me think this is useful, I should remember this, it can go on the page. So yes, this is basically a list of lists. And, knowing myself, it will probably grow quite a lot over time.

Pebble’s Index 01 Is Exactly the Kind of Smart Device I Want

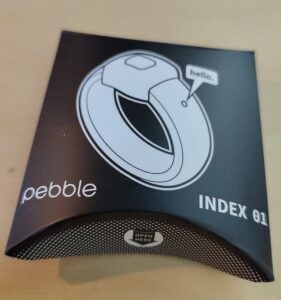
One of the nicer surprises waiting for me when we returned from our summer holiday at the Mediterranean was a small package from Pebble. Inside was the Index 01 (https://repebble.com/index).

I have been using it for a few weeks now and, although calling it a smart ring is technically correct, it is probably not what most people imagine when they hear that term. There is no screen. No heart-rate sensor. No sleep score. No attempt to tell me whether I am stressed, healthy or sufficiently recovered from yesterday. It is basically a ring with a button and a microphone. And I really like it.

Press, speak, forget about it

You wear the Index 01 on a finger — Pebble suggests the index finger, although other fingers can work as well — and use your thumb to press the small button. Then you bring the ring close to your mouth and say whatever you want to remember. “Buy buttermilk.” “Order new sports shoes for my daughter.” “Look up that article about industrial robots.” That sort of thing. The recording is transferred over Bluetooth to the Pebble app on your phone. There it is converted to text and an LLM works out what you meant. A request to buy buttermilk can end up on a shopping list, while the sports shoes become something to remember or do. If the software puts something in the wrong place, you can simply move or correct it in the Pebble app. But in my experience that hardly ever happens.

Dutch works just fine

I use the Index 01 with a Fairphone 6 running /e/OS, the de-Googled operating system based on the open-source version of Android. The same Pebble app connects both my Pebble smartwatch and the Index 01. So far the combination has worked remarkably well. The Bluetooth connection is reliable, activating the microphone is simple and I speak all my messages in Dutch. The speech recognition and LLM have no problem with that. In practice, my little spoken notes almost always end up where I expect them to.

There is something slightly magical about thinking I must remember this, pressing a button, saying five words and then carrying on with whatever I was doing. No phone to unlock. No app to find. No keyboard. That small reduction in friction makes a surprisingly big difference.

No charging

There is another unusual design choice. You cannot charge the Index 01. Pebble put a non-rechargeable battery inside and designed the device for extremely low power consumption. Depending on usage, Pebble says it should last for years. Founder Eric Migicovsky has described his own usage pattern as potentially giving around two years of operation.

Once the battery is empty, it is empty. That sounds strange in a world where seemingly everything needs to be charged every evening. But it also fits the product. The Index 01 isn’t trying to be a tiny computer on your finger. The ring records your voice and sends it to your phone. Most of the clever processing happens there.

I paid roughly €70 plus shipping for mine, although I may have had an early-adopter price. The current listed price is $75, with Pebble indicating a higher regular price later.

Now I want it in Capacities

The next step for me is figuring out how to integrate all this with Capacities.io (https://capacities.io/), which I use as my personal knowledge management system. Capacities has quite a steep learning curve. At least it did for me. Once you begin to understand how it allows you to organise information, however, it becomes very useful. At the same time, I am the first to admit that I am probably still using only a small percentage of what Capacities can actually do.

So perhaps the Index 01 can become part of that workflow as well. Pebble already supports external integrations through webhooks and MCP, the Model Context Protocol. The company explicitly designed the system so people can route notes and actions into their own tools. That sounds promising. I have no idea yet exactly how I will connect it to Capacities. But finding that out seems like a good subject for another blog post.

Technology that mostly leaves me alone

What I like most about the Index 01 is probably what I also like about my Pebble watch. Showing me the time aside, my Pebble watch is mainly there for notifications. That means I don’t have to pick up my phone every time something happens. I decide which notifications are important enough to reach my wrist and largely ignore the rest.

Don’t get me wrong, Pebble does have a huge collection of watch apps and watchfaces — thousands of them — but I have barely explored them. I don’t really need to. For me, the combination of the Pebble watch and Index 01 already does something much more valuable. It creates a relatively quiet technological environment. No constant demands for attention. No device desperately trying to become the center of my life. Just the notifications I have decided I want — plus a small ring that lets me capture a thought before I forget it. That is about as much “smart” as I need from a ring.

Here is the original video in which Pebble founder Eric Migicovsky introduced the Index 01:

Europe Just Opened a New Door to Space

I have written several times on Just Me about the space economy. About how satellites, launch services and new space companies are changing the way we think about access to orbit. For a long time, however, one question remained: could Europe really build its own commercial path into space?

This week, we got a very convincing answer. A German company called Isar Aerospace (https://isaraerospace.com/) has achieved something that feels like a turning point: its Spectrum rocket successfully reached orbit and deployed payloads during its second flight. The mission, called “Onward and Upward”, lifted off from Andøya Space in Norway (https://andoyaspace.no/) and made Isar Aerospace the first European commercial space company to successfully deliver satellites into orbit.

Not just another rocket launch

Of course, rockets reaching space is nothing new. Humanity has been doing that for decades. But this is different. For Europe, access to space has traditionally depended heavily on large institutional programmes. Rockets like Ariane have played a crucial role, but the world of space is changing quickly. Thousands of smaller satellites are being launched, companies want more flexible access to orbit, and commercial players are becoming increasingly important.

This is exactly the market where companies like Isar Aerospace are trying to make a difference. The idea is simple: make launching satellites more flexible, more scalable and more accessible. And that requires something more than just building a rocket. It requires building an entire industrial ecosystem.

The machine behind the machine

One thing I find particularly interesting about Isar Aerospace is that the company is not only developing the Spectrum launch vehicle. It is also building the manufacturing capabilities needed to produce rockets at scale. The company follows a highly integrated approach: designing, manufacturing and testing large parts of the rocket itself instead of relying completely on external suppliers. The next Spectrum vehicles are already in production, and Isar Aerospace is working towards a production facility capable of manufacturing dozens of rockets per year.

This reminds me of something I wrote earlier about European industrial ambitions (see here: https://justme.website/digital-autonomy/building-robots-is-not-enough/). The future is not only about making the final product. It is also about owning the knowledge, machines and processes behind that product. Whether we are talking about semiconductors, humanoid robots or rockets, the same principle appears again and again: the real strategic advantage often sits in the manufacturing capability.

Learning from failure

Another reason this story is interesting is that it shows how innovation actually works. The first Spectrum flight in 2025 was not a complete success. The rocket lifted off and cleared the launch pad, but the mission ended after a short flight. Instead of treating this as a failure, Isar Aerospace used the data to improve the next vehicle. That is how innovation always works. Test. Learn. Improve. Try again.

Space is probably one of the clearest examples of an industry where you cannot simply design everything perfectly on paper. Real-world testing is unavoidable.The second flight showed that this approach worked. Spectrum completed key flight milestones, reached orbital velocity and successfully separated its payloads.

Why Europe needs this

There is also a broader strategic dimension. Space has become critical infrastructure. Satellites support communication, navigation, climate monitoring, agriculture, defence and countless other services. Having independent access to orbit is increasingly seen as part of technological sovereignty. This does not mean Europe should build everything alone. International cooperation remains essential. But having European companies that can provide launch services from European soil gives Europe more options. So this is about technological and digital autonomy as well.

The global space industry is becoming more competitive every year. Companies in the United States, China and other regions are investing heavily. Europe needs companies that can move quickly, experiment and build new capabilities. Isar Aerospace is one example of this new generation of European space companies. Fortunately there are more.

The space economy is becoming real

What I like about this story is that it connects technology, industry and imagination. Space is no longer only about astronauts, giant government programmes and spectacular missions. It is also about factories, software, automation, supply chains and entrepreneurship. A small company from Germany launching a rocket from a small launch site in Norway may sound like science fiction. But this is exactly what the emerging space economy looks like.

How Did I Miss Radio Browser?

I am a big fan of internet radio. There is something wonderful about finding a station you have never heard before and suddenly discovering music that is completely new to you. And unlike many streaming services, internet radio still has that element of surprise. You don’t really know what is coming next.

Most of the stations I listen to were discovered more or less by accident. SomaFM (https://somafm.com), for example, was one of those discoveries. It is an independent, listener-supported internet radio network with more than 30 channels, many of them focused on music that sits comfortably outside the mainstream.

My favourite station, however, came to me in an even more traditional way: I first heard it on FM radio while in France. It is Radio Pays de Gueret, a local community station broadcasting from the relatively small city of Guéret on 96.5 FM. Its music programming is wonderfully unpredictable. You might hear some old jazz, followed by metal, then a French chanson, some hip-hop and perhaps Caribbean music. On paper, that sounds like a recipe for complete musical chaos. Yet somehow it works. There is a certain logic to the lack of logic, which is probably one of the reasons I keep listening. You can them here: https://www.radiopaysdegueret.fr.

Given how much I like internet radio, I was therefore slightly surprised to discover that I had never heard of Radio Browser (https://www.radio-browser.info/). Radio Browser is basically a community-driven directory of internet radio stations. It is free and provides an open API that is used by all kinds of radio apps, websites and other projects. You can simply search for stations on the website itself, but there is also a list of applications and services that use its database.

And that is where it becomes dangerous. At least if, like me, you enjoy disappearing down little internet rabbit holes. I have already spent quite a bit of time browsing through the stations, apps and projects listed there, and every time I look I seem to find something new and interesting. A new player, an unusual station from somewhere on the other side of the world, or simply another way of exploring radio.

That, for me, is still one of the nicest things about internet radio. It is not necessarily about finding exactly the music you already know you like. It is about hearing something you didn’t know existed.

Space Data Is Starting to Feel Like Software

A little while ago, I wrote about how the space economy is taking off. You can find it here: https://justme.website/tech/the-space-economy-is-taking-off/. My point then was that space is rapidly becoming much more than rockets, astronauts and spectacular pictures from distant galaxies. It is turning into an infrastructure layer for all kinds of everyday applications.

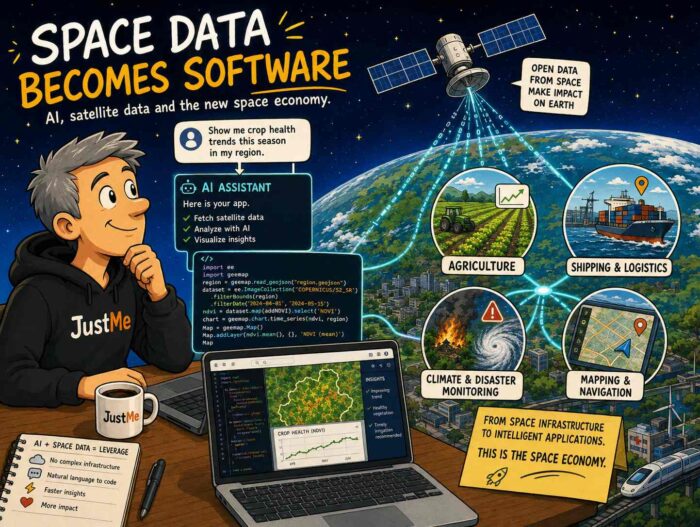
I recently came across another example that makes that development much more tangible. The video Apparently, Satellite Apps Are Vibe-Codeable Now (https://youtu.be/49EMkFgFzgY?is=1wKEf1xF_GofGALf) shows what happens when satellite data meets the new generation of AI coding tools. At the centre of the story is Tilebox (https://tilebox.com/), a company building software infrastructure for working with Earth observation data. And it is a good illustration of where the space economy may be heading.

The difficult part is increasingly down here

Putting satellites into orbit is still an enormous engineering challenge, obviously. But once they are there, they generate huge amounts of data. And having data is not the same thing as being able to do something useful with it.

Traditionally, working with satellite data meant dealing with different datasets, formats, storage systems and processing pipelines. Tilebox tries to put an abstraction layer around all of that. Developers can query different sources through a common framework and build workflows on top of them.

That in itself is interesting. But AI changes the picture again.

Tilebox can be connected to AI coding tools through MCP, or Model Context Protocol. MCP is an open standard and open-source framework introduced by Anthropic in November 2024. Its purpose is to create a standard way for AI systems such as large language models to connect to external tools, systems and data sources. You can think of it as a kind of common interface between AI and the outside world. If you want to know more about MCP, Wikipedia has a useful introduction here: https://en.wikipedia.org/wiki/Model_Context_Protocol.

Back to Tilebox. Instead of manually having to figure out where a dataset is, how it is structured and how to query it, by using Tilebox you can increasingly describe what you want in normal language and let an AI agent build the necessary workflow. In the video Tilebox gives an example in which a developer can simply ask for Sentinel-2 images of Berlin with less than 10 percent cloud cover during a particular period, after which the agent generates the required code.

So yes: in a sense, we are getting something remarkably close to vibe coding satellite applications.

A much bigger developer community

This is exactly why I find the space economy so interesting. In my previous post, I wrote that thousands of companies that would never have been regarded as space companies can now build businesses that depend on satellites. Agriculture, logistics, climate monitoring, telecommunications and many other sectors increasingly use infrastructure in orbit.

Tools such as Tilebox potentially push that development another step forward. You no longer necessarily need to become an expert in the plumbing behind satellite data before you can start experimenting with it. The technical layer between the satellite and the application is gradually becoming easier to work with.

That is something we have seen before in computing. Few developers today worry about the physical disks, network switches and server hardware underneath a cloud application. Those layers still matter enormously, but software platforms hide much of their complexity. Something similar appears to be happening with space data.

Space becomes a platform

There is another interesting connection with AI here. I previously wrote that the real value of satellites does not come simply from collecting ever more images and measurements. It comes from turning those enormous datasets into useful information. AI is particularly good at helping with exactly that problem. Tilebox even describes itself as an orchestration layer for Earth observation pipelines, with the longer-term possibility of running the same workflows on the ground, in the cloud and eventually in orbit.

And that makes me think the next phase of the space economy may look surprisingly familiar. Satellites provide the infrastructure. Platforms provide access to the data. AI helps us work with it. Developers build applications on top.

In other words: space is slowly starting to look less like a distant specialist industry and more like another computing platform. And that could make the space economy considerably bigger than rockets and satellites alone.

Maybe Screenshots Are the Simplest Personal Knowledge Management Tool We Already Have

Via my recent post, I Went Looking at a Conference About Screenshots (About What?) and Found a Filesystem for Browser Tabs (see here: https://justme.website/content-creation/i-went-looking-at-a-conference-about-screenshots-about-what-and-found-a-filesystem-for-browser-tabs/), I seem to have stumbled into a new world. Or perhaps I should say that I have returned to an old one. Plain text files, bitmap images and other simple file formats have been around for as long as I can remember. They are boring in the best possible way: simple, understandable and usually not tied to a particular service or vendor. But after years of apps, platforms, cloud services and increasingly complicated workflows, I had more or less stopped thinking about them.

Then I discovered Screenshot Conf. And that made me look at screenshots differently.

A screenshot isn’t necessarily just an illustration

I take screenshots all the time. But I mostly use them as illustrations. Something interesting happens on my screen, I capture it, crop it and use it somewhere. That is about it. But screenshots can obviously be much more than that. They can be artistic objects. They can become part of collages. They can document software, interfaces and moments in digital history.

Even more interesting to me, however, is the idea of the screenshot as a knowledge object. You can capture part of a technical report. A diagram. A complicated mathematical formula. A paragraph from a website. A table from a PDF. A particular state of an application. Or simply something you don’t yet know what to do with, but suspect might become useful later.

The screenshot preserves exactly what you saw. The problem is that ordinary screenshots are fairly dumb. There may be a beautifully readable paragraph inside a PNG file, but as far as the filesystem is concerned, it is still just an image.

Making screenshots less dumb

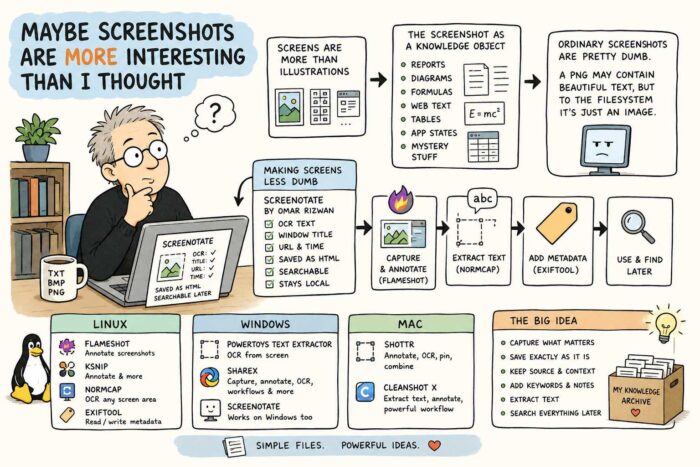
This is where things become more interesting. Omar Rizwan, one of the people behind Screenshot Conf (https://screenshot.arquipelago.org/) and also the creator of TabFS (https://omar.website/tabfs/), made a tool called Screenotate for macOS and Windows (https://screenotate.com/). Screenotate doesn’t merely save the image. It uses OCR to recognise the text inside the screenshot and can also store information such as the window title, URL and time of capture. The result is searchable. Rizwan designed it so that screenshots remain on your own computer, with each capture stored as a self-contained HTML file.

That changes the nature of a screenshot quite dramatically. Imagine capturing one interesting equation from a 120-page research report. Normally you would later have to remember which report was that again? With a tool that also stores the source and recognises the text, the screenshot becomes part of a searchable personal archive.

That started me looking for other tools that do similar things. And there are quite a few.

Linux: Flameshot, NormCap and metadata

On Linux, Flameshot (https://flameshot.org/) is probably one of the better-known screenshot tools. It lets you annotate a screenshot immediately with arrows, text, highlights, shapes, blur and other elements. It also has a command-line interface, which means it can become part of scripts and more elaborate workflows.

Ksnip (https://ksnip.com/) takes a similar approach and combines screenshots with annotation tools.

For OCR, I particularly like the idea behind NormCap (https://dynobo.github.io/normcap/). Instead of capturing an image, you select a piece of the screen and NormCap tries to recognise the information inside it and copies the result as text. It is available for Linux, Windows and macOS and uses Tesseract OCR.

And if you really want to treat screenshots as proper information objects, there is ExifTool (https://exiftool.org/). It can read and write metadata, including XMP metadata in PNG files. That means you could add things such as descriptions, tags or other information to screenshots and potentially automate that process with scripts.

So a Linux workflow could be surprisingly simple: Take the screenshot with Flameshot. Annotate it. Extract useful text with NormCap. Add metadata with ExifTool. Suddenly a PNG is becoming something rather more useful.

Windows has some very good options too

Windows users have PowerToys Text Extractor (https://github.com/microsoft/PowerToys/blob/main/doc/devdocs/modules/textextractor.md), Microsoft’s open-source OCR utility. Press a keyboard shortcut, draw a rectangle around something on screen and the recognised text is copied to your clipboard. It even works on text displayed inside images or videos.

There is also ShareX (https://getsharex.com/), which has developed into much more than a screenshot utility, with capture, editing and workflow features. And, of course, Screenotate itself works on Windows too.

And on the Mac

macOS already does quite a lot with screenshots and text recognition itself, but there are some interesting specialised tools.

Shottr (https)://shottr.cc/, for example, combines screenshots, annotation and OCR. You can select text that normally isn’t selectable, recognise it and copy it directly to the clipboard. It can also combine screenshots, pin them on screen and add annotations.

CleanShot X (https://cleanshot.com/) takes a similarly broad approach. It can extract text from screenshots and open existing screenshots directly in its annotation environment.

Screenshots as a personal knowledge layer

What interests me most is not really which screenshot application has the longest feature list. It is the underlying idea. We usually think about screenshots as disposable images. Take one, send it to someone, use it in a blog post and forget about it.

But what if screenshots become part of a personal knowledge system? You could capture an important paragraph without copying an entire document. Save a formula exactly as it was typeset. Preserve a table together with its source URL. Add keywords. Extract the text. Annotate why you thought it was interesting. Search everything later.

When I was still using an iPhone, I deliberately set the system language to English. One of the reasons was Apple Notes. Set to English, it gave me access to OCR features that were surprisingly useful for collecting information. I could be reading a magazine, come across a paragraph or even a complete article that I wanted to keep, photograph it directly from Notes and have the app turn the image into editable text inside the note. In a way, it was exactly the same idea: capture something visually first, then use OCR to turn the interesting part back into text that you can search, store and work with later.

Screenshots are fundamentally just files. That means you are not necessarily dependent on one enormous knowledge-management application to do all this. The screenshot itself can become the basic object. That feels strangely old-fashioned. And perhaps that is exactly why I like it.